Loading activity…

@arankomatsuzaki
Sharing AI research. Early work on AI (GPT-J, scaling, MoE). Ex ML PhD (GT) & Google.
 AI
A user exploring the idea asks whether anyone is interested in cofounding or knows someone who might be.
AI
One commenter says AI mostly helped with rewording; their feed split between “unreadable slop” and praise.
AI
A post describes a benchmark testing nine frontier agents on 15 open scientific follow-up problems developed with domain scientists.
AI
Quoting a post captioned 'recession indicator,' a user said it explained what was exciting about GLM 5.3 Flash fine-tune.

AI
A post links to a photo without offering any explanation beyond 'hmm.'

AI
A post claims a more than 100-fold question-answering speedup for VideoJev versus Thinking.
AI
A post describes stage-by-stage checks that send a failed tablecloth grasp back to repositioning.

AI
A post claims ARC achieves more than 5× higher success on reasoning-heavy tasks without changing the model architecture.

AI
The ARC project says it adds action-grounded reasoning to existing models without new robot demonstrations or foundation-scale training.

AI
A user floats buying a few hundred robots in India for companies to run real-world tests.
AI
Partiful’s listing invites researchers, engineers and innovators to commemorate mathematics and discuss scaling laws.
AI
A post introducing the report claims three years of data support its argument about AI and creativity.
AI
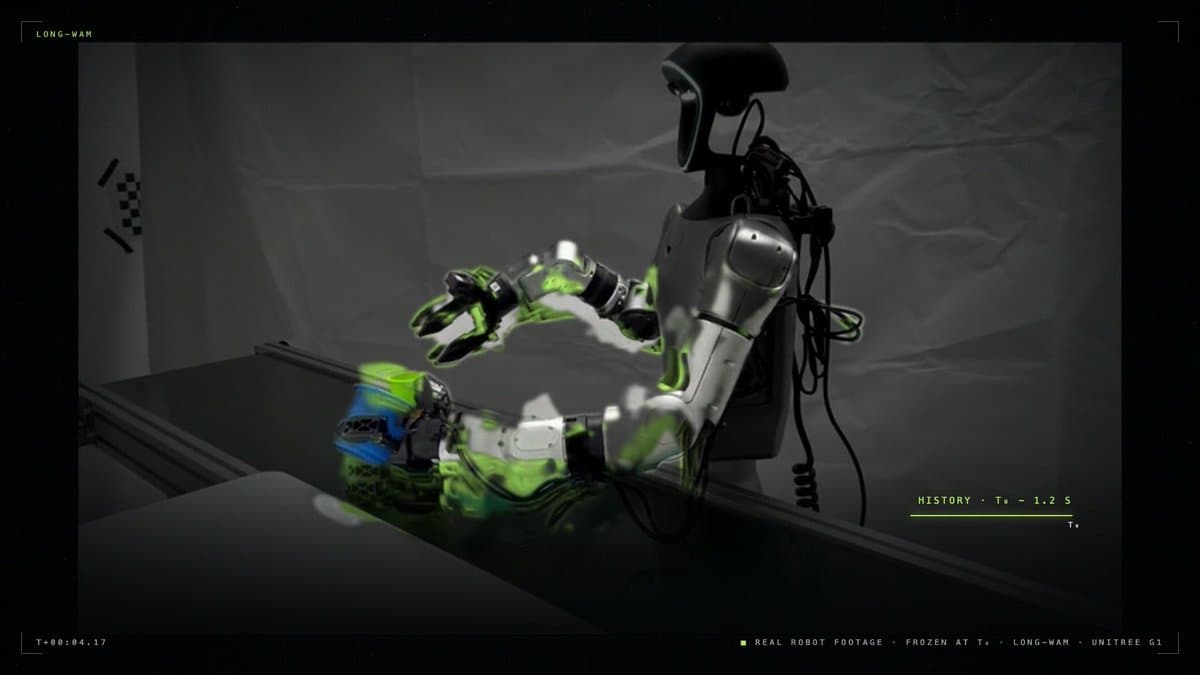
A post says success on RoboCasa GR-1 rose from 63.3% to 78.7% as context grew from 0.0 to 19.2 seconds.
AI
A post describes an 8B-parameter RoboJEPA model from Meta’s FAIR and Mila, trained on 15,022 hours of robot video.

AI
The Workhorse team says it studies how to teach whole-body movement and object handling from human demonstrations, without teleoperation.

AI
In posts describing new research, the authors say some base models recovered much of reinforcement learning’s reasoning gain when prompted with model-specific “token cues,” and they say the work also includes a safety case study on refusal and compliance.

AI
A user says an unspecified element pops up 30 minutes after they close it, no matter how many times they try.

AI
A post about the project claims a 65% score gain with the same compute on a 24-hour multi-repository agent-swarm task.

AI
A user invites researchers using GPT 6 Astra for robotic control or agentic real2sim to request free tokens for testing Kimi K3 and Qwen 3.8 Flash Next as comparisons.
AI
A post attributes the proposal to Meta's team and reports Qwen3-8B average accuracy rising from 30.76% to 65.97%.