Loading activity…

@samsja19
leading research at @PrimeIntellect
 AI
PrimeIntellect also claims up to 34% faster hosted training with prime-rl in tests on two Qwen3 models.
 X
AI
A post says the OpenRouter figure represents just a small portion of Prime Inference.

AI
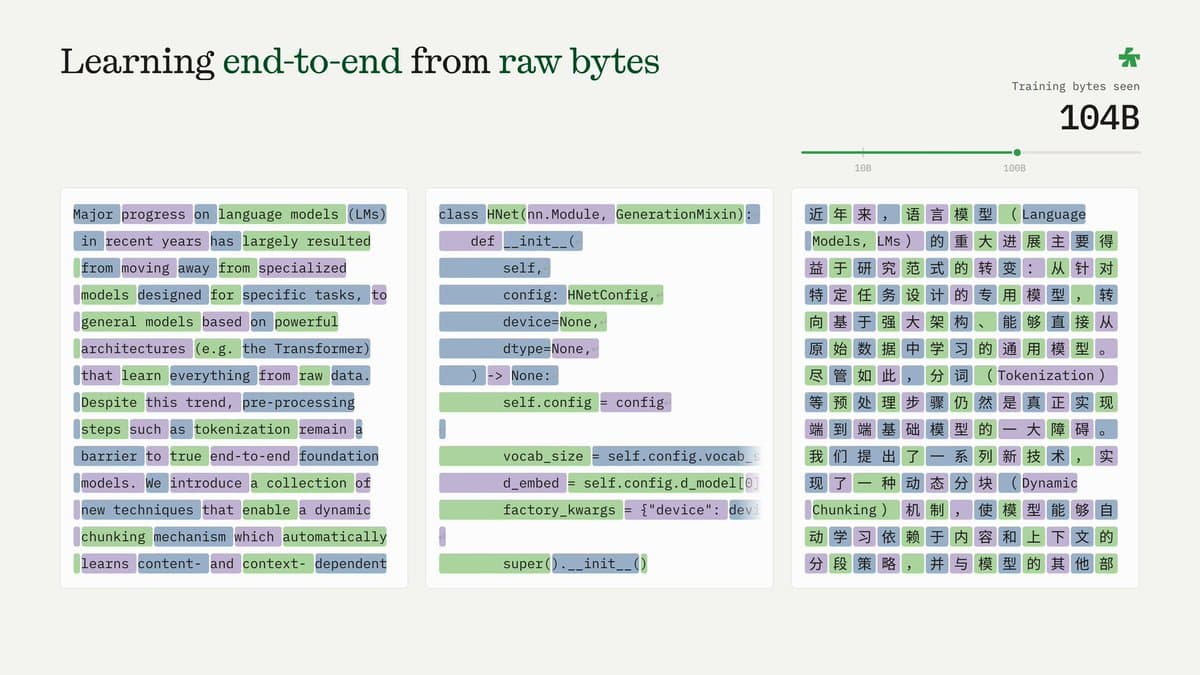
Unlike models with fixed tokenizers, H-Net learns to group raw bytes within the model, Cartesia says.
 X
AI
Mirendil says Lor's agents write its code, run experiments and iterate on results for days.

AI
Thom Wolf describes an open collection of more than 120 publicly reported AI-model misbehavior incidents.

AI
The announcement calls the addition stable; a September post says it targets instability when training and sampling policies differ.

AI
A contributor says the merged approach will become Prime-RL’s default algorithm in the next release.

AI
Hugging Face Bio reports a 66.7% average across five DNA benchmarks, against 67.5% for GPT-6.1 Sol.
 X
AI
DeepSeek says the model is live on its website, app and API, and optimized for DeepSeekHarness and Tencent CodeBuddy.

AI
A user jokes about checking your floating-point number too, but says looking at the data matters most.
AI
Prime Intellect says it is bringing Moondream’s open vision models and inference optimizations into its stack.
 X
AI
A user calls something “the future of coding agents” but does not identify what they mean.

AI
PrimeIntellect says the rewrite reaches usable input about 13 times faster and uses 83% less startup memory than before.

AI
A post asks people convinced LLMs interpolate rather than extrapolate for their perspective on AlphaZero.
AI
Mistral says Mistral Large 4 is live via API in public preview now, with open weights due at the end of October. Reuters says the launch is part of Mistral’s push to narrow the gap with leading Chinese open-weight models.

AI
Prime Intellect announced Prime Inference as a service with serverless endpoints and reserved capacity for frontier open-source models, alongside self-reported scale and performance claims.

AI
Arthur Douillard describes work since March to scale reinforcement learning for Gemini, with bug fixes, improvements and more still to build.

AI
A user praises a team and congratulates Calvin Chen.

AI
One post doubts SpaceXAI was at 10% model FLOPs utilization (MFU), a measure of compute efficiency. A reply treats that level as a waste of money.
AI
Defazio said in his September 26, 2026, announcement that he had moved to San Francisco for the role.


