14 stories tagged by Digg
 AI
A blogger says Jev’s results on reasoning-intensive regression problems were within expectations. They describe Jev as focused on classification and call it “wicked fast.”
AI
A user says Jev can’t answer with text and handles only fairly narrow questions, despite its claimed cost and speed advantages.
 Technology
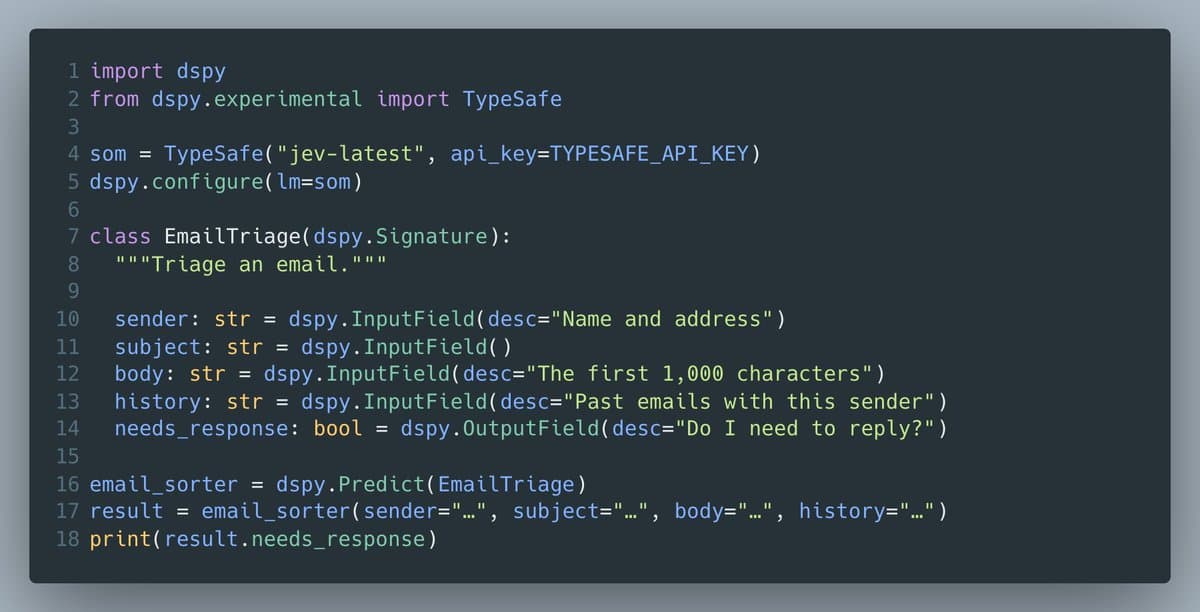
VentureBeat describes Jev as an alternative to generating text for routine decisions, using classification techniques with modern pretrained models.
AI
EmergentMind describes a paper testing JEV, a rubric judge that returns probabilities over fixed answers instead of generating text. The post says that when JEV makes a confident error, commercial LLM judges make the exact same mistake 96% of the time.

AI
A user says open source cloned Jev in less than a week. They say the clone uses the same API format, so switching to it just requires swapping the URL.

AI
An a16z post shares TypeSafe AI's Diogo Almeida's argument that AI output written for people is hard for software to use. It describes Jev as choosing from a set of options and assigning each a confidence level.

Technology
TypeSafe AI has launched Jev, a model Diogo Almeida describes as software-native rather than chat-first, built to turn natural language into structured choices with confidence scores.
AI
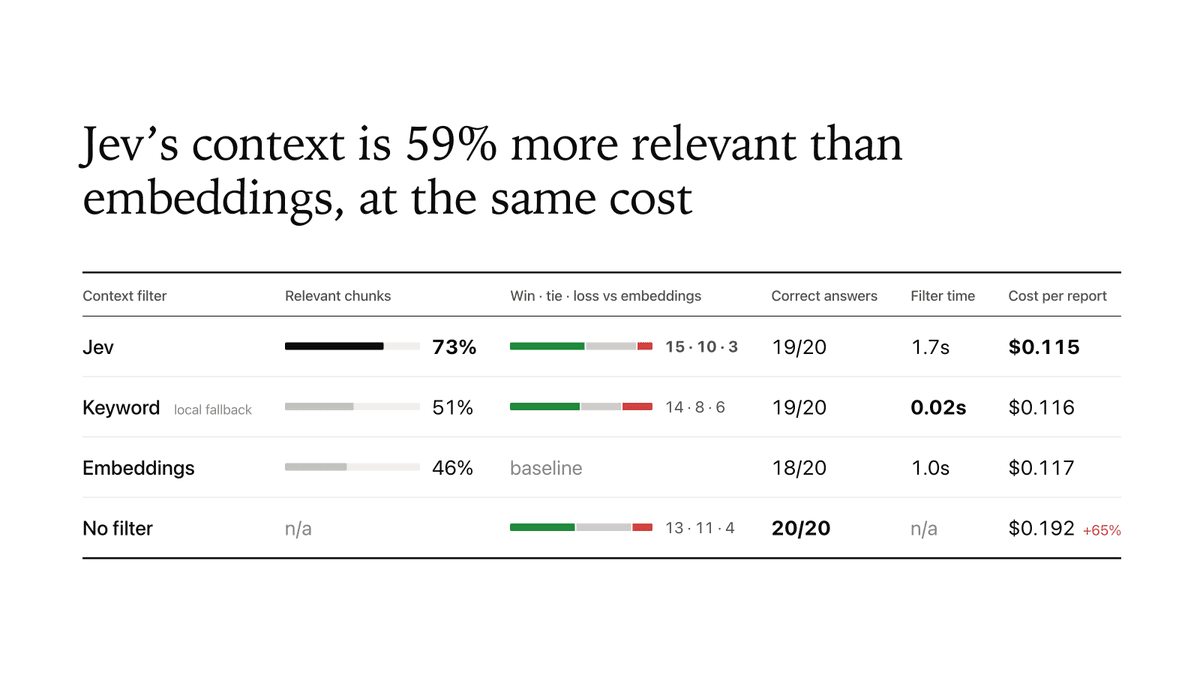
A September 28 post announcing the change says Jev yielded 73% relevant context versus 46% for embeddings in tests on 28 research tasks, at the same cost per report.
AI
A user says they collected thousands of reviews with Apify, then used Jev to classify them against criteria they care about.

AI
A user says JEV entered “limited early access” on September 15 and counts 29 arXiv papers about it by September 28. They call the pace “not healthy.”
AI
Typesafeai announced on September 27 that Jev was back with increased capacity and open signups. A post quoting the announcement said free credits had been temporarily disabled for new users.
AI
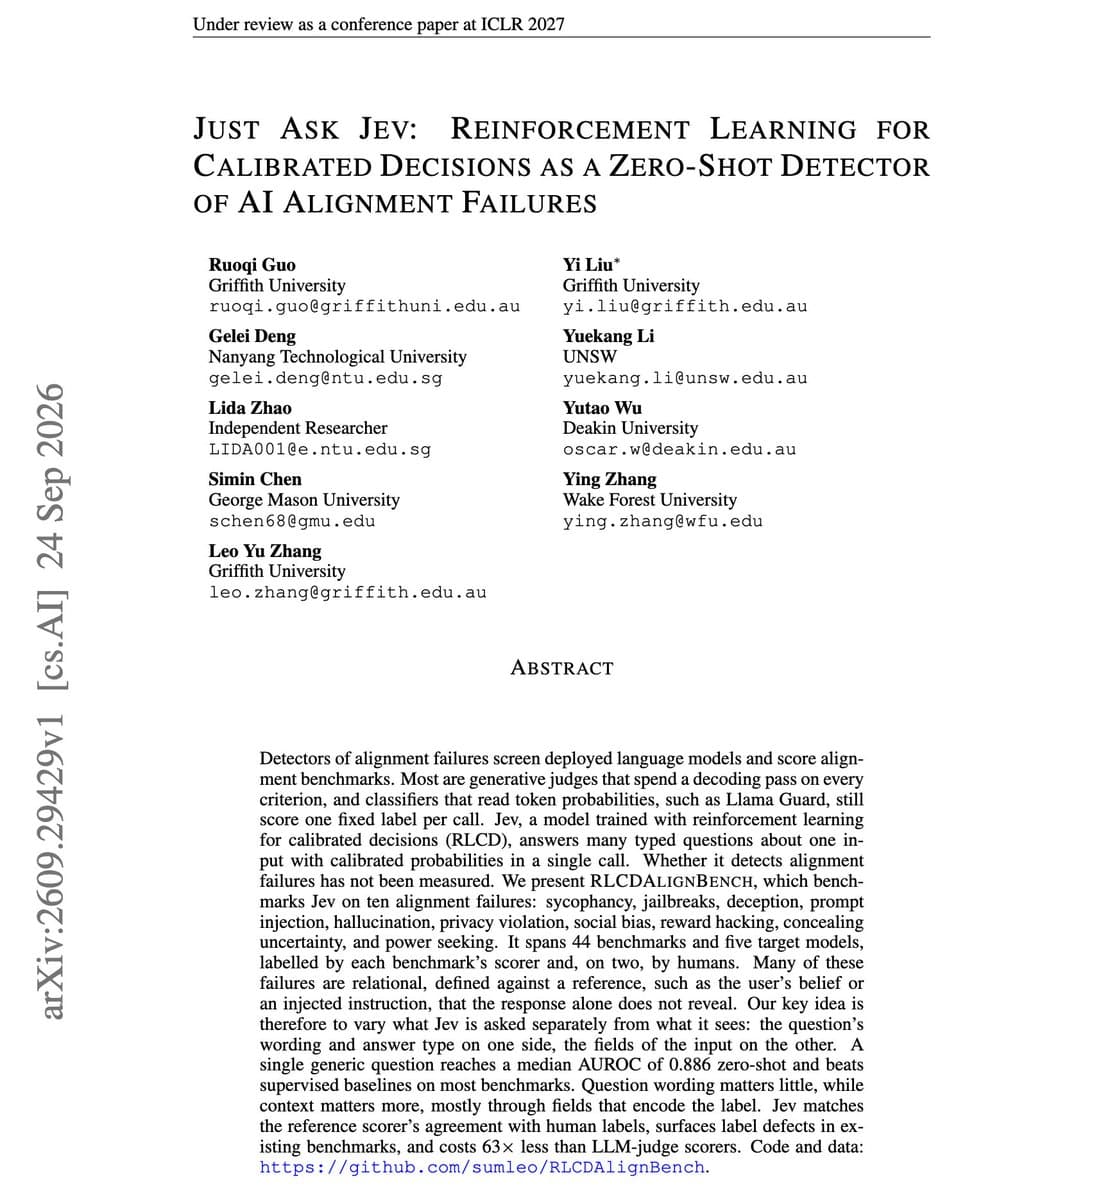
A post describing the paper says TypeSafe AI's Jev scores a model response using the probability of its answer to one generic yes/no question. Without extra training, the score had a median AUROC of 0.886.
AI
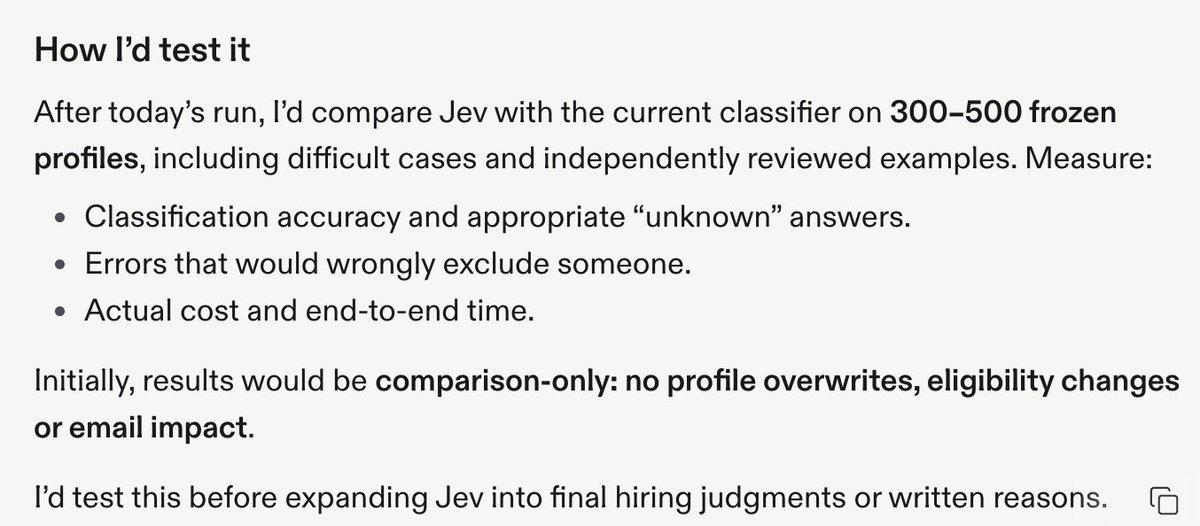
Every reports that the filter’s first version flagged every newsletter as urgent. Its creator revised the criteria to ask who wrote an email, whether someone he knew was waiting on him, and what ignoring it might cost.

AI
The release announcement also introduces ReAnchor, a new optimizer described as specifically for calibrating outputs with confidence.