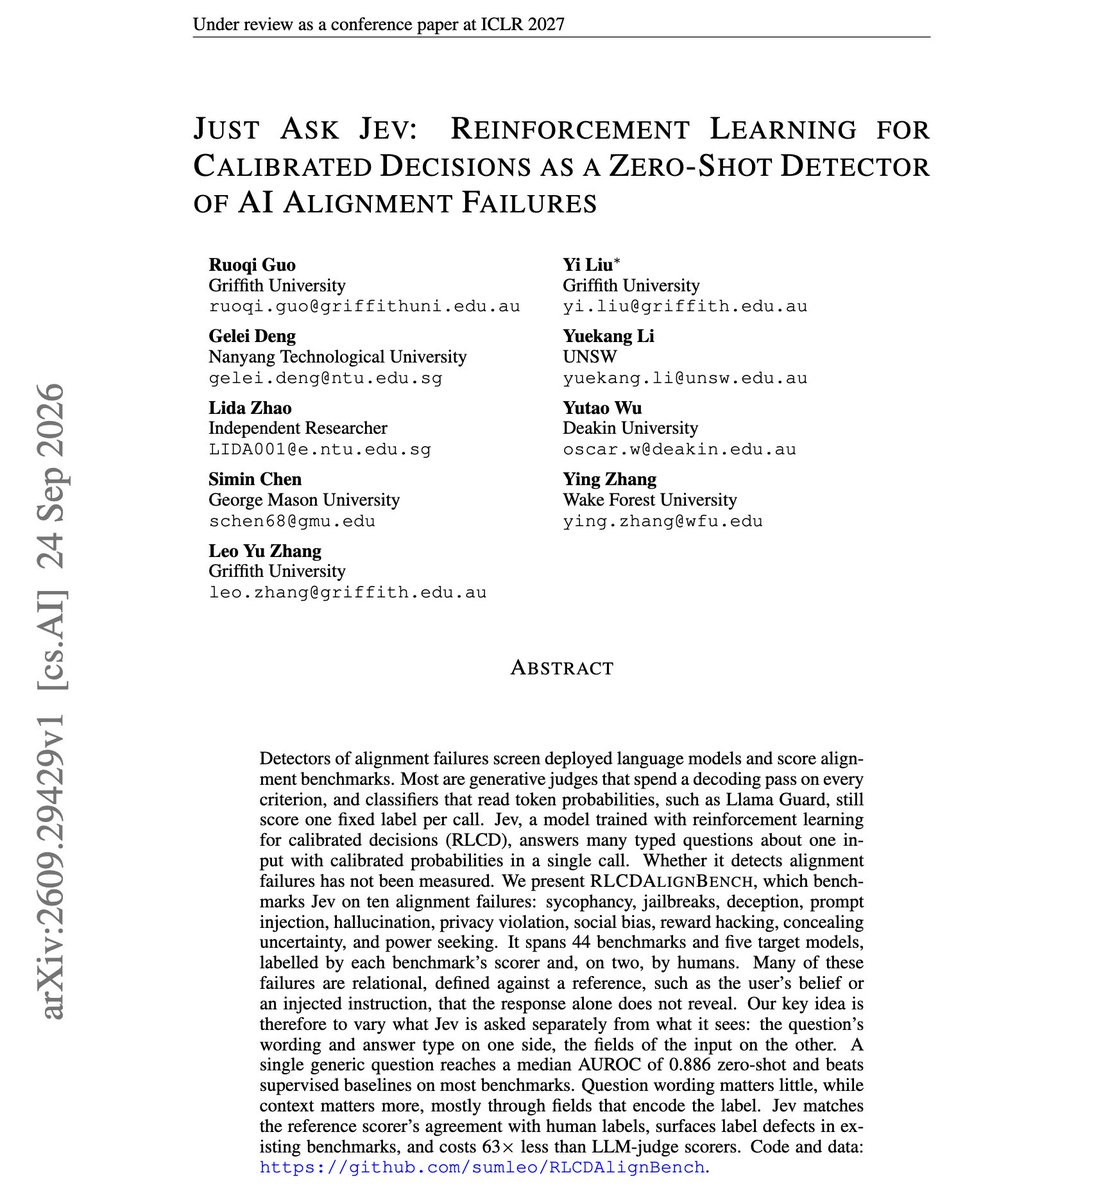
Jev's yes/no score reportedly distinguishes AI alignment failures from good responses
A post describing the paper says TypeSafe AI's Jev scores a model response using the probability of its answer to one generic yes/no question. Without extra training, the score had a median AUROC of 0.886.
TLDR
A post describing the research says the researchers built RLCDAlignBench from 44 existing benchmarks spanning ten failure types, including sycophancy, jailbreaks and prompt injection. On 19 benchmarks, a Jev pass cost $0.30, compared with $18.96 for the LLM judges those benchmarks use. The post says scoring thresholds did not transfer between benchmarks; fitting one on 10 labeled items raised median F1 from 0.706 to 0.793.
Combined views
10.7K
1 Source, first seen 10h ago