Report
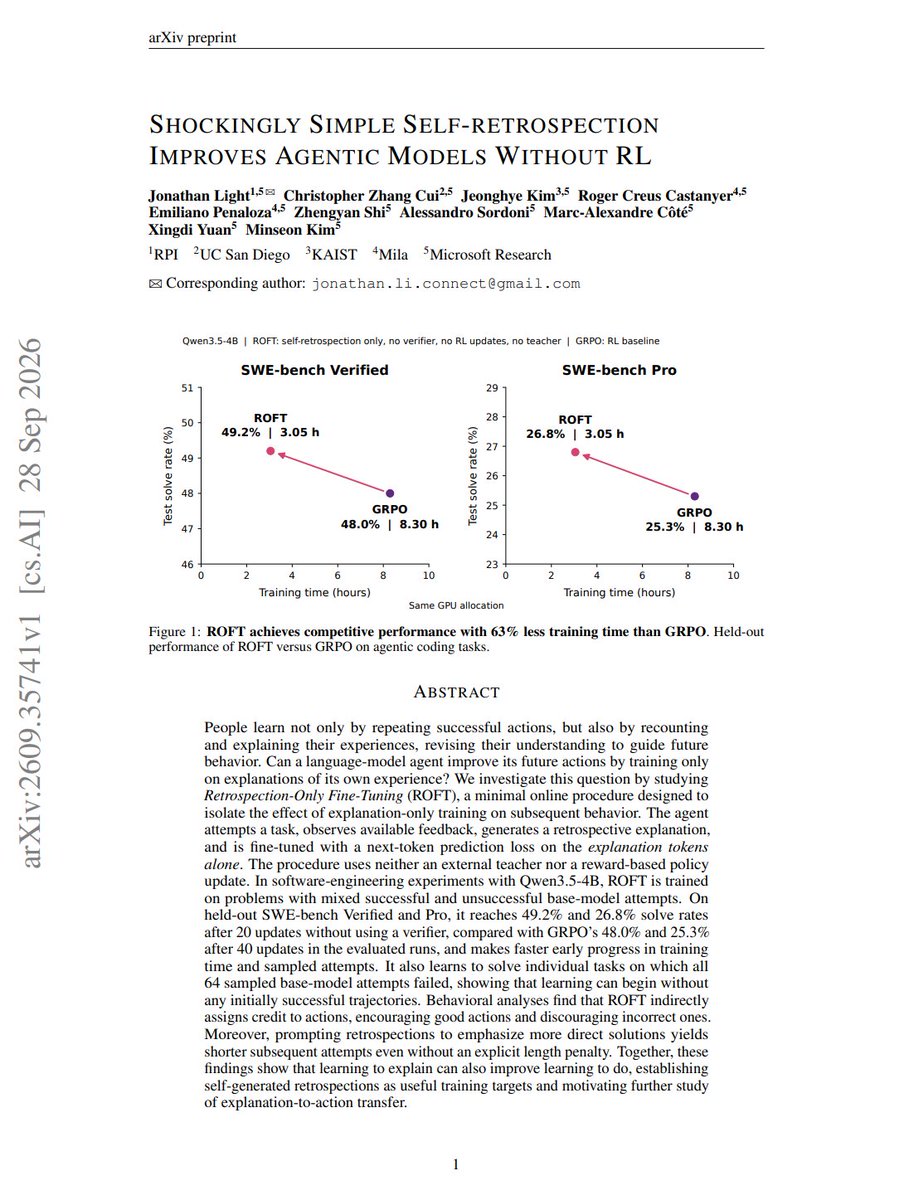
Can language-model agents improve by training on their own explanations?
A post shares a paper investigating that question through Retrospection-Only Fine-Tuning (ROFT), a procedure that trains agents on explanations of their experience without reinforcement learning.
TLDR
The paper shared in the post describes an agent attempting a task, observing available feedback and generating a retrospective explanation. ROFT then fine-tunes the agent using next-token prediction loss on the explanation tokens alone. The paper investigates whether that training improves the agent’s future actions.
Combined views
5.1K
1 Source, first seen 6h ago