Report
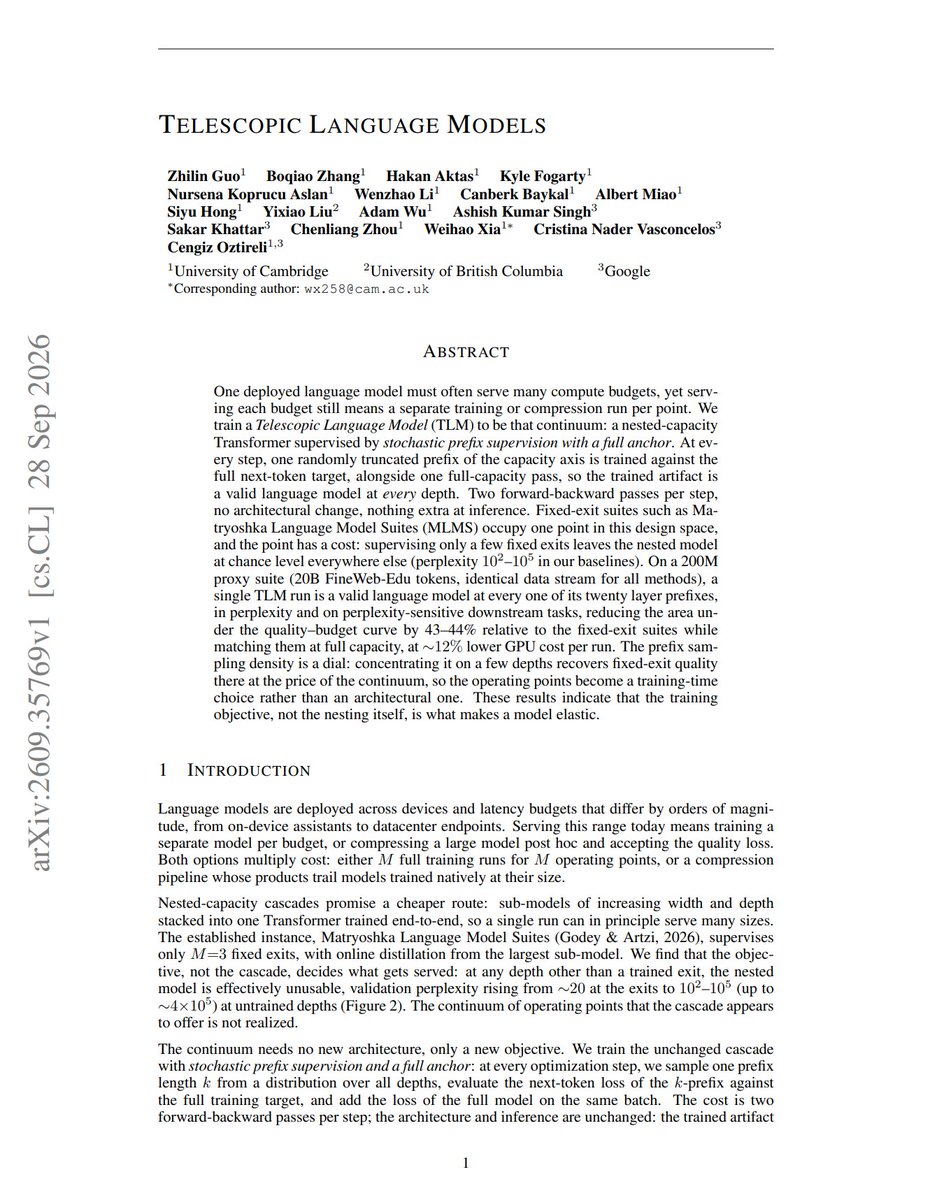
A telescopic language model aims to be valid at every depth
A post shares an excerpt describing a nested-capacity Transformer trained with a randomly truncated capacity prefix alongside a full-capacity pass.
TLDR
The shared excerpt says training uses one randomly truncated capacity prefix per step, trained against the full next-token target, alongside a full-capacity pass. It claims the resulting model is a valid language model at every depth.
Combined views
4K
1 Source, first seen 6h ago
63 likes