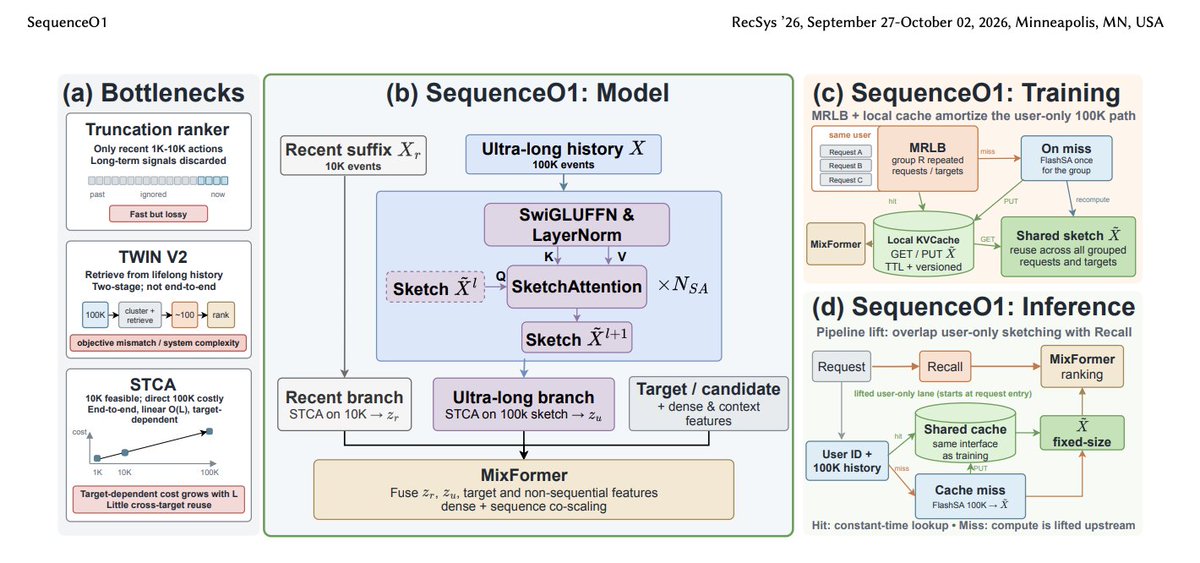
ByteDance’s SequenceO1 paper proposes “sketches” for recommendation histories of up to 100,000 events
A post says the paper, accepted for presentation at RecSys ’26, uses Sketch Attention to turn long event histories into 1,024 learned representations that can be reused when ranking recommendations.
TLDR
A post describing ByteDance’s SequenceO1 paper says the model summarizes up to 100,000 user events in 1,024 learned representations, while a separate branch uses the most recent 10,000 events. The post says the authors observed 2.33% more video finishes and 6.98% fewer dislikes on Douyin. They estimated the ultra-long-history branch would require 50 times fewer training FLOPs and 64 times fewer inference FLOPs than processing the full 100,000-event sequence directly with STCA.
Combined views
1.2K
2 Sources, first seen 5h ago