


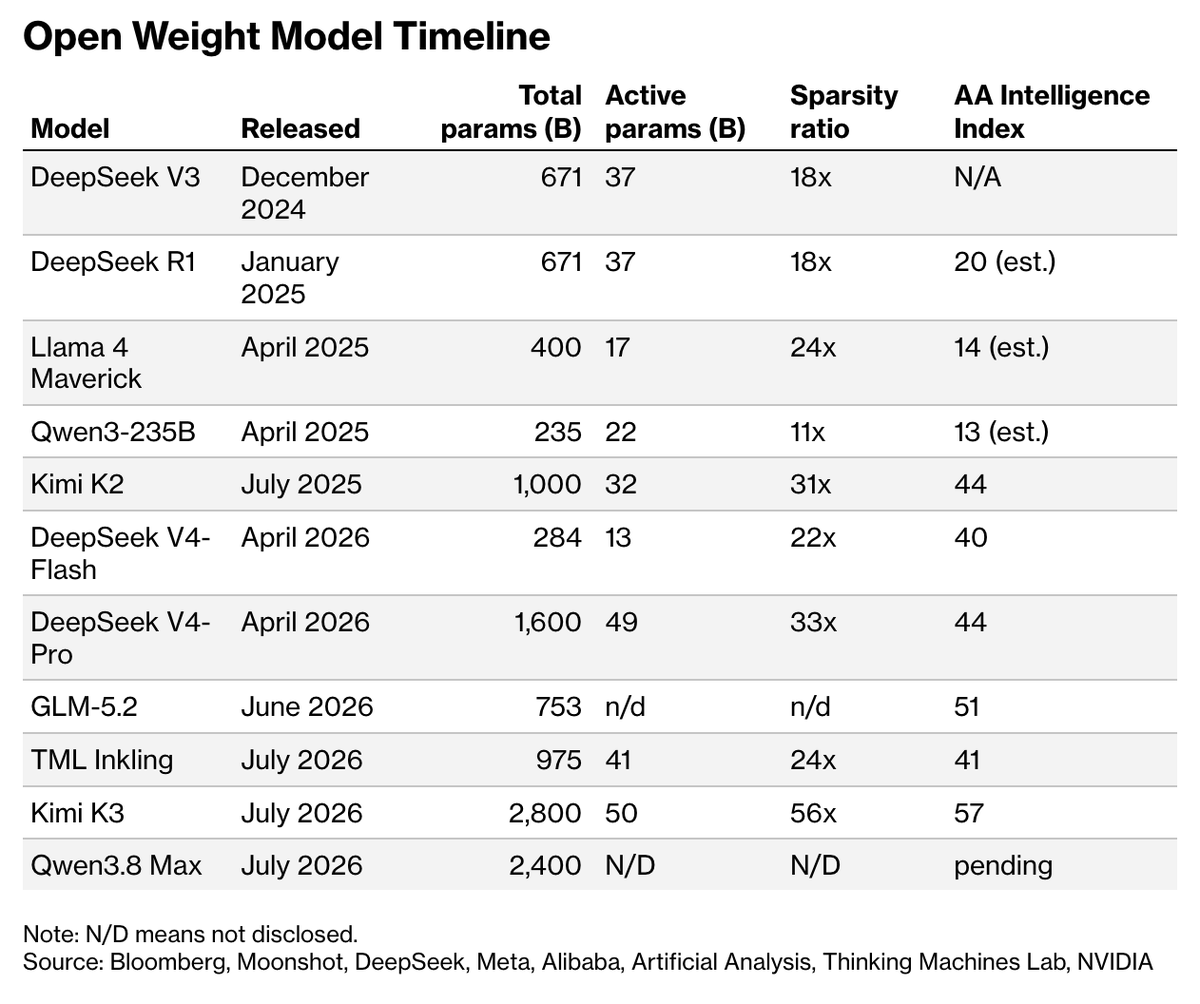
Moonshot AI releases 2.8T open-weight model Kimi K3
It was trained using Nvidia H800 and Huawei hardware.


Combined views
355.2K
10 Sources, first seen ago
Sources
PD  Peter H. Diamandis, MD@PeterDiamandis
- likes: 162
- replies: 10
- bookmarks: 32
- reposts: 19
PD Peter H. Diamandis, MD@PeterDiamandisAmerica just had its AI Sputnik moment. Kimi K3 dropped a bombshell: 2.8 trillion parameters, the largest open-weight model ever built headed. straight to number one. Possible built on chips two generations behind NVIDIA's best, under US export controls designed to make exactly…
- likes: 1.4K
- replies: 142
- bookmarks: 421
- reposts: 171
NL Nathan Lambert@natolambertIn my long read on the Kimi K3 situation, I focus on the big picture for where we going next. 0. Chinese labs have 3 of top 8 most intelligent models, and have been climbing the ranking. 1. China’s recommits to open-source AI – showing a different (lower) read on near-term…
- likes: 455
- replies: 16
- bookmarks: 173
- reposts: 40
TK tae kim@firstadopterThis isn't rocket science. Frontier AI models are going to get much LARGER. Trillions upon trillions of parameters will require vastly more memory, flash storage, and AI GPU compute. Use your brain. https://twitter.com/firstadopter/status/2079179559493046495
- likes: 216
- replies: 9
- bookmarks: 47
- reposts: 19
NL Nathan Lambert@natolambertWhere Kimi K3 puts the balance of power — and bends the trajectory — of the AI ecosystem. https://www.interconnects.ai/p/kimi-k3-the-open-weights-escalation
- likes: 107
- replies: 7
- bookmarks: 55
- reposts: 14
T2 Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)@teortaxesTex2800/896*16 = 50 ✅ 1600/384*7= 29,166 ❌ Bloomberg should learn arithmetic. Activated parameters cannot be calculated from expert sparsity ratio alone, at a minimum there's the attention backbone. K3 is sparse but it's not 50/2800 sparse.…
- likes: 27
- replies: 2
- bookmarks: 1
- reposts: 1