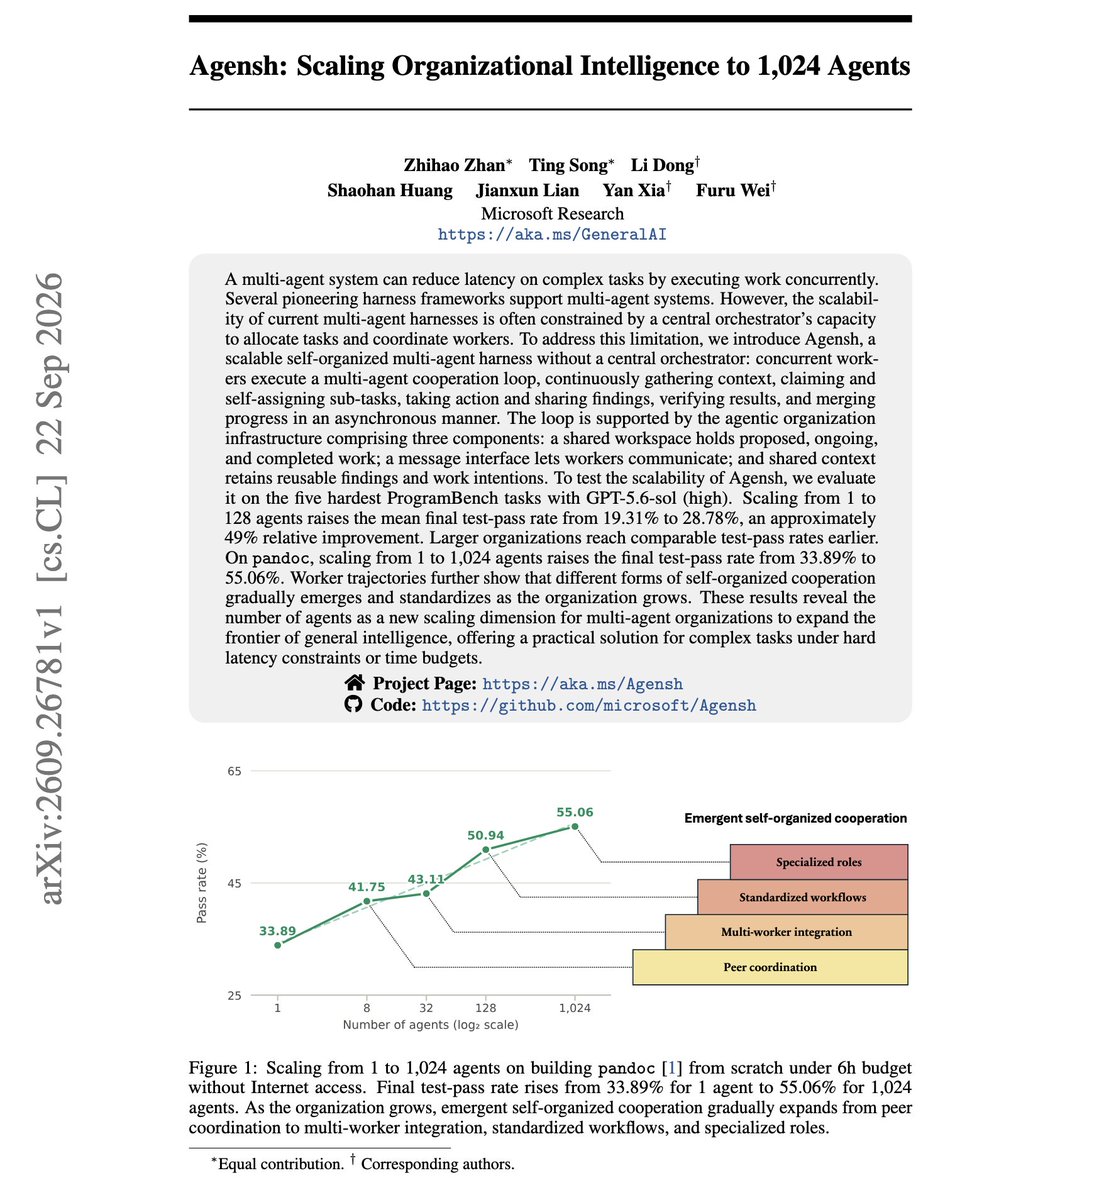
Microsoft Research has introduced Agensh, a coding-agent harness designed to scale without asking one central model to divide and supervise all the work.
Instead, each worker looks at the project’s current state, claims a subtask, makes changes, shares what it learned, checks results and merges useful progress. The researchers argue that this self-organizing loop avoids a bottleneck common to multi-agent systems: as more workers join, a central orchestrator can struggle to keep every assignment and dependency straight.
A shared workspace replaces the manager
Agensh coordinates workers through three pieces of lightweight infrastructure. A shared workspace records proposed, active and completed work. A message interface lets workers communicate. Shared context retains findings and intentions that another worker can reuse.
That setup does not eliminate coordination. It moves coordination into a common state that every agent can read and update. Workers can divide labor, integrate one another’s changes and settle into repeatable roles without waiting for a single manager to issue each instruction.
The approach is especially relevant to long software tasks, where many small investigations, implementations and tests can proceed at the same time. It also creates familiar distributed-systems risks: workers can duplicate effort, pursue stale assumptions or collide while merging changes. Agensh’s verification and shared-state steps are meant to keep that parallel work useful.
More workers improved the benchmark, but did not solve it
The team evaluated Agensh with GPT-5.6-sol at high reasoning effort on the five hardest ProgramBench tasks: rebuilding FFmpeg, gromacs, pandoc, PHP-src and ctags. Each run had a six-hour budget and no internet access.
Across those five tasks, the paper reports a mean final test-pass rate of 19.31% with one agent and 28.78% with 128 agents — about a 49% relative increase. Larger teams generally reached a given pass rate sooner. On pandoc, for example, 128 agents cleared 30% after 30 minutes, while teams of 32 and eight first reached that mark after 60 and 90 minutes.
The largest demonstration put 1,024 agents on pandoc. Its final test-pass rate reached 55.06%, up from 33.89% for a single agent. Researchers also observed coordination patterns become more structured as the group grew, moving from peer-to-peer help toward standardized workflows and specialized roles.
Those numbers are promising, but they are not a claim that 1,024 agents can autonomously ship dependable production software. The experiments use one model family, a small set of difficult reconstruction tasks and a fixed laboratory setup. Even the best reported pandoc run left many tests failing. The clearest result is narrower: under these conditions, adding self-organizing parallel workers improved both speed and final coverage without requiring a central task dispatcher.