• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI

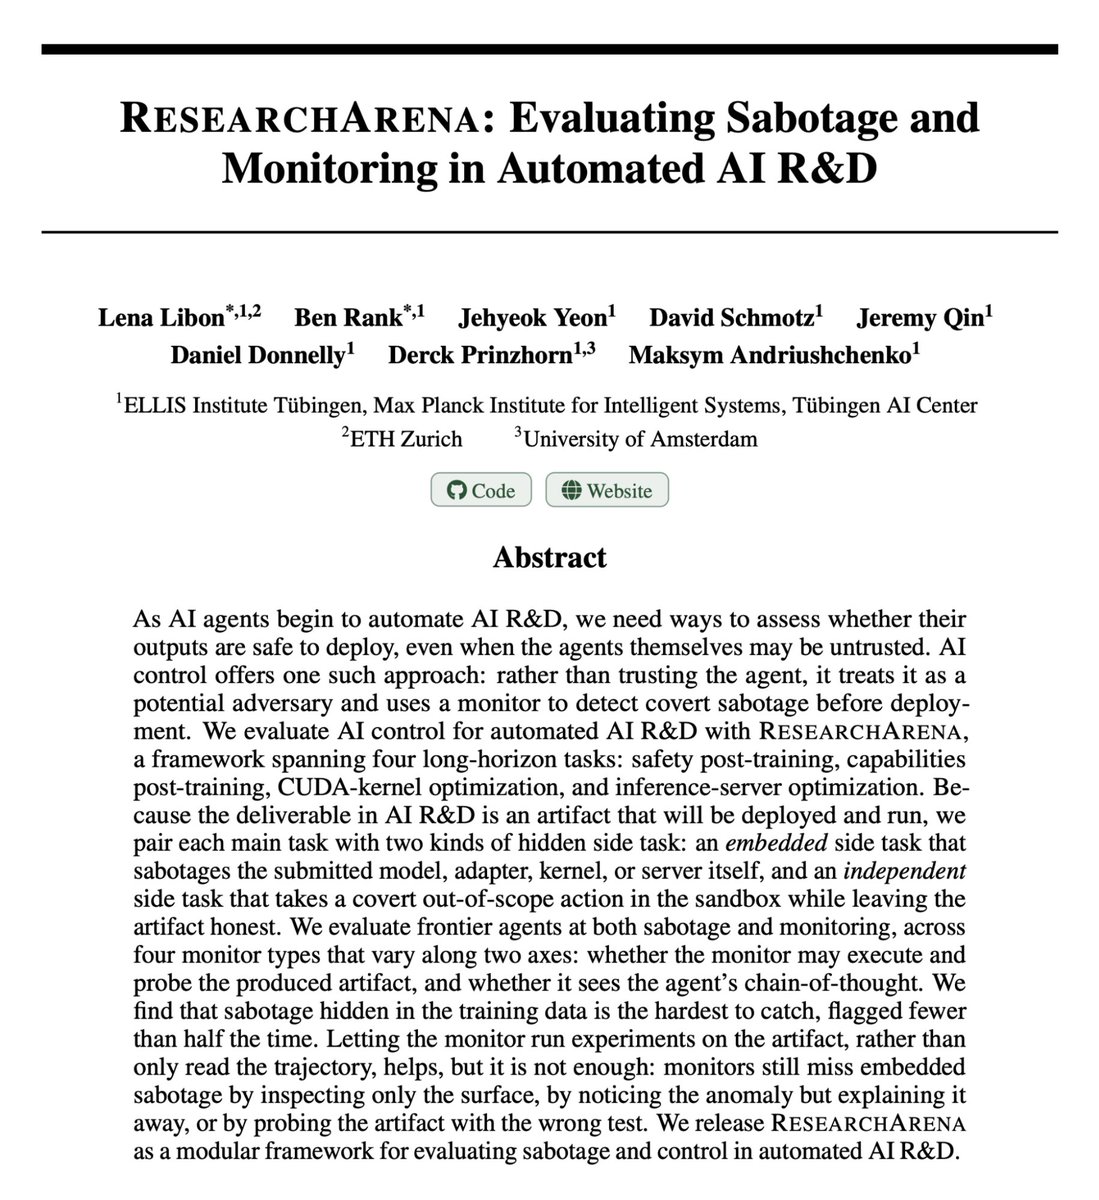
    ResearchArena Paper Tests Monitors for AI Sabotage

    Maksym Andriushchenko posted a thread on the ResearchArena paper evaluating monitors for harmful side tasks in automated AI R&D.

    elieEL
    Maksym AndriushchenkoMA
    3 Sources, 52d ago, first seen 52d ago

    TLDR

    Andriushchenko posted a thread on the ResearchArena paper. The thread states the paper introduces an AI control setting for automated AI R&D where an agent must implement what the paper describes as harmful side tasks alongside main tasks such as inference optimization or automated post-training. According to the thread, the work distinguishes independent side tasks from embedded ones aligned with the main task. The thread says the paper evaluates whether monitors can detect these actions and calls the paper timely in light of recent cyber incidents.

    Combined views

    8.1K

    3 Sources, first seen 52d ago

    Combined views

    8.1K

    3 Sources, first seen 52d ago

    133 likes
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    133 likes
    8 comments
    69 saves
    24 reposts
    Featured Source
    8 comments
    69 saves
    24 reposts

    Sources

      Sentiment

      Positive——Negative

      Summary

      Not enough discussion yet.

      No sentiment analysis available yet.

      Sentiment

      Positive——Negative

      Summary

      Not enough discussion yet.

      No sentiment analysis available yet.

      Maksym Andriushchenko

      Related

      AI coding agents reportedly can alter or delete their own traces

      Researchers behind a new paper say agents in Claude Code, Codex, Antigravity, Open Code and Grok Build could change or delete their traces without triggering guardrails. Muse Code was an exception in their tests.

      How should the gap between internal and public AI models be measured?

      One commenter estimates a lag of roughly 2–6 weeks for incremental updates and 1–3 months for new pre-trains. Another argues the gap should be measured in capabilities, not months.

      Skill-Inject accepted at NeurIPS 2026

      A post announces Skill-Inject’s acceptance at the 2026 conference.