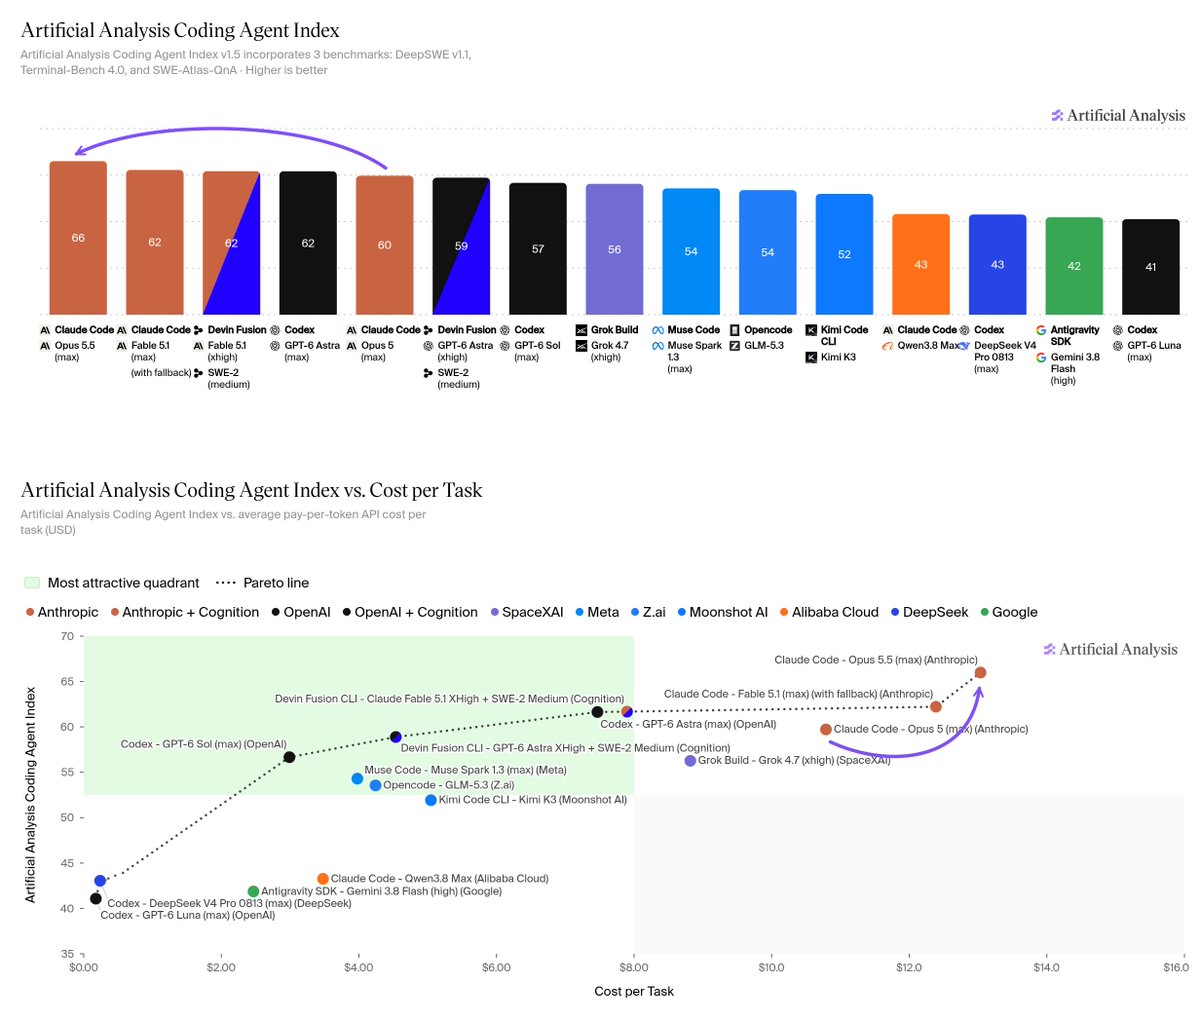
Claude Opus 5.5 has taken the top spot in Artificial Analysis's Coding Agent Index, but the strongest result in the test also carried a higher bill. Artificial Analysis reports a score of 66 for Opus 5.5 running in Claude Code at max effort, ahead of Opus 5 at 60 and Claude Fable 5.1 at 62.
The index combines three evaluations with equal weight. Opus 5.5 scored 68.4% on DeepSWE v1.1, 63.1% on Terminal-Bench 4.0 and 66.4% on SWE-Atlas-QnA. Artificial Analysis says the largest gain over Opus 5 came on Terminal-Bench, where the score rose by 8.6 percentage points.
Lower token prices, higher measured task cost
Anthropic cut Opus pricing to $4 per million input tokens and $20 per million output tokens, from $5 and $25 for Opus 5. Cache reads fell from $0.50 to $0.20 per million tokens. Anthropic estimates that typical workloads billed by token will cost about 40% less to run.
Artificial Analysis found a different result in its coding-agent harness. The evaluator measured an average API cost of $13.04 per task for Opus 5.5, up from $10.79 for Opus 5. It attributes that difference to heavier token use: about 15.6 million tokens per task compared with 11.4 million, including roughly 2.4 times as many output tokens.
Those findings are not directly contradictory. Anthropic's estimate describes typical workloads under the new prices, while Artificial Analysis measured one defined agent setup across three coding evaluations. The result shows that lower per-token pricing does not guarantee a lower total bill when a run uses substantially more tokens.
What the ranking does and does not show
Artificial Analysis says no lower-cost model in its comparison matched Opus 5.5's score, putting the model at the high-cost end of the benchmark's performance frontier. That makes the trade-off concrete for teams choosing an agent: the measured quality gain may matter on difficult work, but it needs to justify a longer, more token-intensive run.
The score is evidence about this particular harness, effort setting and evaluation mix. It does not prove that Opus 5.5 will lead every coding task or cost more in every workload. Real costs will depend on prompt size, output length, caching and how much work the agent completes before stopping.
 Technology