• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
Technology
Announcement

Open-source proxy turns coding-agent harnesses into reinforcement-learning environments

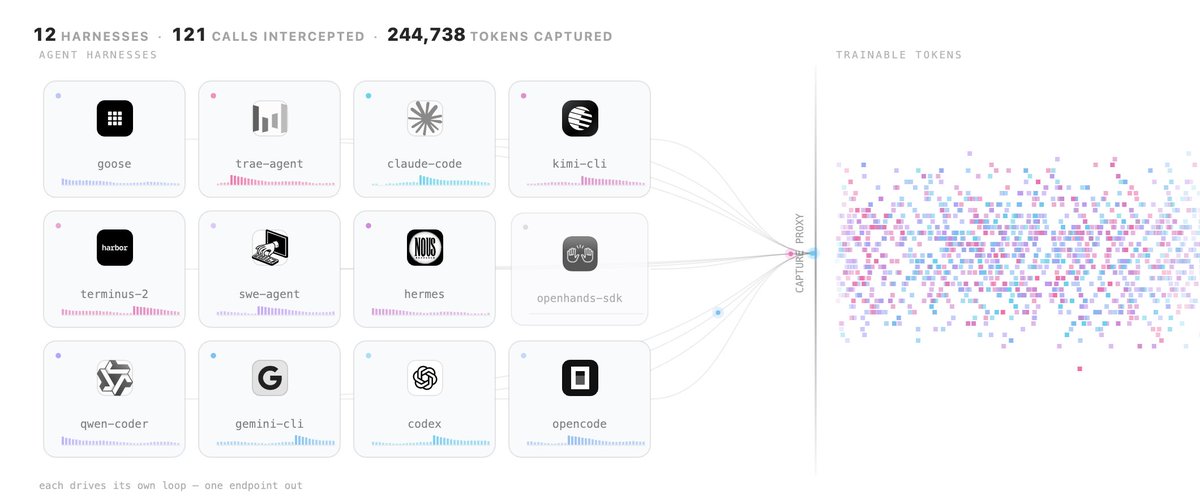
The projectโ€™s post says its proxy records token IDs and log probabilities from vLLM while 10 harnesses run unmodified.

C๐Ÿค—
HF
3 Sources, 1h ago, first seen 1h ago

TLDR

The projectโ€™s post says a capture proxy lets existing coding harnesses serve as reinforcement-learning environments without changes to the harnesses or training code. It reports 31% fewer tool calls on tasks the model already solved after adding a reward for using fewer calls, with reductions in every harness and about half as many calls under Codex. The post says the proxy, trainer, tasks, training code and seven trained models are open source.

Combined views

32.9K

3 Sources, first seen 1h ago

561 likes73 comments453 saves132 reposts
Combined views

32.9K

3 Sources, first seen 1h ago

561 likes73 comments453 saves132 reposts

Sentiment

Positiveโ€”โ€”Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Featured Source

Sentiment

Positiveโ€”โ€”Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

3 Sources

@ClementDelangueWe turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to the harnesses, no changes to the training code. Any open model, any task set, fully open source my friends! Same model, same weights: 62% under Mini-SWE-Agent, 33% under Claude Code. But training inside a real harness normally means reimplementing it as an environment, so most models get trained in a scaffold nobody actually ships. The fix is a proxy, not a rewrite. The harness thinks it's talking to a model API. It's actually talking to a capture proxy that speaks the 4 formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini), forwards to @vllm_project, records the exact token IDs and logprobs vLLM sampled, and hands TRL sequences it can train on. The harness becomes the environment. 10 harnesses run through it today, none modified. And because you control the reward, you can shape behavior the harness never asked for. We added a small bonus for solving a task in fewer tool calls: on tasks it already solved, the model now uses 31% fewer calls, in every harness, and about half under Codex. Tested on LFM2.5-2.6B from @liquidai: โ†’ Train in one harness: better mostly in that harness (OpenCode 34% โ†’ 58%). โ†’ Train in 4 at once: better in all 4 (42% โ†’ 54%). โ†’ SFT on 3,189 rollouts from Qwen3.8-27B instead: plateaus at 47.5%, below both RL runs. Everything is open and reproducible: the capture proxy in OpenEnv, the trainer in TRL, the tasks, the SFT data, the training code and all 7 trained models. Bigger models and bigger runs next. Full guide: https://huggingface.co/spaces/FineEnvs/multi-harness-rl1h
@huggingfaceRT @ClementDelangue: We turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to theโ€ฆ1h
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI

    3 Sources

    @ClementDelangueWe turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to the harnesses, no changes to the training code. Any open model, any task set, fully open source my friends! Same model, same weights: 62% under Mini-SWE-Agent, 33% under Claude Code. But training inside a real harness normally means reimplementing it as an environment, so most models get trained in a scaffold nobody actually ships. The fix is a proxy, not a rewrite. The harness thinks it's talking to a model API. It's actually talking to a capture proxy that speaks the 4 formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini), forwards to @vllm_project, records the exact token IDs and logprobs vLLM sampled, and hands TRL sequences it can train on. The harness becomes the environment. 10 harnesses run through it today, none modified. And because you control the reward, you can shape behavior the harness never asked for. We added a small bonus for solving a task in fewer tool calls: on tasks it already solved, the model now uses 31% fewer calls, in every harness, and about half under Codex. Tested on LFM2.5-2.6B from @liquidai: โ†’ Train in one harness: better mostly in that harness (OpenCode 34% โ†’ 58%). โ†’ Train in 4 at once: better in all 4 (42% โ†’ 54%). โ†’ SFT on 3,189 rollouts from Qwen3.8-27B instead: plateaus at 47.5%, below both RL runs. Everything is open and reproducible: the capture proxy in OpenEnv, the trainer in TRL, the tasks, the SFT data, the training code and all 7 trained models. Bigger models and bigger runs next. Full guide: https://huggingface.co/spaces/FineEnvs/multi-harness-rl1h
    @huggingfaceRT @ClementDelangue: We turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to theโ€ฆ1h
    Today's Rank

    #1

    Today's Rank

    #1