Science
Artificial Analysis launches Terminal-Bench-Science leaderboard
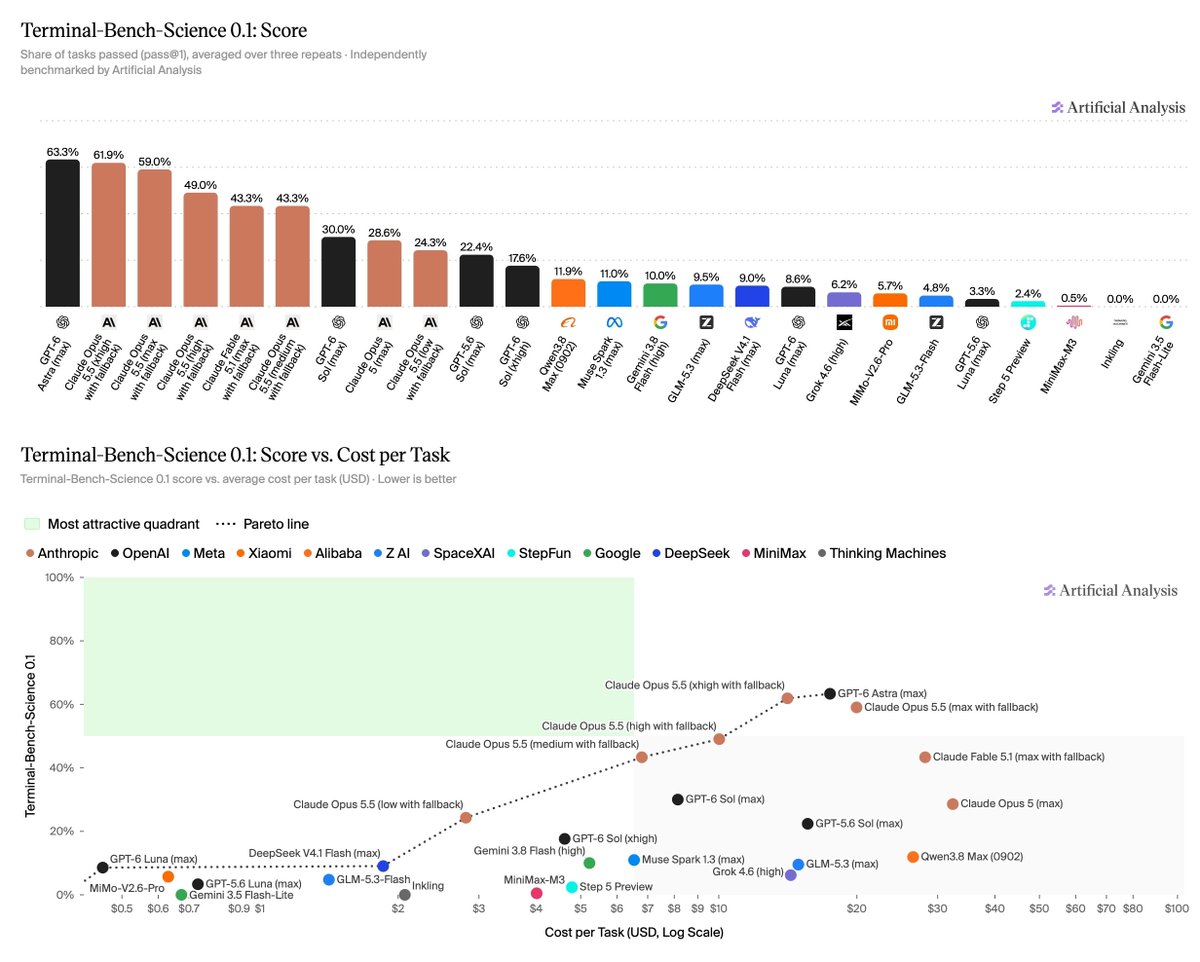
Artificial Analysis says GPT-6 Astra (max) leads at 63%, followed by Claude Opus 5.5 (xhigh) at 62%, on a benchmark of 70 expert-curated scientific research tasks.
TLDR
Artificial Analysis announced its Terminal-Bench-Science 0.1 leaderboard on September 24, 2026. It describes 70 tasks across life, physical, mathematical, engineering and earth sciences. Agents work from start to finish in sandbox environments, with automated pass/fail grading; scores reflect average pass@1 over three attempts. Artificial Analysis puts GPT-6 Astra (max) at 63% and Claude Opus 5.5 (xhigh) at 62%. The highest-scoring open-weight models, GLM-5.3 (max) and DeepSeek V4.1 Flash (max), score 10% and 9%. It says life sciences is the lowest-scoring domain for most leading models, while cautioning that domain scores are noisy with 8 to 19 tasks each.