2 posts tagged by Digg
AI
A Zstd task couldn't show whether structured fuzzing improved correctness; a harder Pandoc task yielded no reliable method ranking.
Technology
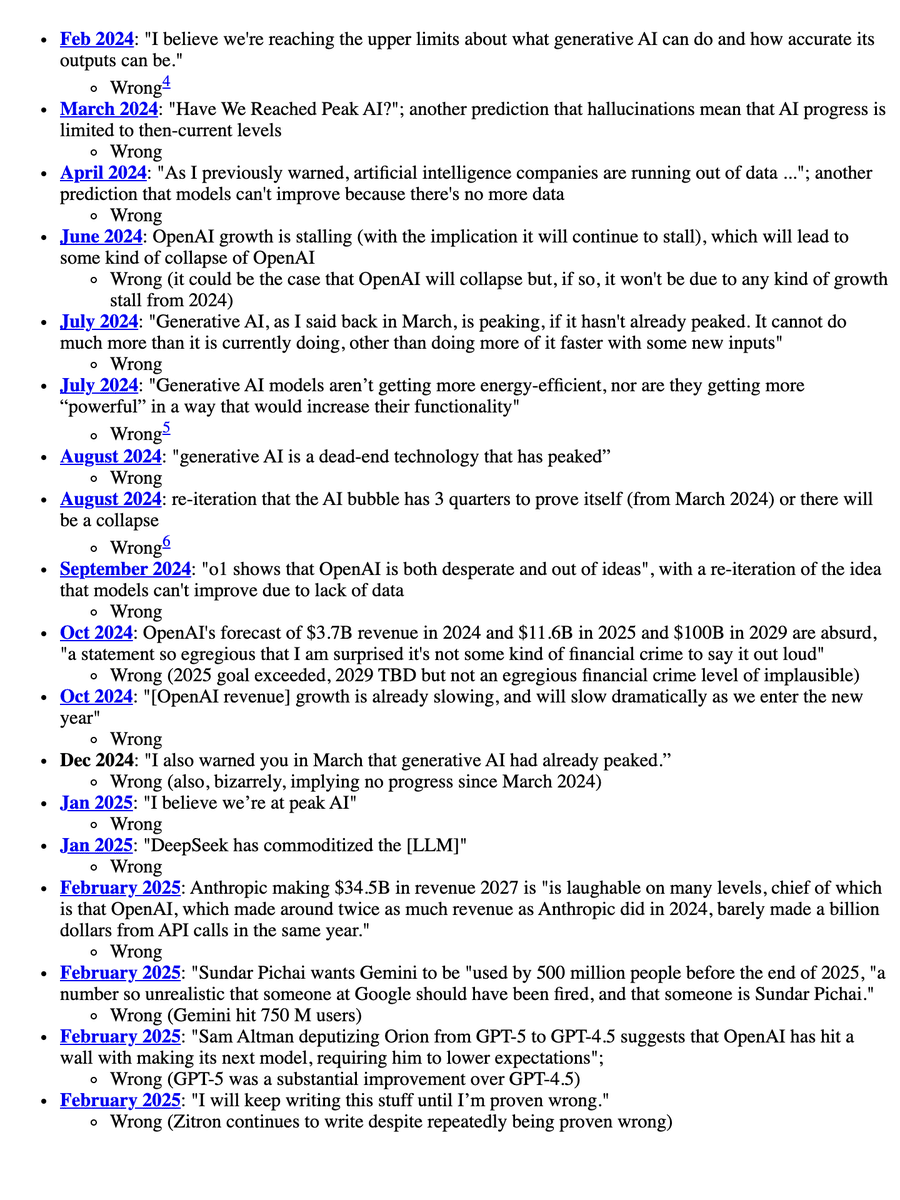
Dan Luu posted an analysis comparing Ed Zitron's forecasts against actual outcomes.
 Technology