Announcement
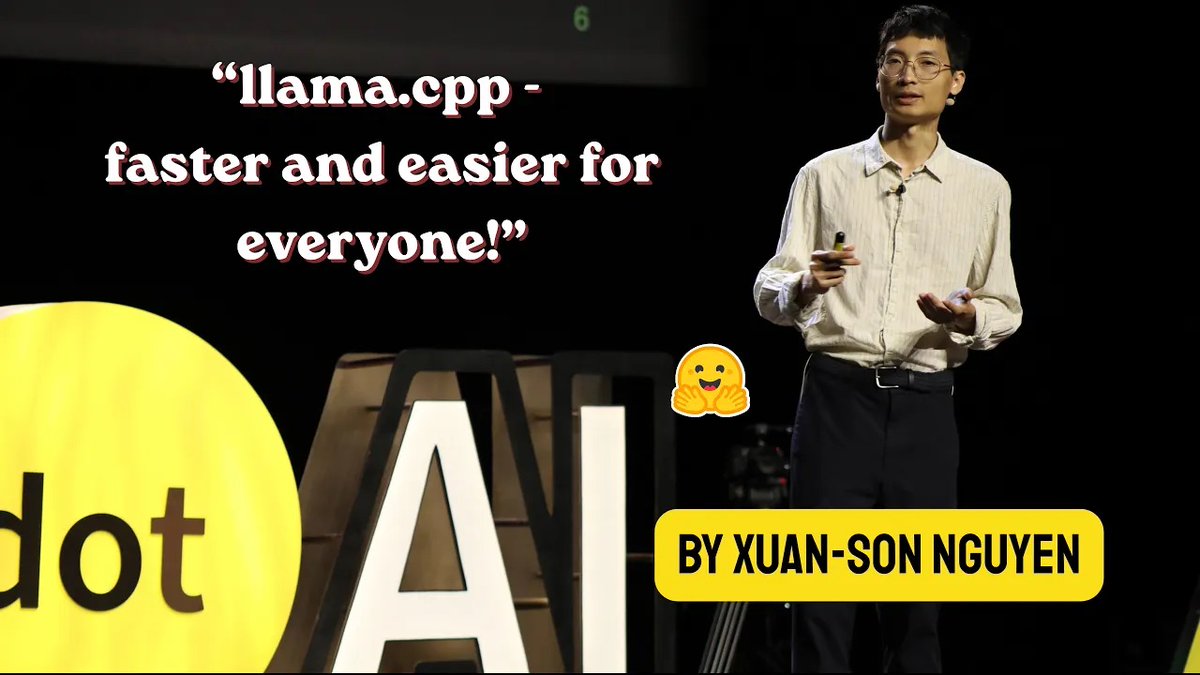
Replay of dotConferences talk on speculative decoding and dflash/dspark is out
The speaker says the talk explains how speculative decoding can speed up token generation and shows its use on llama.cpp.


TLDR
A speaker has shared a replay of their dotConferences talk on speculative decoding and dflash/dspark. They say it explains how the approach helps improve token generation speed and shows how easy it is to use on llama.cpp.
Combined views
1.2K
2 Sources, first seen ago