Report
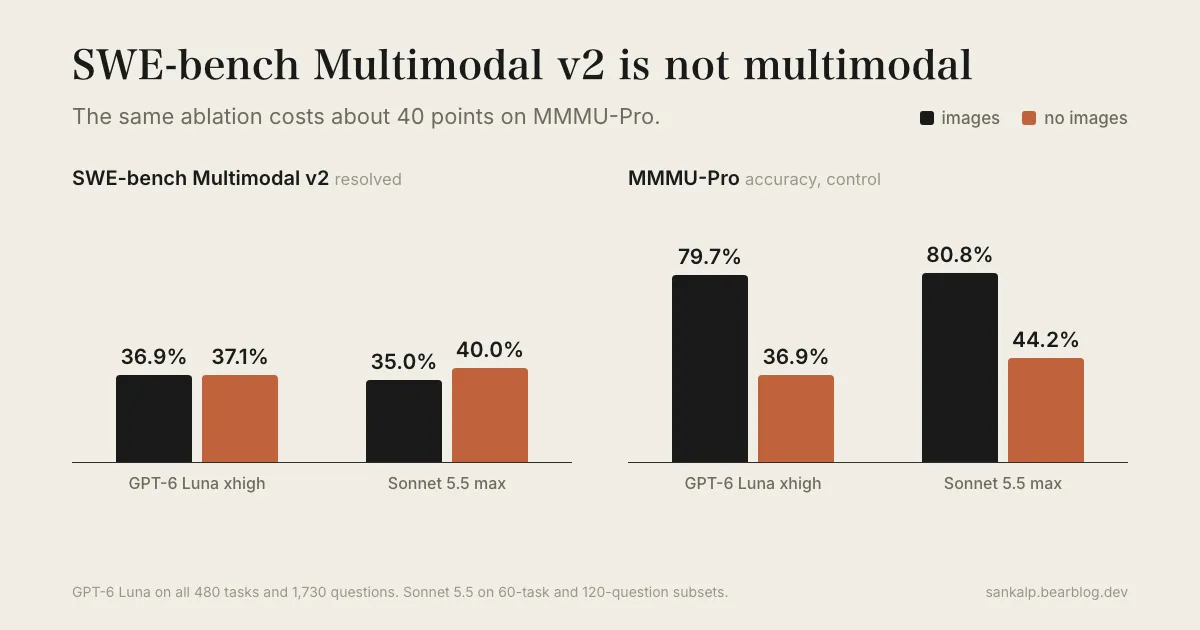
SWE-bench Multimodal v2 scores barely moved without images in one experiment
Sankalp Shubham found little change in resolved-task rates, while both models faltered on a separate visual test.
TLDR
Removing images barely changed how often GPT-6 Luna resolved SWE-bench Multimodal v2 tasks in Sankalp Shubham’s experiment; Sonnet 5.5 showed a similar pattern on a smaller sample. Both models lost substantial accuracy without images on a separate, image-dependent test. Shubham argues that issue text and grading tests may explain the benchmark result, but his 60-task Sonnet run cannot rule out a moderate benefit from images.
Combined views
—
5 Sources, first seen ago