Announcement
WM-VLM introduces world-model-generated visual steps for spatial reasoning
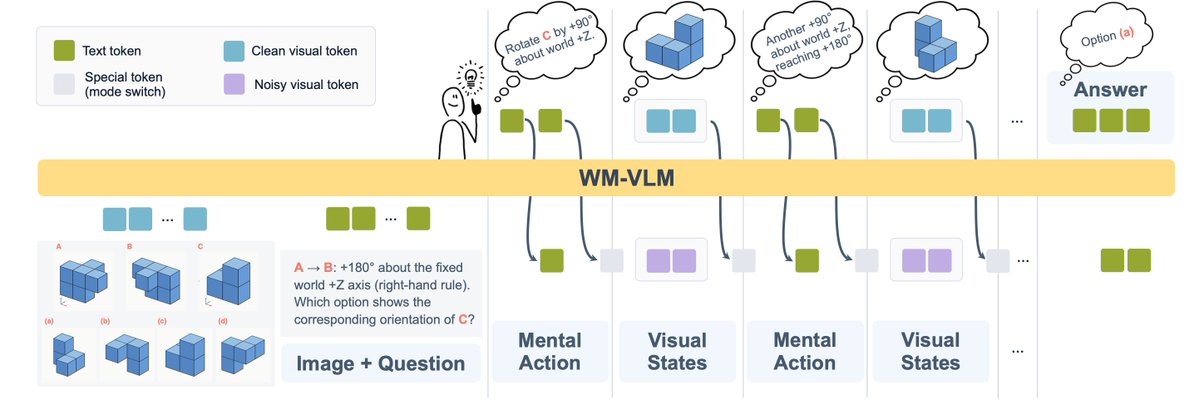
The WM-VLM announcement says its lightweight, two-branch design efficiently generates visual thoughts and verbal reasoning.


TLDR
A post introducing WM-VLM says an internal world model generates intermediate visual states that a vision-language model uses for spatial reasoning. The author claims it significantly improves on a supervised-fine-tuned VLM backbone on tasks requiring “imagination.” They suggest alternating visual and text reasoning might replace verbal-only reasoning, and say generating latent representations may be enough without reconstructing pixels.
Combined views
227
2 Sources, first seen ago