Announcement
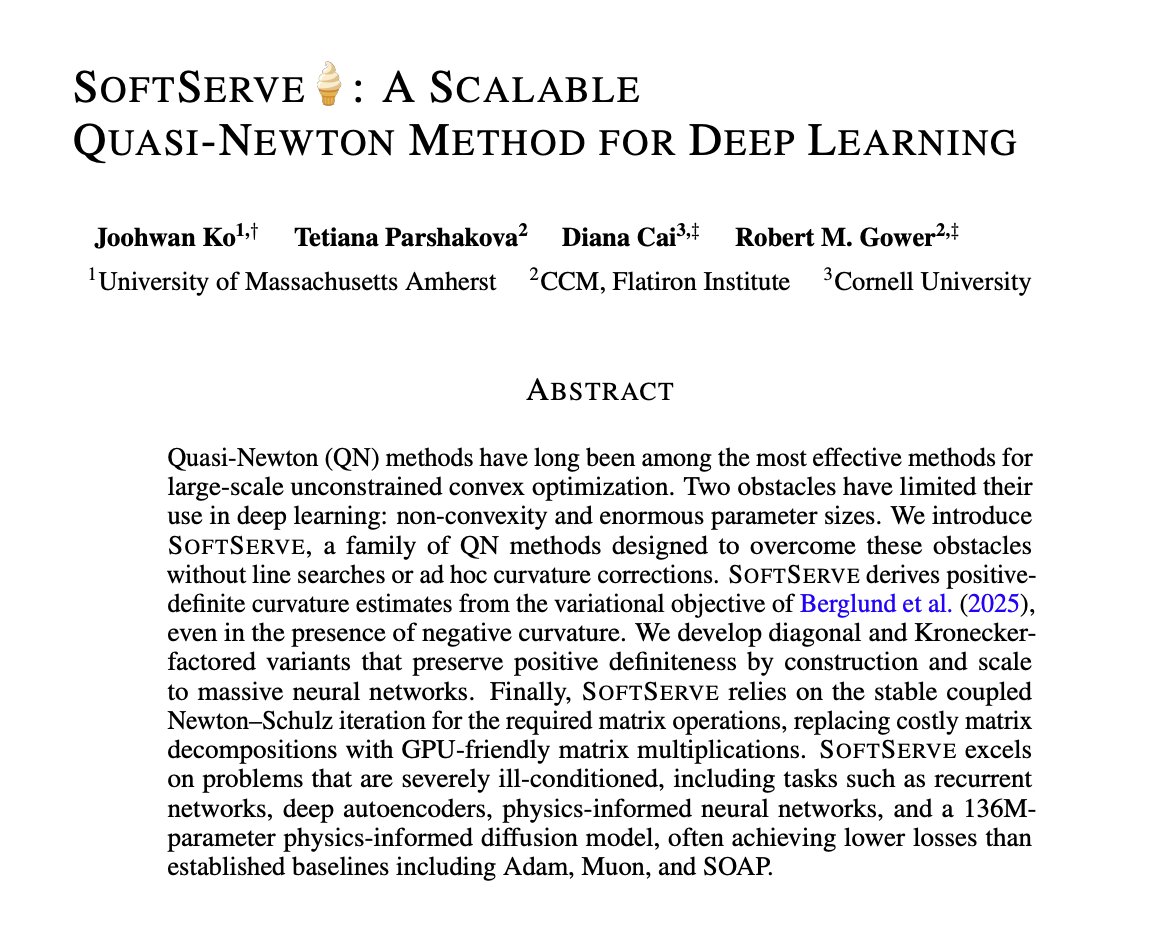
SoftServe preprint proposes a quasi-Newton method for large neural networks
A researcher says the method replaces the exact secant equation with a “soft” penalty and uses GPU-friendly matrix multiplications.
TLDR
A researcher introducing the SoftServe preprint says its quasi-Newton method is designed for non-convex objectives and to scale to very large neural networks. The researcher says it considers structured curvature approximations, such as diagonal and Kronecker forms, and uses Newton–Schulz procedures to approximate costly matrix operations with GPU-friendly matrix multiplications.
Combined views
3.1K
2 Sources, first seen ago