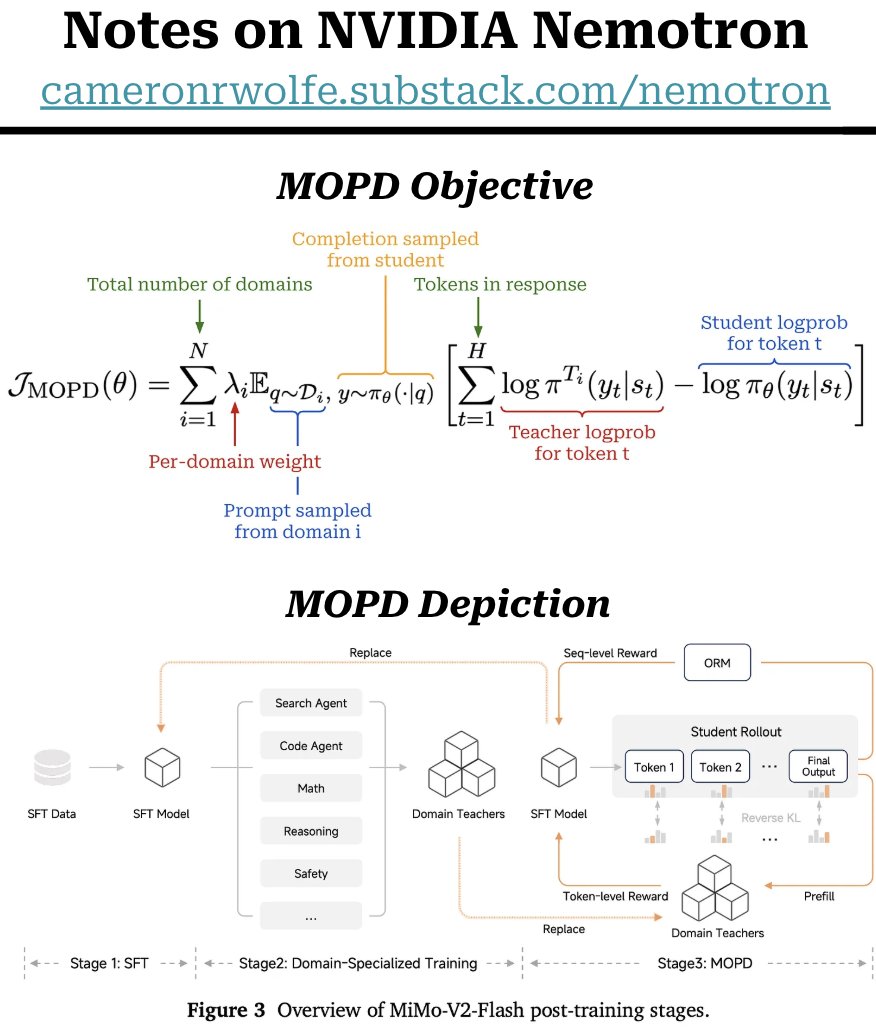
How multi-teacher on-policy distillation combines specialist capabilities in one model
A post explains that the student model generates text, then a teacher for that domain scores it token by token.

TLDR
A post describes multi-teacher on-policy distillation (MOPD) as a way to train specialist models separately, then consolidate their capabilities into one student model. The student generates text, and a teacher for the relevant domain scores each token rather than generating the text itself. The post says this dense feedback can make distillation more sample-efficient than outcome-based reinforcement learning, but cautions that teachers whose behavior differs too much from the student's may provide a weaker learning signal.
Combined views
2.1K
1 Source, first seen ago