• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

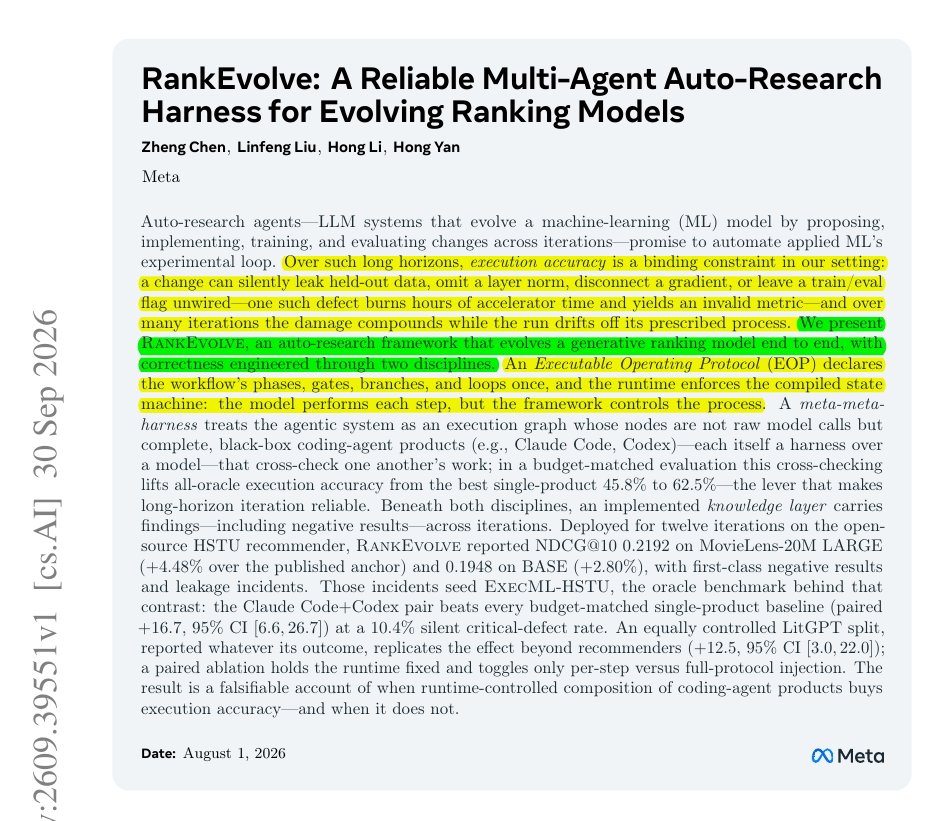
    Mixing Claude Code and Codex reportedly raised fully correct patches from 45.8% to 62.5% at matched spend

    A post describing a Meta paper says cross-review caught more silent bugs than giving one coding agent a bigger budget.

    Rohan PaulRP
    1 Source, 2h ago, first seen 2h ago

    TLDR

    A post describing a Meta paper says using Claude Code and Codex on the same task raised fully correct patches from 45.8% to 62.5% at matched spend. It attributes the gain to agents making different mistakes, giving cross-review more to catch, and says the effect repeated on an unrelated training codebase.

    Combined views

    3.3K

    1 Source, first seen 2h ago

    Combined views

    3.3K

    1 Source, first seen 2h ago

    63 likes
    63 likes
    47 comments
    25 saves
    10 reposts
    47 comments
    25 saves
    10 reposts
    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    1 Source

    Rohan Paul@rohanpaul_aiNew Meta paper finds that having 2 different coding agents review each other's patches catches far more silent bugs than giving 1 agent a bigger budget. Mixing Claude Code and Codex on the same task raised fully correct patches from 45.8% to 62.5% at matched spend. Agents editing real training code can leak test data, break a gradient, or miswire a flag. The code still runs, so you burn GPU hours and get numbers that look valid. The reason is uncorrelated mistakes: agents from the same product fail the same way, so there is little for review to catch. The effect repeated on an unrelated training codebase. – arxiv. org/abs/2609.39551 Title: "RankEvolve: A Reliable Multi-Agent Auto-Research Harness for Evolving Ranking Models"2h