• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

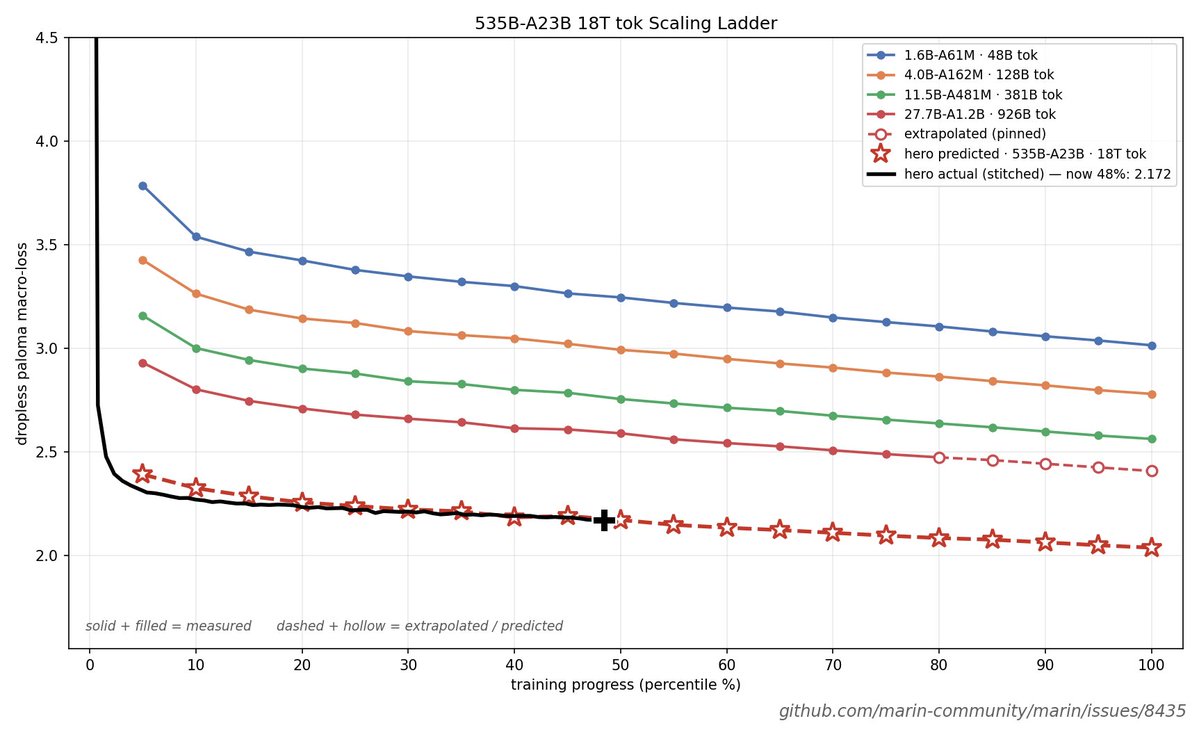
    Marin’s training run is reportedly within 0.3% of its loss forecast at the halfway point

    A post says custom kernels let Marin expand the model from 360 billion to 535 billion parameters while speeding up token processing.

    RS
    LD
    2 Sources, ,

    TLDR

    An October 1 post says Marin’s live-streamed run is halfway through training a 535-billion-parameter mixture-of-experts model on a planned 18 trillion tokens. Its evaluation loss is reportedly within 0.3% of a publicly pre-registered forecast, despite a 300-fold extrapolation. The post says the run was originally planned for 360 billion parameters, but custom kernels allowed a larger model and faster token processing.

    Combined views

    10.7K

    2 Sources, first seen 5h ago
    Combined views

    10.7K

    2 Sources, first seen 5h ago

    182 likes
    5h ago
    first seen 5h ago
    182 likes
    8 comments
    112 saves
    22 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    8 comments
    112 saves
    22 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @classiclarryd43 days ago Marin kicked off the largest live-streamed pretraining run in history: a 535B MoE trained on 18T tokens. A scaling ladder was used to forecast eval loss along the entire trajectory, and the forecast was publicly pre-registered. Its halfway along, and despite being a 300x extrapolation, the run is within 0.3% of the forecast. The run was originally planned to be 360B parameters. Until @ravwojdyla found a hardware implementation with custom kernels to grow to 535B parameters while also speeding up tokens per second. Learn about how he did it on the Open Athena blog: https://openathena.ai/blog/expert-parallelism/.
    @ziv_ravidRT @classiclarryd: 43 days ago Marin kicked off the largest live-streamed pretraining run in history: a 535B MoE trained on 18T tokens. A s…