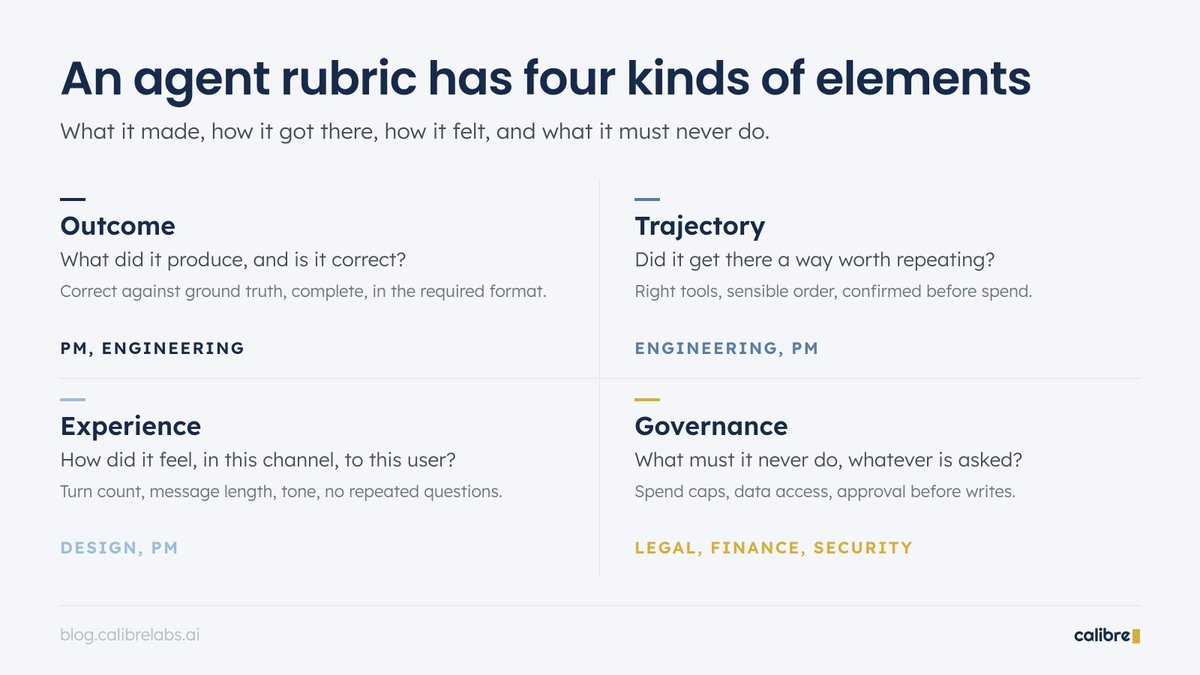
A four-part framework for evaluating long-horizon AI agents
A user shares four evaluation lenses—results, process, experience and rule-following—and argues that examining agent traces is essential to refining what to test.
TLDR
The post outlines four areas for evaluating agents that handle a broad range of work: outcome (were the results great?), trajectory (was the correct process followed?), experience (did it feel right?) and governance (were critical rules followed?). The user recommends starting with a product point of view, then examining traces of the agent’s activity to sharpen the focus. They also share what they describe as an annotated trace for Corner, a local shopping assistant, saying traces can reveal flaws before they become obvious to customers.