Announcement
Shared memory is claimed to improve looped Transformers while cutting memory use
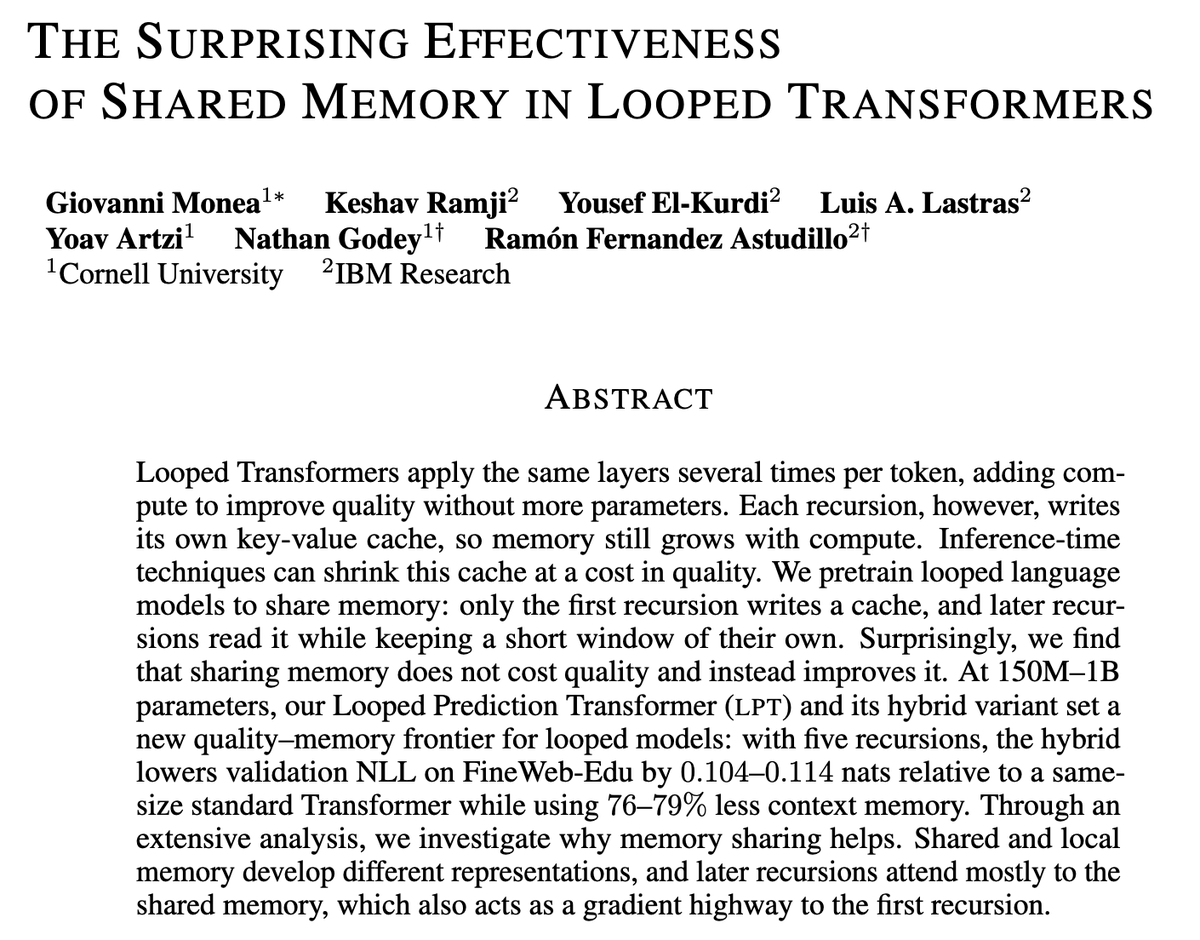
The researchers say later recursions read the first recursion’s key-value cache while keeping a short window of their own.


TLDR
In a preprint, the researchers report that training looped Transformers to share memory improved quality rather than hurting it. Their hybrid model with five recursions had 1.12–1.82 lower validation perplexity on FineWeb-Edu than a same-size standard Transformer while using 76–79% less context memory, they say.
Combined views
3K
2 Sources, first seen ago