AI
PowerPoint workflow reportedly helps GPT-5.5 in one coding harness and hurts it in another
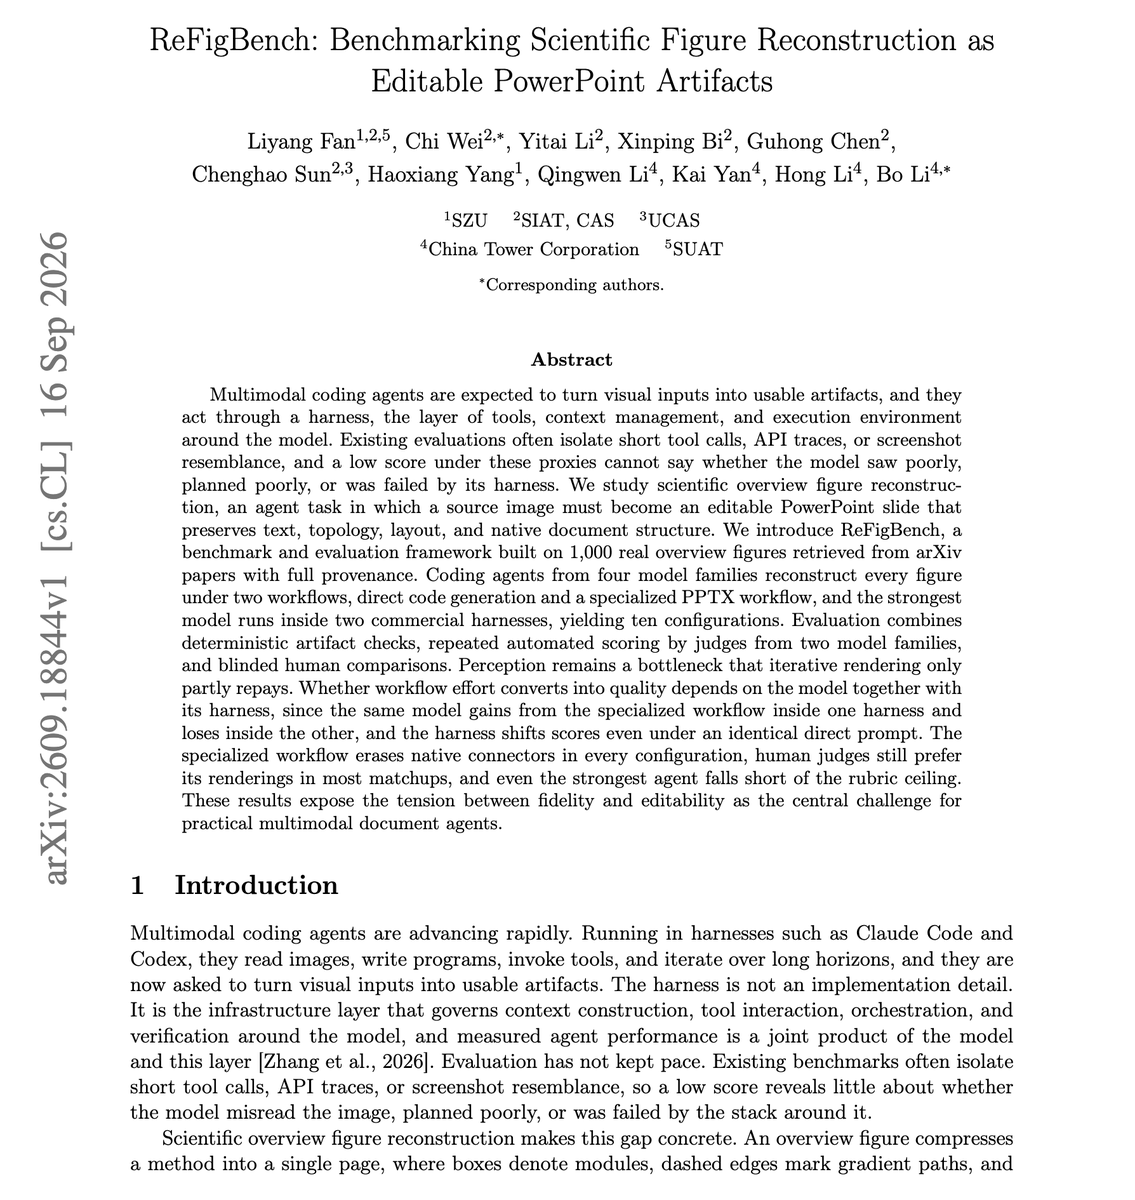
A post summarizing ReFigBench describes a benchmark for rebuilding arXiv figures as editable slides. It says the harness—the software setup around the model—changed scores even when prompts were identical.
TLDR
A post describing the ReFigBench paper says GPT-5.5 ran the same 1,000 tasks in Claude Code and Codex. A specialized PowerPoint workflow improved results in one harness but worsened them in the other.
The benchmark asks coding agents to rebuild real arXiv overview figures as editable PowerPoint slides, preserving text, layout and connections. The post describes ten configurations across GPT, Claude, MiMo and MiniMax, evaluated through artifact checks, two families of LLM judges and blinded human comparisons.
The post identifies perception as the main bottleneck and highlights a trade-off: the specialized workflow removed native connectors in every configuration, yet human judges preferred its renderings in most matchups.