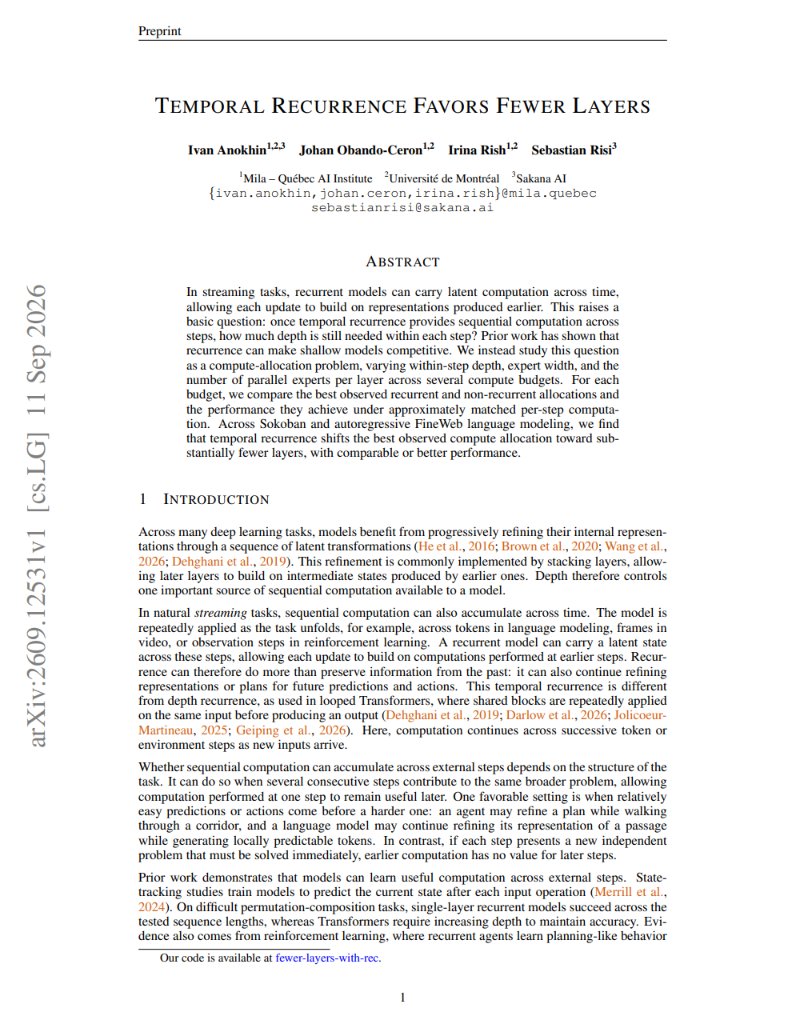
Two-layer recurrent networks reportedly match 32-layer feedforward baselines at equal compute
A post asks whether remembering the previous step could let models get by with just two layers, arguing that compute has been spent on the wrong axis.
TLDR
A post claims that two-layer recurrent networks match 32-layer feedforward baselines under identical compute budgets. It frames the claimed result around a model’s ability to remember the previous step, questioning the emphasis on adding layers.
Two-layer recurrent networks reportedly match 32-layer feedforward baselines at equal compute
A post asks whether remembering the previous step could let models get by with just two layers, arguing that compute has been spent on the wrong axis.
TLDR
A post claims that two-layer recurrent networks match 32-layer feedforward baselines under identical compute budgets. It frames the claimed result around a model’s ability to remember the previous step, questioning the emphasis on adding layers.