Announcement
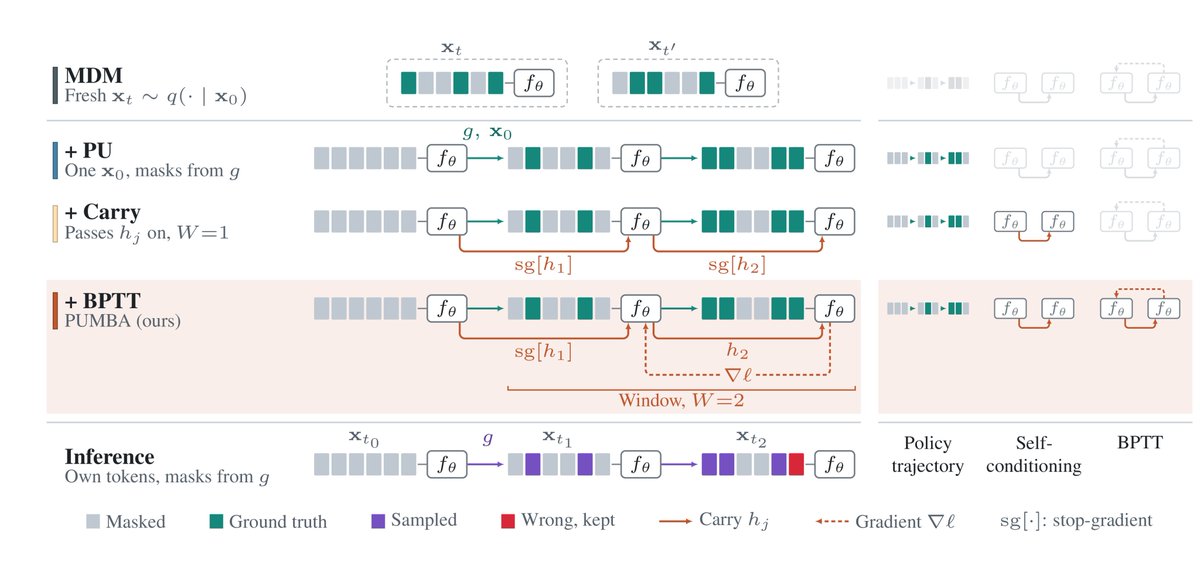
PUMBA paper explores a training-sampling gap in masked diffusion language models
An author says the paper examines how training could better reflect the paths models follow when generating text.


TLDR
An author introducing PUMBA says masked diffusion language models are trained one way and sampled another. The paper studies how training could better account for the paths models follow during inference, and how that might lead to more efficient text generation.
Combined views
1.3K
2 Sources, first seen ago