Announcement
Shared-cache transformer training tweak reportedly removes 81–89% of the primary continuation penalty
The researcher says generation had higher loss than prefill, even with ground-truth token inputs.
TLDR
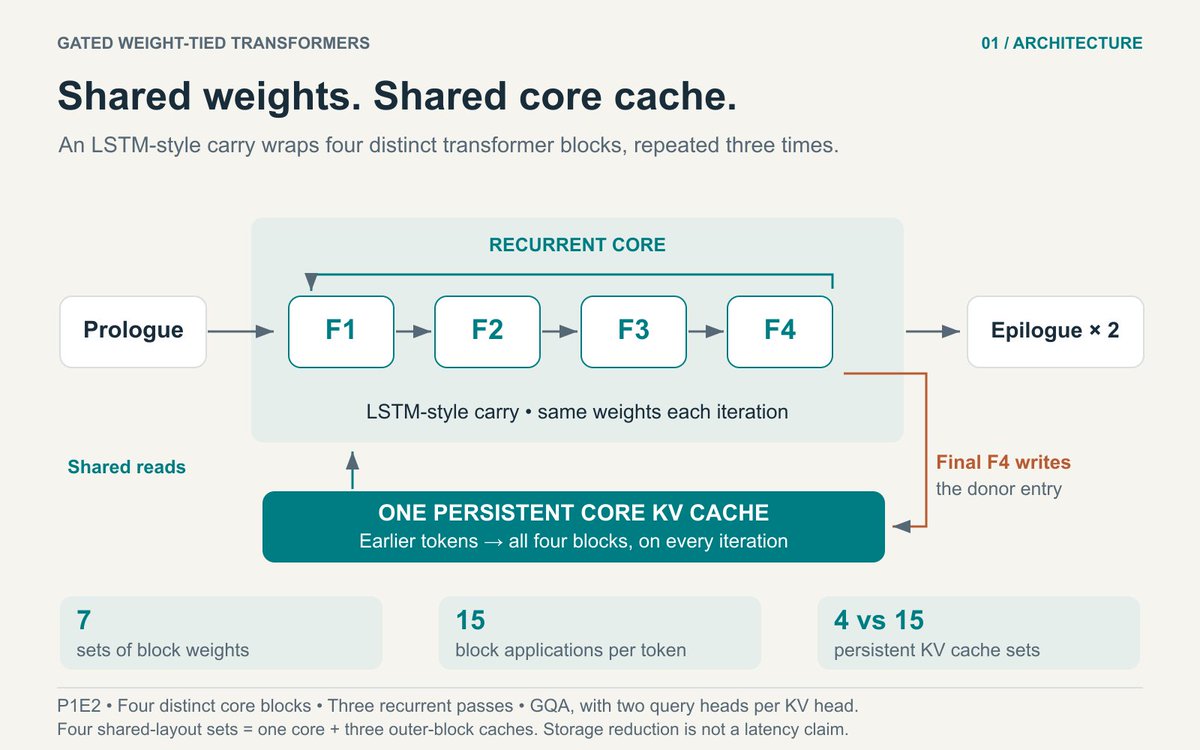
After leaving Google DeepMind, a researcher describes a short, compute-constrained project on a transformer with one shared core key-value cache. They say their two-pass training still produced cache histories that differed from those during continuation. Matching the passes’ donor keys and values during the final 10% of training removed 81–89% of the primary continuation penalty at three tested widths, they report. The token budget stayed the same, while full-cache loss rose by 0.0011–0.0025 nats.
Combined views
2.6K
5 Sources, first seen ago