• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

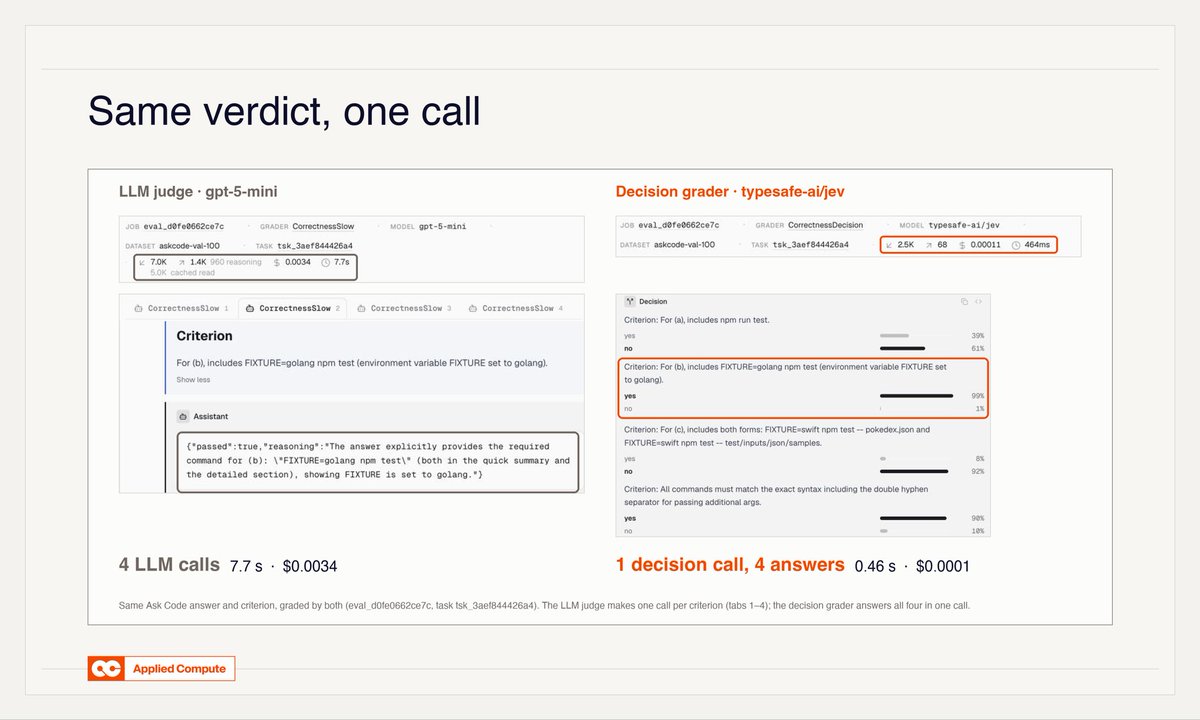
    Decision grader is reportedly ~32× cheaper than an LLM judge in a code QA test

    A user describing Applied Compute’s test says it was ~8× faster, with 94% agreement across 407 criteria.

    Yash PatilYP
    Rahil VermaRV
    2 Sources, ,

    TLDR

    A user describing Applied Compute’s AC2 code QA benchmark says a decision grader was ~32× cheaper and ~8× faster than an LLM judge on the same answers across 100 sample tasks (407 criteria), with 94% agreement. It returned yes/no probabilities for every criterion in one call. The user says confident results matched the LLM judge 99% of the time, while low-confidence results helped identify ambiguous rubric items.

    Combined views

    9.5K

    2 Sources, first seen 3h ago

    Combined views

    9.5K

    2 Sources, first seen 3h ago

    169 likes
    3h ago
    first seen 3h ago
    169 likes
    11 comments
    154 saves
    12 reposts
    11 comments
    154 saves
    12 reposts
    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    Rahil Verma@RahilVerma13At Applied Compute most of our RL and eval pipelines grade with an LLM judge. These produce one result per rubric criterion, typically a paragraph of text accompanying a score. For some complicated tasks, grading can be a slow, pricey part of the loop. We swapped a grader on a code QA benchmark in AC2 for a decision grader: one call, a yes/no probability for every criterion at once. On 100 sample tasks (407 criteria), same answers: → ~32× cheaper → ~8× faster → 94% agreement with the LLM judge And it’s even better than the original judge: When the decision grader was confident, it matched the LLM judge 99% of the time. When it wasn't, the decision grader indicated low confidence (30-70%), pointing to ambiguous rubric items. This allowed us to identify noisy tasks and make the dataset cleaner. A cheap, fast, calibrated grader means you can grade more rollouts, ask more questions per call, and downweight or review the shaky calls instead of training on them.3h
    Yash Patil@ypatil125RT @RahilVerma13: At Applied Compute most of our RL and eval pipelines grade with an LLM judge. These produce one result per rubric criteri…3h