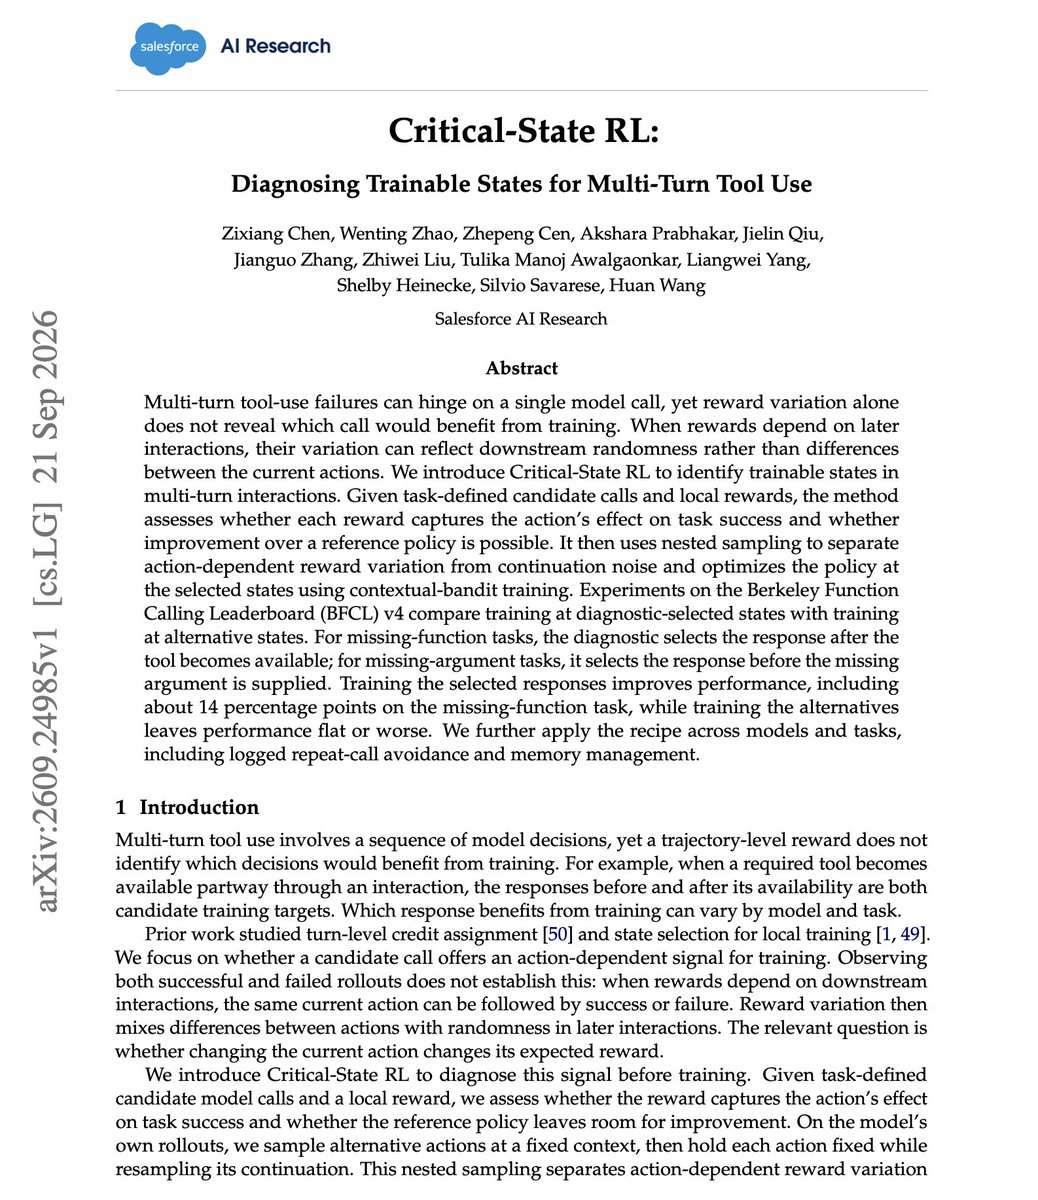
Training a selected tool call reportedly adds about 14 points on BFCL v4 missing-function tasks
A post about a Salesforce AI Research paper says Critical-State RL trains the tool call whose action changes the outcome, rather than spreading reward across the full sequence.
TLDR
A post about the paper says Critical-State RL uses nested sampling to separate the effect of a current tool call from what happens later, then trains the selected call. On BFCL v4 missing-function tasks, the post reports that training that turn added about 14 points; training another candidate turn left accuracy flat or lower.
Combined views
7.9K
2 Sources, first seen 14h ago