Report
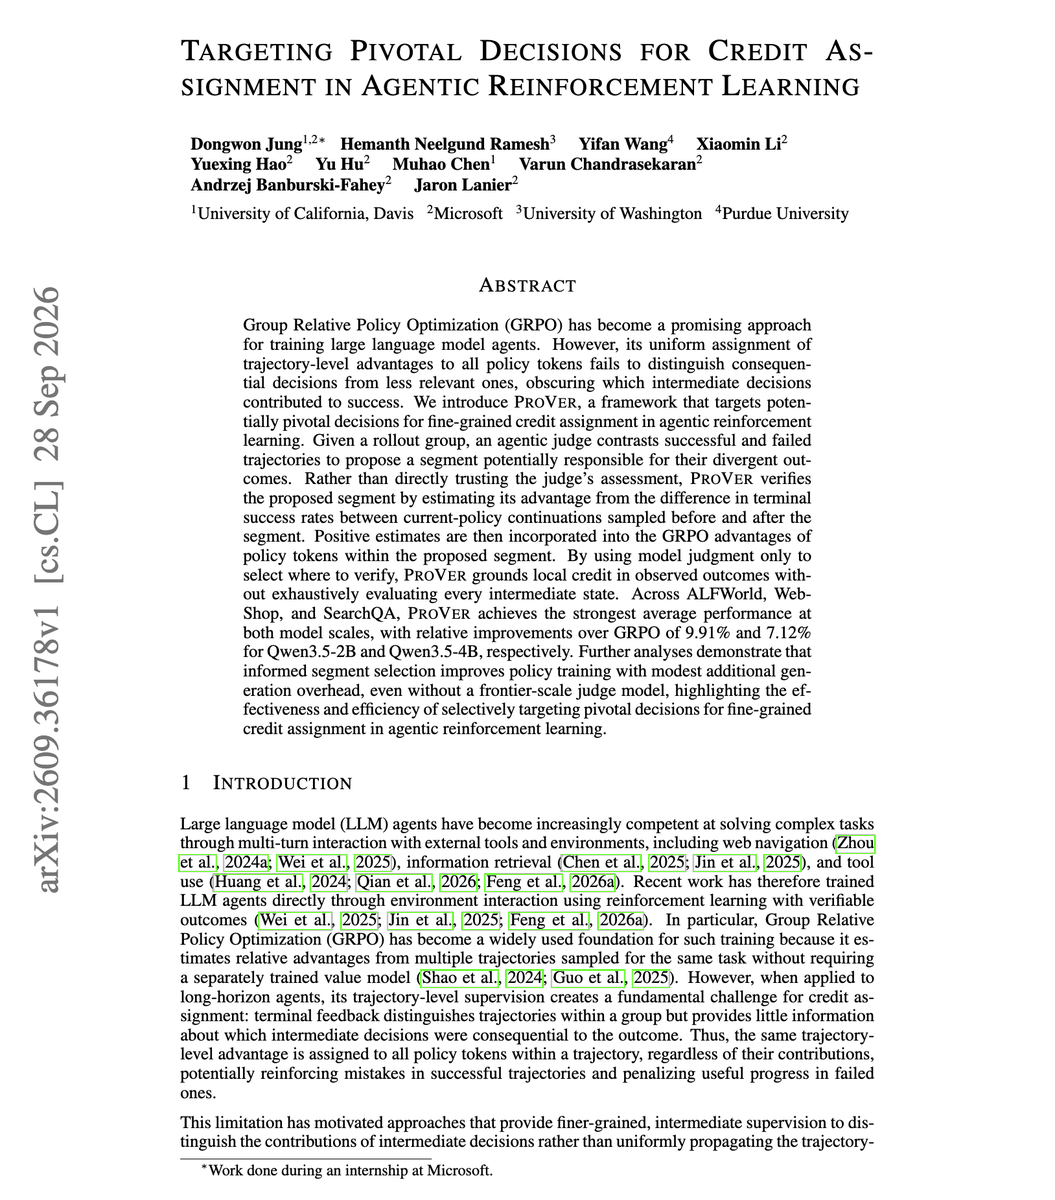
ProVer pairs an LLM judge with sampled rollouts to assign credit in agent RL
A post describing the paper says the judge selects a pivotal segment, while sampled continuations estimate its effect on success.
TLDR
A post describing the ProVer paper says GRPO gives every token in a trajectory the same advantage. ProVer instead has an LLM judge compare successful and failed rollouts to select a segment, then samples continuations from before and after it to estimate its advantage. Across ALFWorld, WebShop and SearchQA, the post reports relative improvements over GRPO of 9.91% for Qwen3.5-2B and 7.12% for Qwen3.5-4B. It says a smaller judge still helps.
Combined views
1 Source, first seen ago