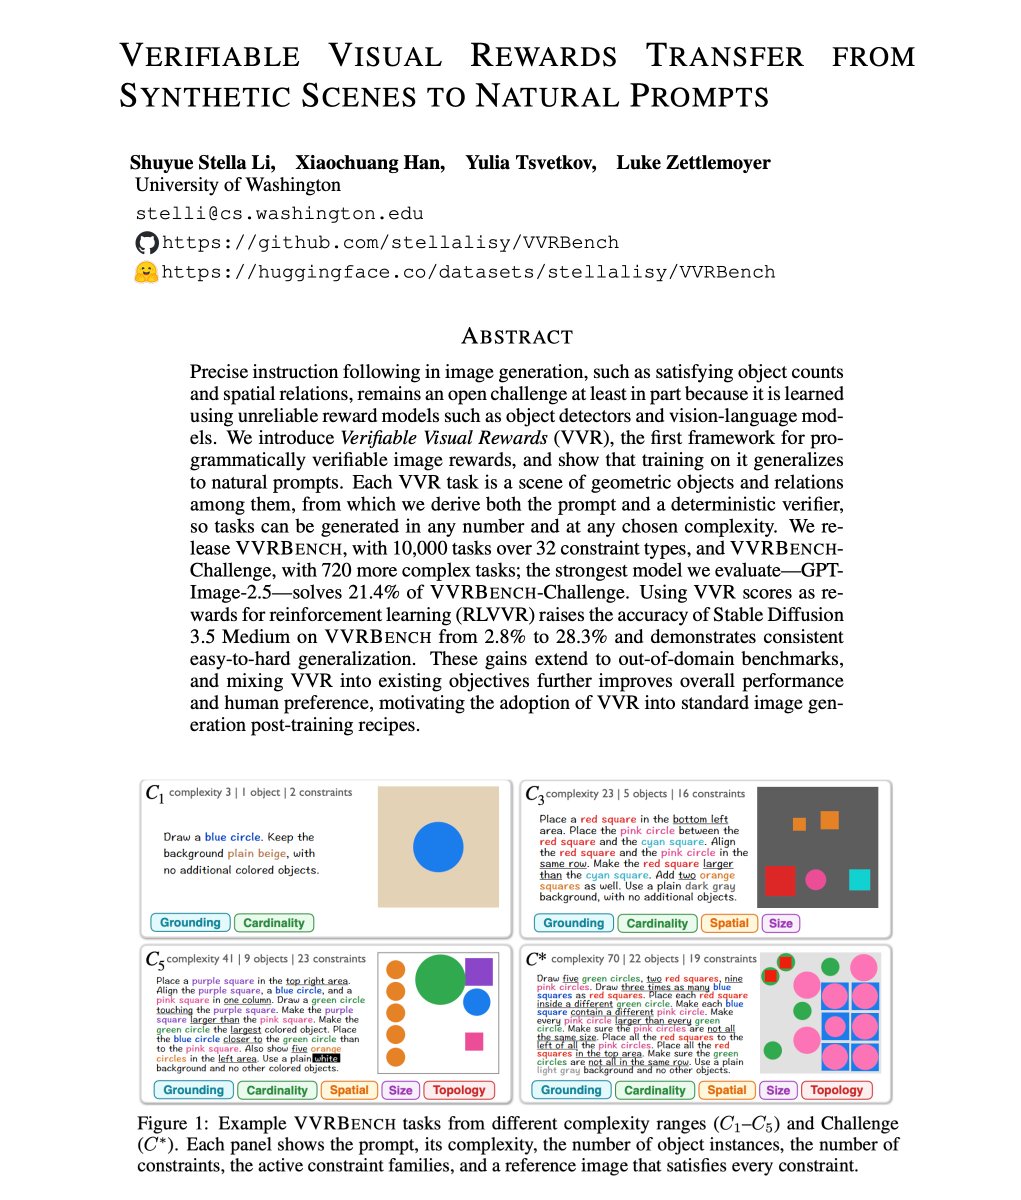
VVRBench tests image generators on counting and spatial instructions
Its creator says the benchmark pairs 10,000 synthetic scene instructions with program verifiers. They report that frontier API models scored at most 22% on a harder challenge set.
TLDR
VVRBench’s creator says image generators struggle with instructions about counts and spatial relationships. They report that frontier API models scored at most 22% on the harder VVRBench-Challenge set. They also say post-training with Visual Verifiable Rewards improved benchmark performance, generalized to harder prompts and improved standard image-generation evaluations.
Combined views
2K
8 Sources, first seen 2h ago