Report
LLM generalization may swing during pre-training despite stable training loss
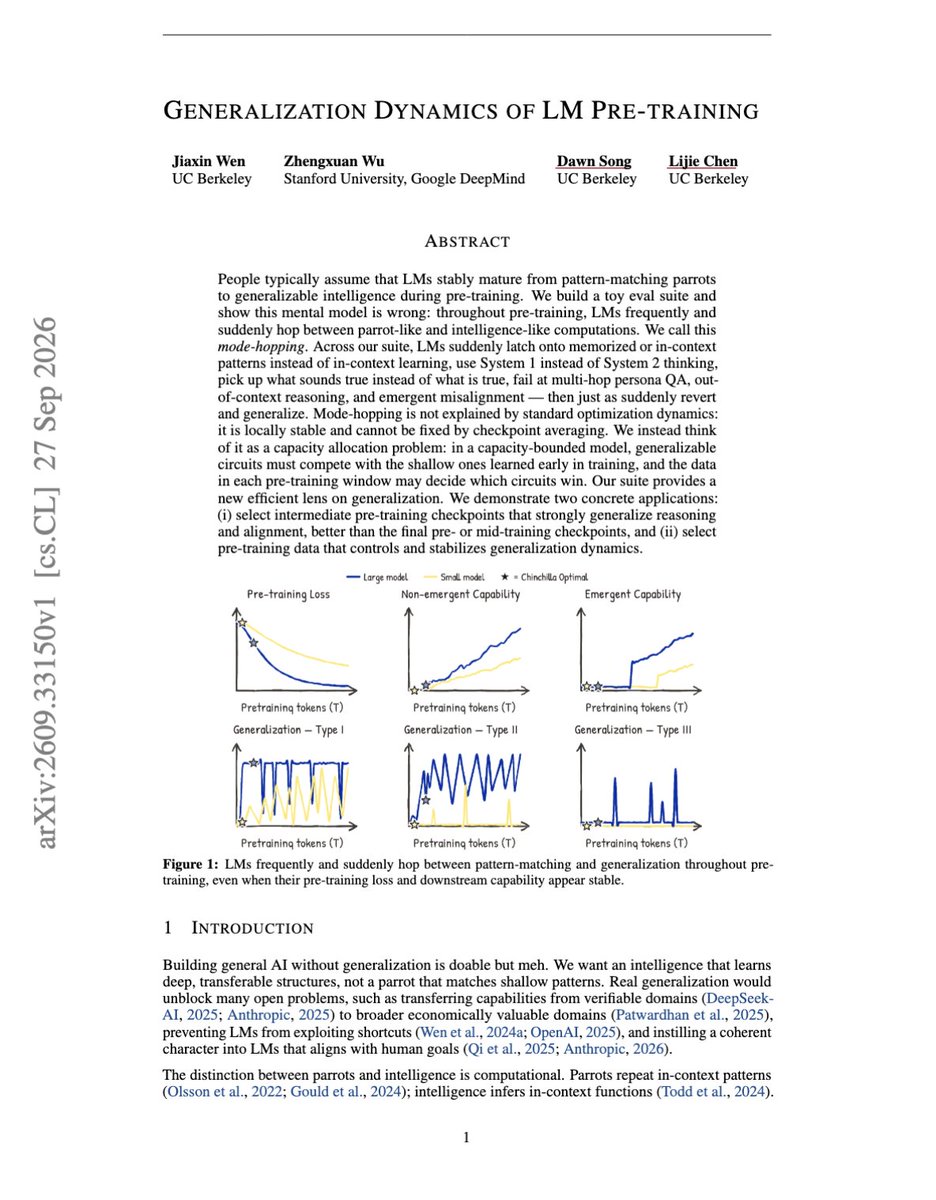
askalphaxiv shares a paper describing “mode-hopping,” in which LLMs repeatedly shift between shallow pattern-matching and generalization.
TLDR
askalphaxiv says the paper found that OLMo3-32B’s accuracy fell from 81% to 0%, then rose to 81.7% within 40 billion training tokens. The post also says selecting an earlier 4.5-trillion-token checkpoint instead of a 4.9-trillion-token one improved GPQA transfer after math fine-tuning (36.3% vs. 29.8%) and robustness to alignment attacks (53% vs. 21%).
Combined views
9.5K
3 Sources, first seen 8h ago