Announcement
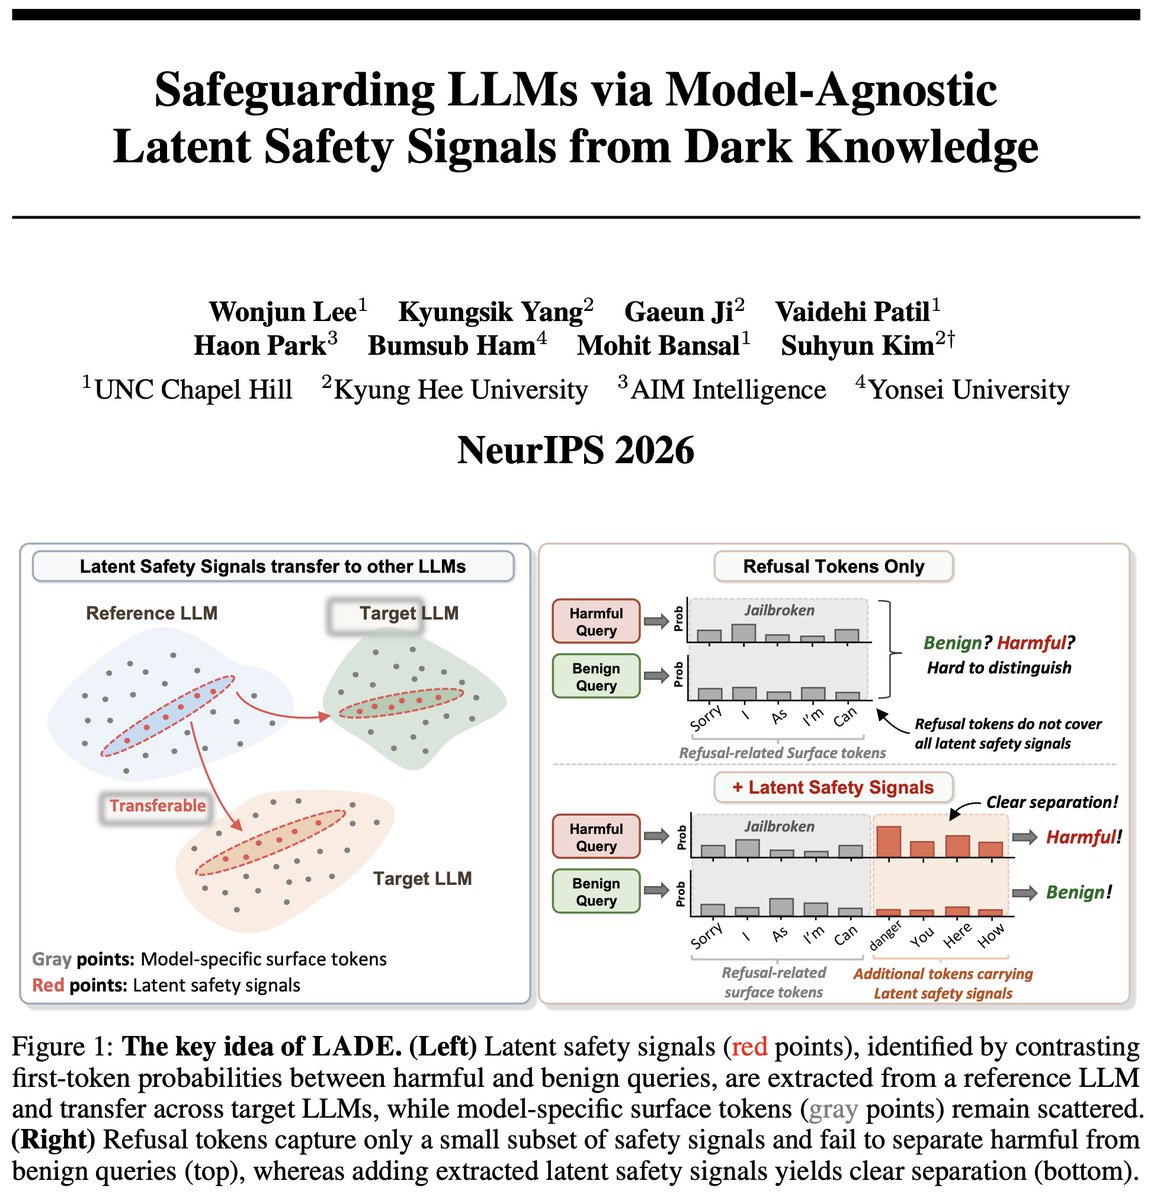
LADE is designed to flag harmful LLM prompts before generation begins
The researchers say LADE uses first-token probabilities to detect harmful prompts without accessing a model’s internal hidden states.


TLDR
Researchers introducing LADE in a NeurIPS 2026 paper say it uses a k-nearest-neighbors classifier to identify harmful prompts before an LLM generates text. They report 96.6% average accuracy at distinguishing harmful from benign queries across the reference–target model pairs they tested. They also say it performs well against several jailbreak attacks while keeping over-refusal low.
Combined views
1.3K
4 Sources, first seen ago