Report
GLM 5.3 Flash update goes live on RunInfra with AMD support
RunInfra says it rewrote the model’s kernels in September and now runs it on AMD with the same API. It reported a 99.7% cache hit rate for the 24 hours before its September 30 announcement.
TLDR
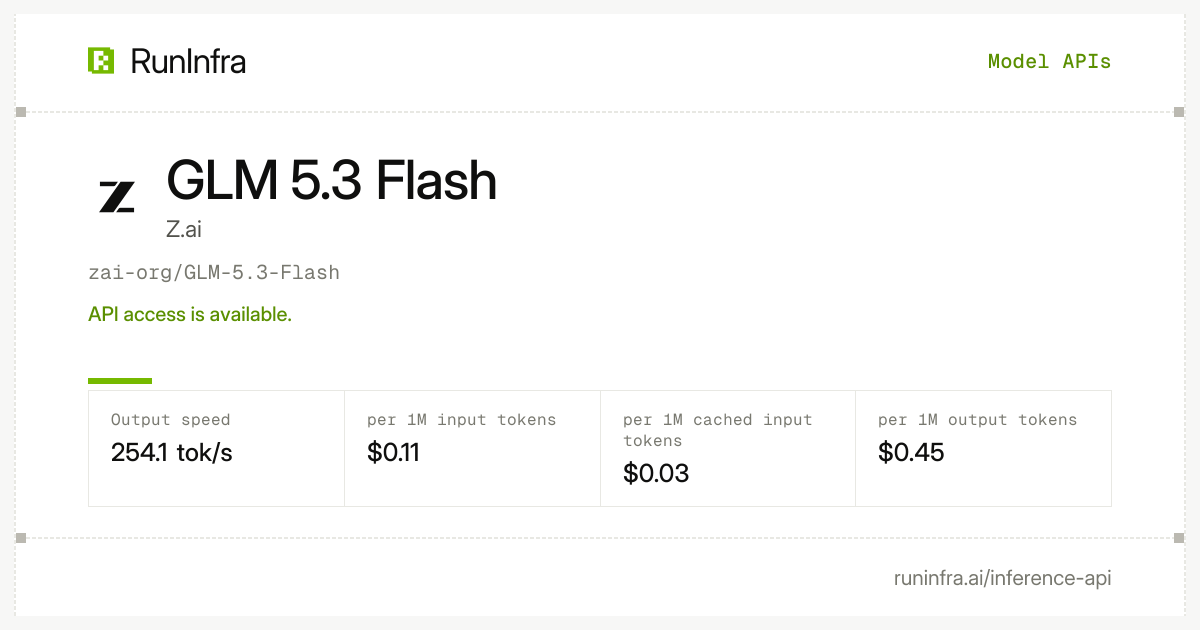
RunInfra announced a GLM 5.3 Flash release on September 30. It says the model now runs on AMD with the same API, claims 670 tokens per second on Vercel AI Gateway, and lists a 1M-token context window. Its posted prices are $0.11 per 1M input tokens, $0.45 per 1M output tokens and $0.03 per 1M cached tokens.
Combined views
1.3K
1 Source, first seen 8h ago