AI
Wispr Flow introduces Canto, a speech model for real-time dictation
Wispr Flow says Canto achieved a 3.4% word error rate—the lowest among the models it tested—in its evaluation of English Flow dictations.
TLDR
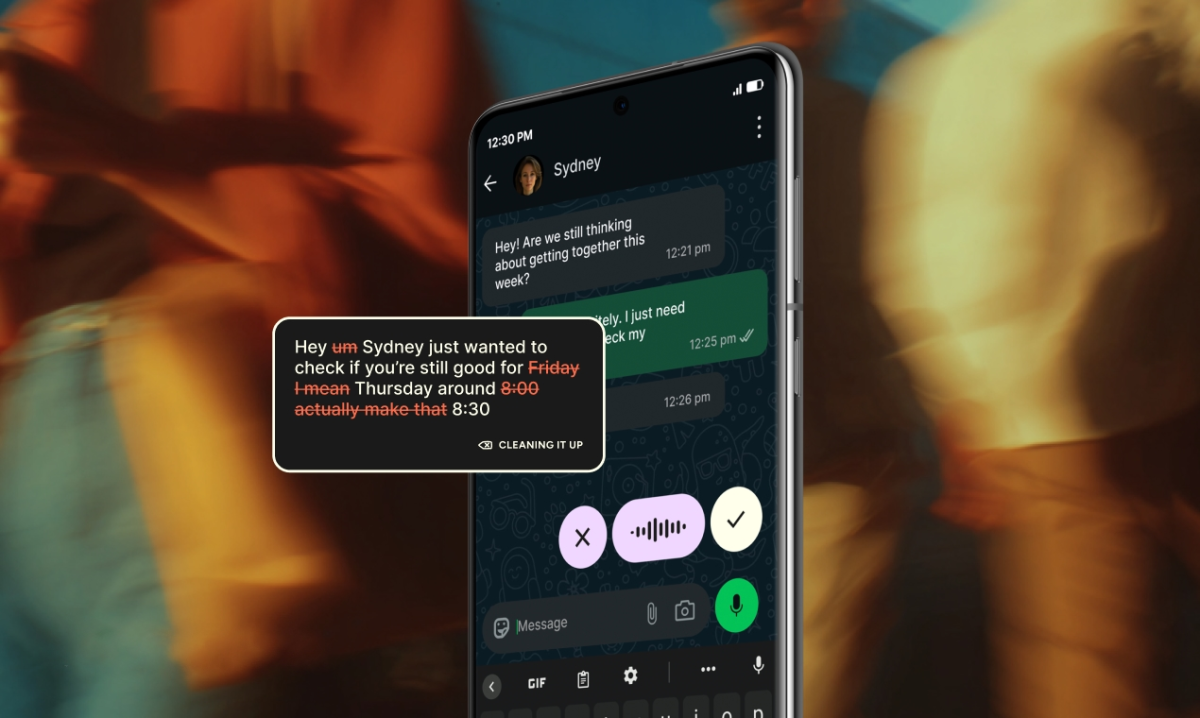
Wispr Flow has announced Canto, its latest speech model for real-time dictation. The company says its evaluation used 9.8 hours of English Flow dictations from more than 2,300 speakers. Canto achieved a 3.4% word error rate in that test, which Wispr Flow says was the lowest among the models it evaluated.
Combined views
11.5K
1 Source, first seen 10h ago
Wispr Flow introduces Canto, a speech model for real-time dictation
Wispr Flow says Canto achieved a 3.4% word error rate—the lowest among the models it tested—in its evaluation of English Flow dictations.
TLDR
Wispr Flow has announced Canto, its latest speech model for real-time dictation. The company says its evaluation used 9.8 hours of English Flow dictations from more than 2,300 speakers. Canto achieved a 3.4% word error rate in that test, which Wispr Flow says was the lowest among the models it evaluated.