• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

    Hybrid language models reportedly rely heavily on attention, even after supervised fine-tuning

    The author reports that encouraging recurrent memory use improved performance, especially on long-context tasks.

    Mohit BansalMB
    Elias Stengel-EskinES
    hyunji amy leeHA
    6 Sources, ,

    TLDR

    The author says recurrent–attention hybrid language models, such as Qwen3.5, rely heavily on attention even after supervised fine-tuning. They report that encouraging recurrent memory use improved performance, particularly on long-context tasks, with average gains of 4.6% on question answering and 12.1% on agentic tasks. They also report a 28.6% gain for attention-only models with multiple memory types.

    Combined views

    1.3K

    6 Sources, first seen 2h ago

    Combined views

    1.3K

    6 Sources, first seen 2h ago

    34 likes
    2h ago
    first seen 2h ago
    34 likes
    1 comments
    5 saves
    30 reposts
    Featured Source
    1 comments
    5 saves
    30 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    6 Sources

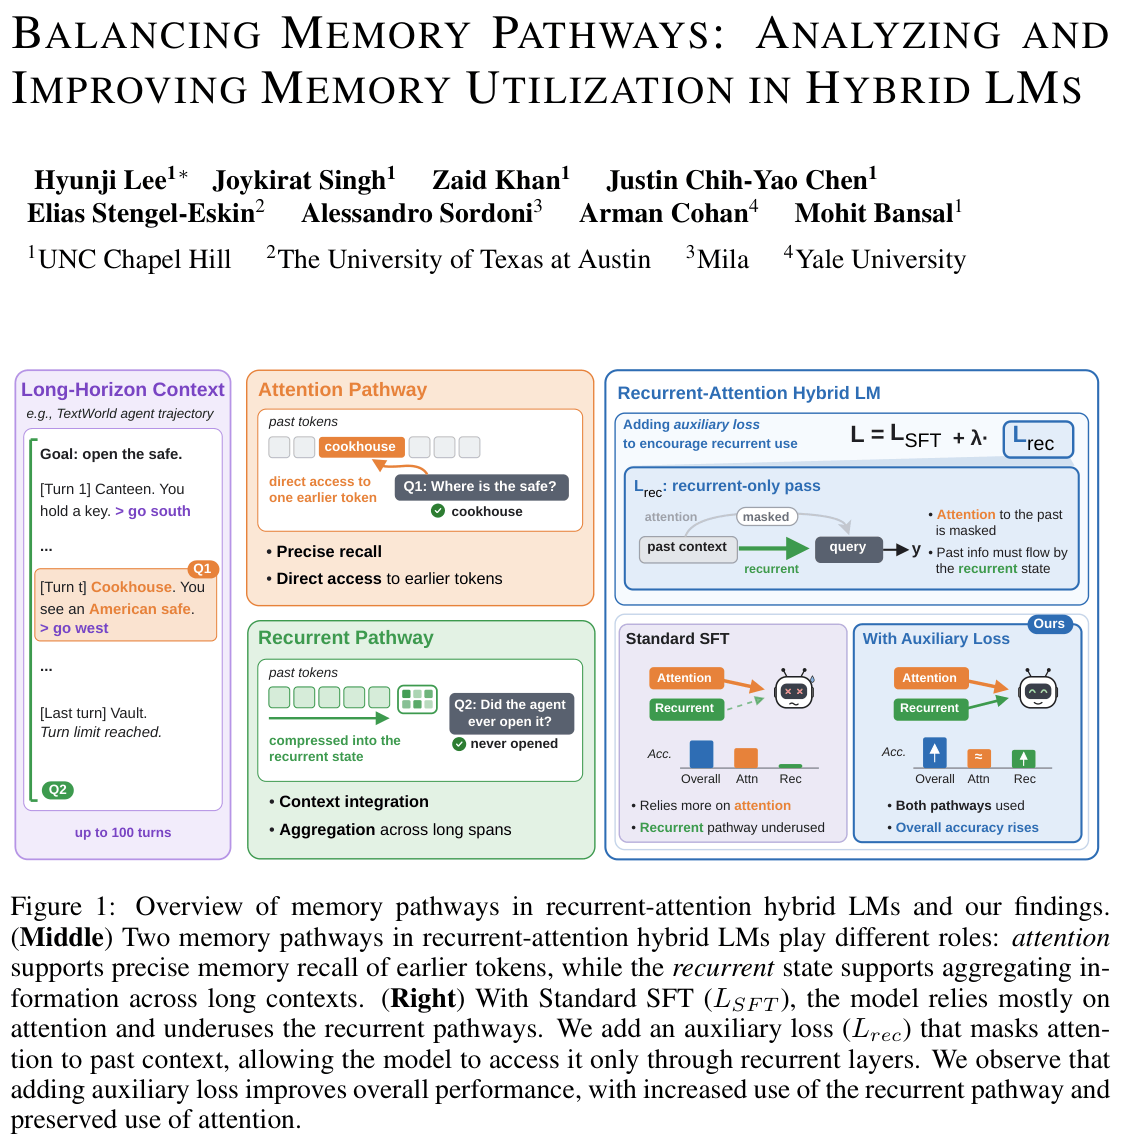
    hyunji amy lee@hyunji_amy_leeRecurrent–attention hybrid LMs (e.g., Qwen3.5) have two complementary memory pathways: attention and recurrence. But do they use both effectively? ❌ We find that they rely heavily on attention, even after SFT. 💡 We show that encouraging recurrent memory use improves performance (esp. on long-context tasks)! 🌐 Strong generalization across: - Multiple hybrid LMs - Question answering (avg. 4.6% ⬆️) and agentic tasks (avg. 12.1% ⬆️) - Attention-only models with multiple memory types (28.6% ⬆️)2h
    Elias Stengel-Eskin@EliasEskinRT @hyunji_amy_lee: Recurrent–attention hybrid LMs (e.g., Qwen3.5) have two complementary memory pathways: attention and recurrence. But do…2h
    Zaid Khan@codezakhNext-gen hybrid LLMs (e.g. Qwen-3.5) mix recurrent layers with attention. We show that naively SFT’ing makes them ignore the recurrent pathway and rely mostly on attention, which is suboptimal because each pathway excels at different operations needed for long-context tasks. Specifically, attention is good at needle-in-a-haystack exact retrieval, while the recurrent state is good at aggregating information distributed across a long context. To fix this during fine-tuning, we run a second forward pass where the attention layers are masked so the output tokens can't attend to the earlier context, while the recurrent layers still see the full sequence. If you apply the standard next-token loss to this pass, it forces the model to learn to use the recurrent state. This improves performance substantially on long-context QA and agentic tasks! See thread for details 👇1h
    Mohit Bansal@mohitban47RT @codezakh: Next-gen hybrid LLMs (e.g. Qwen-3.5) mix recurrent layers with attention. We show that naively SFT’ing makes them ignore the…1h
    Joykirat @COLM@joykiratsinghHaving two memory pathways ≠ using both! Attention is great at recall, and recurrent state is better than aggregating context spread across long contexts. But in practice, hybrid LMs (Qwen3.5, Nemotron-H) lean almost entirely on attention: blocking attention pathways collapses accuracy (30% → 5%), while blocking recurrent pathways (30% → 20%) barely hurts. Standard SFT only widens this gap. Our fix: A simple auxiliary pass where attention can't see the past and the model has to rely on its recurrent memory. Overall performance goes up, recurrent-only accuracy increases, and attention use is preserved, especially on long contexts, multi-evidence questions, and long-horizon agent tasks. 👇🧵1h