• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI
Announcement

DeepSeek V4.1 Flash joins AA-AgentPerf; Nvidia GB300 leads throughput per MW at 100 tokens/s per user

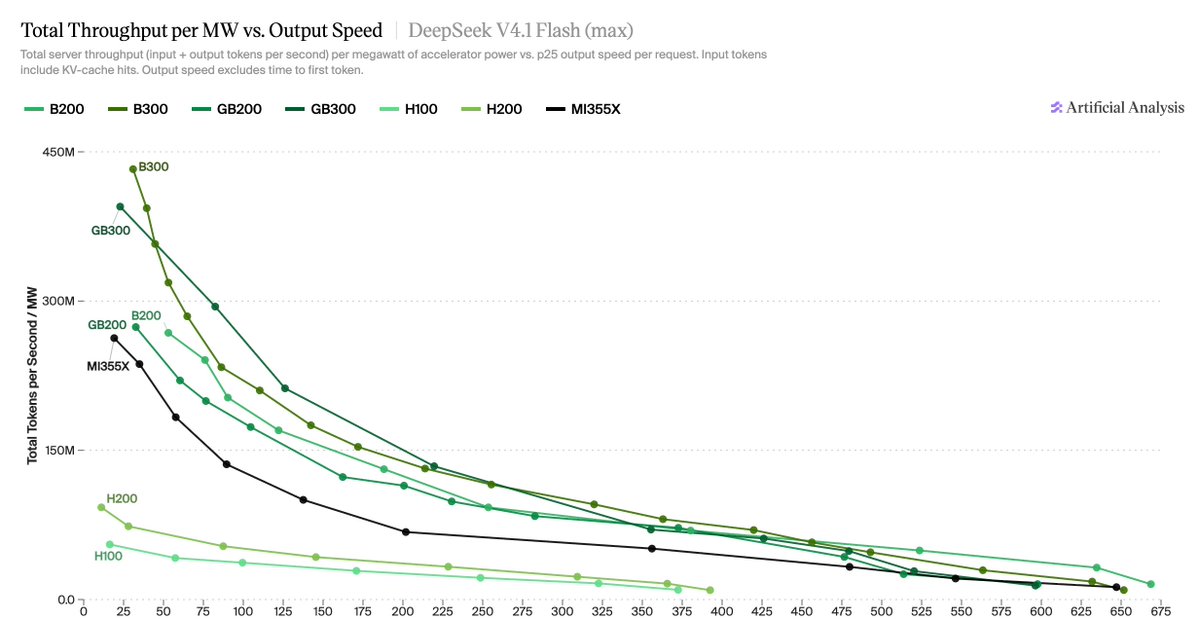
Artificial Analysis reports GB300 reached up to 261 million tokens/s per MW, ahead of B300's roughly 220 million.

Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)T(
2 Sources, 1h ago, first seen 1h ago

TLDR

Artificial Analysis added DeepSeek V4.1 Flash to AA-AgentPerf, its benchmark of agentic coding sessions with prompt caching and tool-call delays. At 100 tokens/s per user, it reports GB300 reached up to 261 million tokens/s per MW, versus about 220 million for B300 and 128 million for AMD's MI355X. It says V4.1 Flash scores 39 on its Intelligence Index, versus 36 for DeepSeek V4 Pro 0813, with about a third of the parameters.

Combined views

1.2K

2 Sources, first seen 1h ago

8 likes2 comments

Combined views

1.2K

2 Sources, first seen 1h ago

8 likes2 comments
Image: @ArtificialAnlys on X

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Featured Source

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

2 Sources

Artificial Analysis@ArtificialAnlysWe’ve added DeepSeek V4.1 Flash to AA-AgentPerf, with results for NVIDIA and AMD hardware. At 100 tokens/s per user, NVIDIA GB300 is in first place with throughput up to 261M tokens/s per MW. AA-AgentPerf is our agentic inference performance benchmark. It replays real agentic coding sessions, including prompt caching and tool-call delays, to give a realistic measure of inference performance in day-to-day agentic workloads. We measure total system throughput per megawatt of runtime power, and per-agent output speed at varying concurrency levels, to show the trade-off between system utilization and individual user experience. DeepSeek V4.1 Flash joins the leaderboard today. It brings the leaderboard to four featured models, joining DeepSeek V4 Pro 0813, Kimi K3, and GLM-5.2/5.3. We are evolving the featured models as popular new open-weights models release, and will feature day-0 results for major future releases. Background on DeepSeek v4.1 Flash: ➤ It scores 39 on the Artificial Analysis Intelligence Index, ahead of DeepSeek’s earlier V4 Pro 0813 at 36, with about a third of the parameters (552B ‘backbone’ and 16B active, against 1.6T and 49B) ➤ It is built on a new architecture, with a causal encoder-decoder design that activates 8B parameters per input token and 16B per output token. It uses a further 196B parameters of Engram n-gram memory that can sit in host memory rather than on the accelerator, and compressed sparse attention that needs about a quarter of even the earlier V4 Flash model’s KV cache per token ➤ This makes it much more efficient to serve, since the weights fit on fewer GPUs and the smaller KV cache leaves room for more concurrent agents per GPU Initial AA-AgentPerf results for DeepSeek V4.1 Flash: ➤ V4.1 Flash runs on as few as 2 GPUs, so rack-scale systems get less advantage over 8-GPU single nodes like B300, which stays within about 20% of rack-scale GB300 NVL72 across the curve, and leads at both ends ➤ At 100 tok/s per user, GB300 leads with ~261M tokens/s per MW, ahead of B300 (~220M), B200 (~193M), GB200 (~178M) and MI355X (~128M) ➤ Every Blackwell system and MI355X can reach around 600 to 670 tok/s output speed for a single agent (ie. at batch size of one), against 372 to 392 tok/s on H100 and H200 ➤ V4.1 Flash is both more intelligent than V4 Pro 0813 and much cheaper to serve, yielding ~1.3x (GB300) to ~6.2x (B200) the throughput per MW at 100 tok/s per user compared to its larger cousin1h
Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)@teortaxesTexRemarkably (though predictably) little gain for rack-scale systems1h
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI

    2 Sources

    Artificial Analysis@ArtificialAnlysWe’ve added DeepSeek V4.1 Flash to AA-AgentPerf, with results for NVIDIA and AMD hardware. At 100 tokens/s per user, NVIDIA GB300 is in first place with throughput up to 261M tokens/s per MW. AA-AgentPerf is our agentic inference performance benchmark. It replays real agentic coding sessions, including prompt caching and tool-call delays, to give a realistic measure of inference performance in day-to-day agentic workloads. We measure total system throughput per megawatt of runtime power, and per-agent output speed at varying concurrency levels, to show the trade-off between system utilization and individual user experience. DeepSeek V4.1 Flash joins the leaderboard today. It brings the leaderboard to four featured models, joining DeepSeek V4 Pro 0813, Kimi K3, and GLM-5.2/5.3. We are evolving the featured models as popular new open-weights models release, and will feature day-0 results for major future releases. Background on DeepSeek v4.1 Flash: ➤ It scores 39 on the Artificial Analysis Intelligence Index, ahead of DeepSeek’s earlier V4 Pro 0813 at 36, with about a third of the parameters (552B ‘backbone’ and 16B active, against 1.6T and 49B) ➤ It is built on a new architecture, with a causal encoder-decoder design that activates 8B parameters per input token and 16B per output token. It uses a further 196B parameters of Engram n-gram memory that can sit in host memory rather than on the accelerator, and compressed sparse attention that needs about a quarter of even the earlier V4 Flash model’s KV cache per token ➤ This makes it much more efficient to serve, since the weights fit on fewer GPUs and the smaller KV cache leaves room for more concurrent agents per GPU Initial AA-AgentPerf results for DeepSeek V4.1 Flash: ➤ V4.1 Flash runs on as few as 2 GPUs, so rack-scale systems get less advantage over 8-GPU single nodes like B300, which stays within about 20% of rack-scale GB300 NVL72 across the curve, and leads at both ends ➤ At 100 tok/s per user, GB300 leads with ~261M tokens/s per MW, ahead of B300 (~220M), B200 (~193M), GB200 (~178M) and MI355X (~128M) ➤ Every Blackwell system and MI355X can reach around 600 to 670 tok/s output speed for a single agent (ie. at batch size of one), against 372 to 392 tok/s on H100 and H200 ➤ V4.1 Flash is both more intelligent than V4 Pro 0813 and much cheaper to serve, yielding ~1.3x (GB300) to ~6.2x (B200) the throughput per MW at 100 tok/s per user compared to its larger cousin1h
    Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)@teortaxesTexRemarkably (though predictably) little gain for rack-scale systems1h
    Today's Rank

    #1

    Today's Rank

    #1