• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Reaction

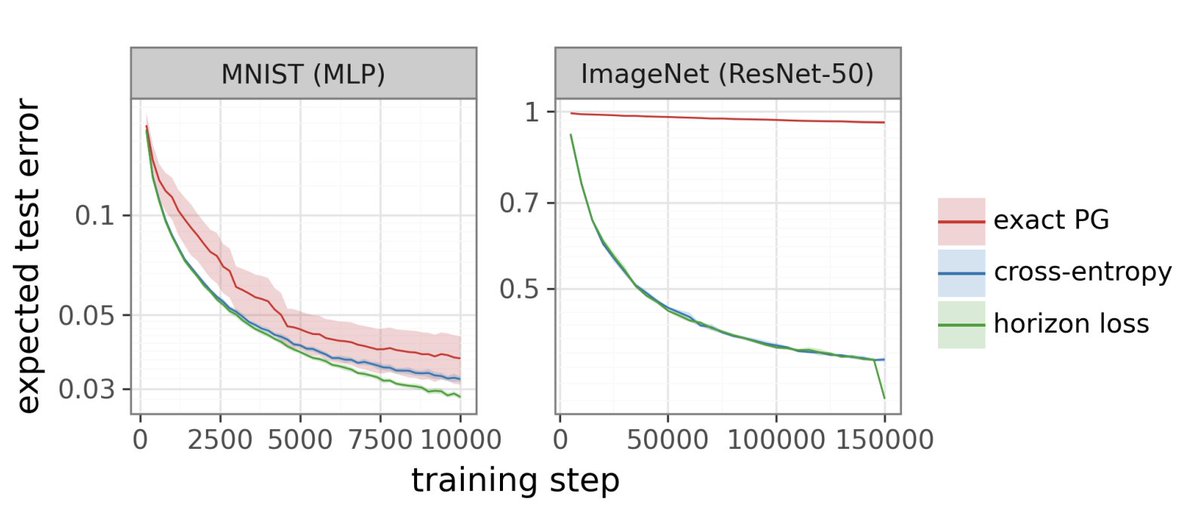
    Exact policy gradient is claimed to trail cross-entropy on ImageNet

    A user cites 4% for policy gradient versus 62% for cross-entropy on ImageNet, despite an exact gradient.

    IO
    4 Sources, 4h ago, first seen 4h ago

    TLDR

    A user argues that policy gradient can perform poorly even in image classification, where they say exploration, credit assignment and sampling noise are not factors. They cite 4% for policy gradient versus 62% for cross-entropy on ImageNet, describe a “horizon loss” tied to the remaining training budget, and claim a planning loss beats both approaches.

    Combined views

    10.8K

    4 Sources, first seen 4h ago

    Combined views

    10.8K

    4 Sources, first seen 4h ago

    177 likes
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    177 likes
    8 comments
    147 saves
    23 reposts
    Featured Source
    8 comments
    147 saves
    23 reposts

    4 Sources

    @IanOsbandIn LLM post-training, policy gradient is "the RL loss". When it fails, we blame the RL: exploration, credit assignment, sampling noise. Image classification has none of these, and the policy gradient is exact. Following it is terrible... ImageNet, 4% vs 62% for cross-entropy.4h

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    4 Sources

    @IanOsbandIn LLM post-training, policy gradient is "the RL loss". When it fails, we blame the RL: exploration, credit assignment, sampling noise. Image classification has none of these, and the policy gradient is exact. Following it is terrible... ImageNet, 4% vs 62% for cross-entropy.4h