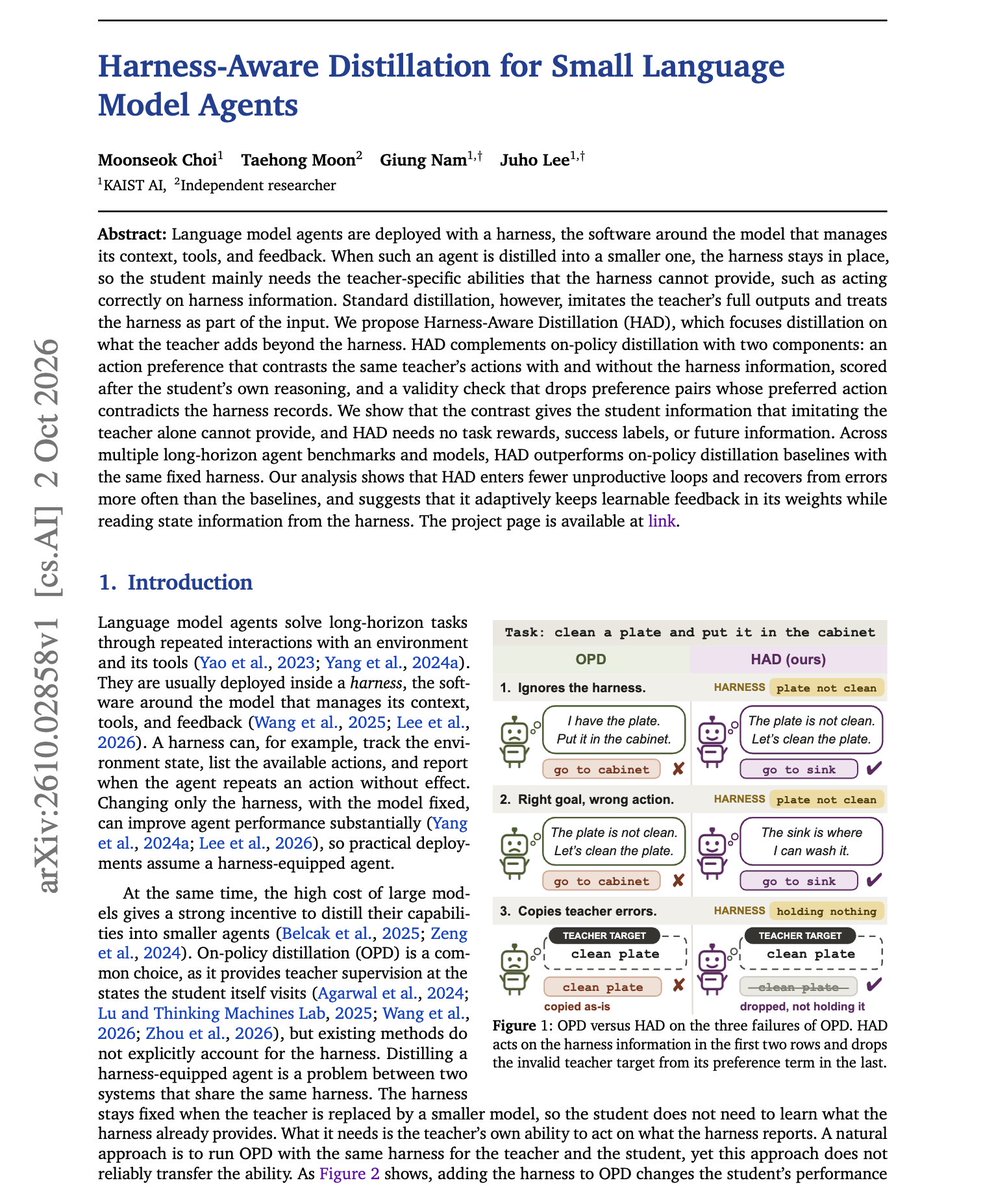
A small agent trained with harness-aware distillation reportedly reaches 63.4% success on unseen ALFWorld tasks
A post describing the paper says researchers compared a teacher’s actions with and without harness information, using no task rewards or success labels.

TLDR
A post describing the paper says adding harness information to on-policy distillation increased how often a small agent used it on ALFWorld, but barely changed task success. The researchers’ method instead trains the agent to prefer actions its teacher chose with harness information, filtering out choices that contradict harness records. The post reports 63.4% success on unseen tasks, versus 47.0% for the best baseline, and says the agent exceeded its 8B teacher.
Combined views
1 Source, first seen ago