Reaction
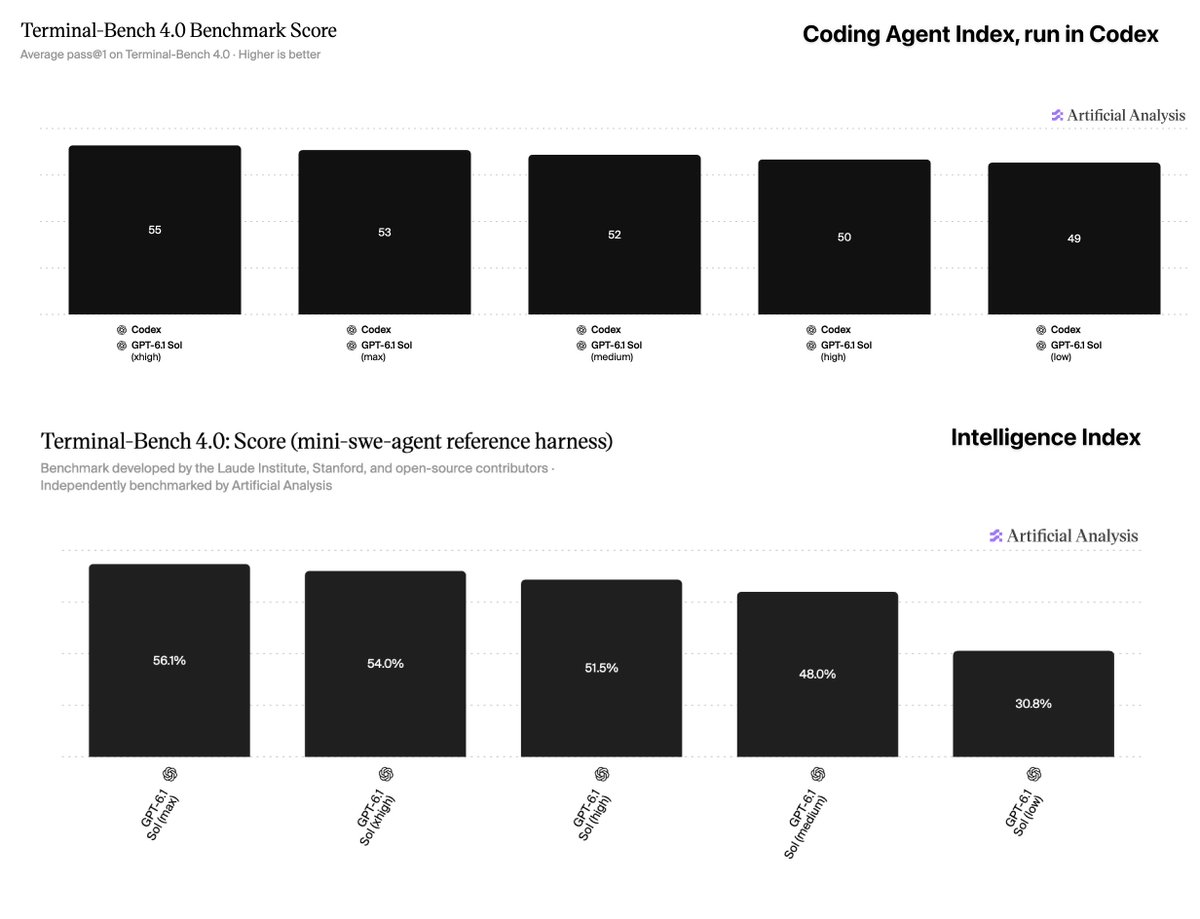
No significant Codex harness bump observed vs. reference in Terminal-Bench 4.0, except at low effort
ArtificialAnlys says it uses three repeats for its benchmark results. In a reply, another user asked whether the mini-swe-agent runs had vision/image tools, saying those tools made a huge difference in their own runs.
TLDR
ArtificialAnlys says its Terminal-Bench 4.0 results for the Codex and mini-swe-agent harnesses showed no significant Codex harness performance bump over its reference harness, except at the low-effort setting. It says it uses three repeats. Another user asked whether the mini-swe-agent runs had vision/image tools, which they said made a huge difference in their own runs.
Combined views
2.6K
1 Source, first seen 9h ago