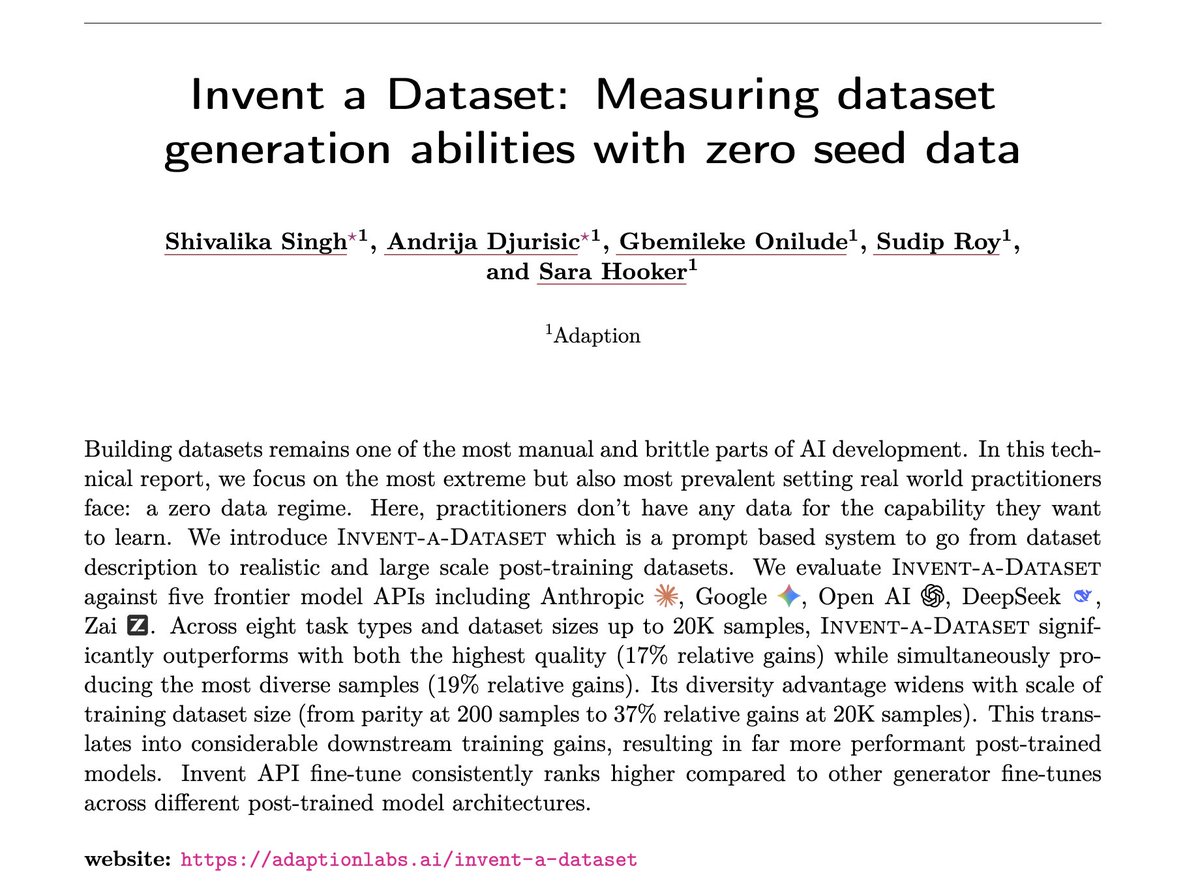
Adaption's Invent a Dataset promises task-specific training data without a seed corpus
Adaption says users can describe a task in natural language, with no upfront schema required.

TLDR
Adaption says Invent a Dataset generates task-specific training data from a task description, without requiring a schema or seed corpus. An October 1 launch post says a technical report evaluates the Invent API against proprietary and open-weight frontier LLMs for data generation. A later post says an Adaption team member made a video explainer.
Combined views
1.8K
2 Sources, first seen ago