• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI
Report

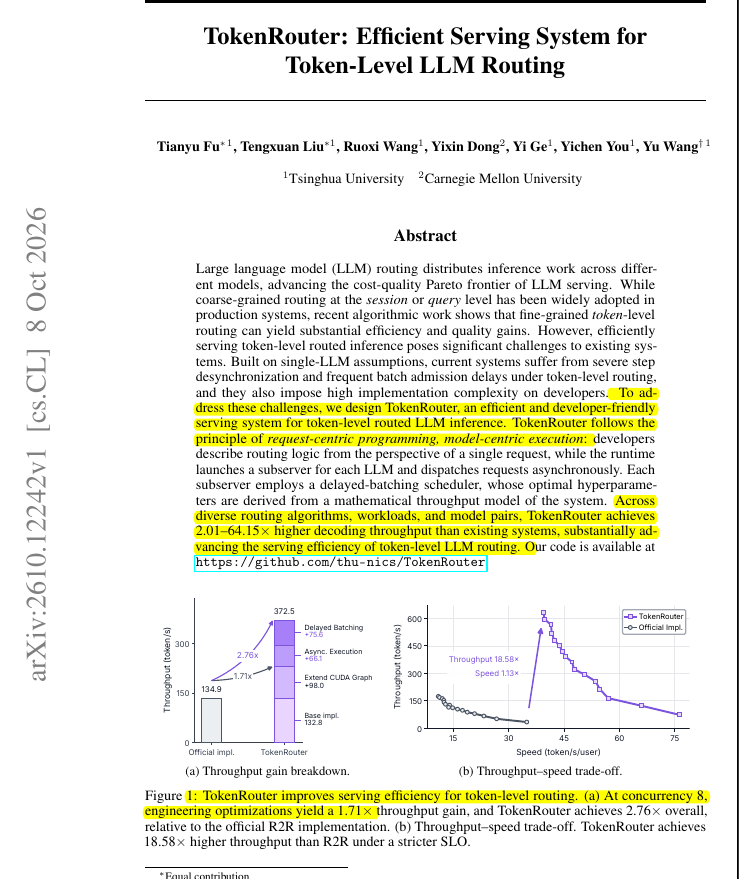
TokenRouter reportedly boosts throughput for per-token routing between small and large AI models

A post sharing the Tsinghua paper reports 2.01–64.15× the throughput of a stronger existing setup across five routing methods.

1 Source, 1h ago, first seen 1h ago

TLDR

A post sharing a new Tsinghua paper says TokenRouter gives small and large models separate servers and passes partly written answers between them while retaining the KV cache—the models’ memory of the text so far. It briefly holds requests so each model can work on larger batches. Across five routing methods, the post reports 2.01–64.15× the throughput of a stronger existing setup.

Combined views

—

1 Source, first seen 1h ago

— likes— comments— saves— reposts

Combined views

—

1 Source, first seen 1h ago

— likes— comments— saves— reposts

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Featured Source

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

1 Source

Rohan Paul@rohanpaul_aiNew Tsinghua paper builds TokenRouter, a serving system that runs per-token small-and-large model routing at upto 64.15X the throughput of existing setups. Current popular serving frameworks (like vLLM and SGLang) run one model per request, so when two models share an answer, every step waits for the slower one. TokenRouter gives each model its own server and lets them pass work back and forth. So, it hands a half-written answer between them while keeping the model’s memory of the text so far (the KV cache), and holds requests for a moment so each model works on bigger batches. Across 5 routing methods, throughput rose 2.01 to 64.15 times over the stronger existing setup. – arxiv. org/abs/2610.12242 Title: "TokenRouter: Efficient Serving System for Token-Level LLM Routing"1h
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI

    1 Source

    Rohan Paul@rohanpaul_aiNew Tsinghua paper builds TokenRouter, a serving system that runs per-token small-and-large model routing at upto 64.15X the throughput of existing setups. Current popular serving frameworks (like vLLM and SGLang) run one model per request, so when two models share an answer, every step waits for the slower one. TokenRouter gives each model its own server and lets them pass work back and forth. So, it hands a half-written answer between them while keeping the model’s memory of the text so far (the KV cache), and holds requests for a moment so each model works on bigger batches. Across 5 routing methods, throughput rose 2.01 to 64.15 times over the stronger existing setup. – arxiv. org/abs/2610.12242 Title: "TokenRouter: Efficient Serving System for Token-Level LLM Routing"1h
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet