AI
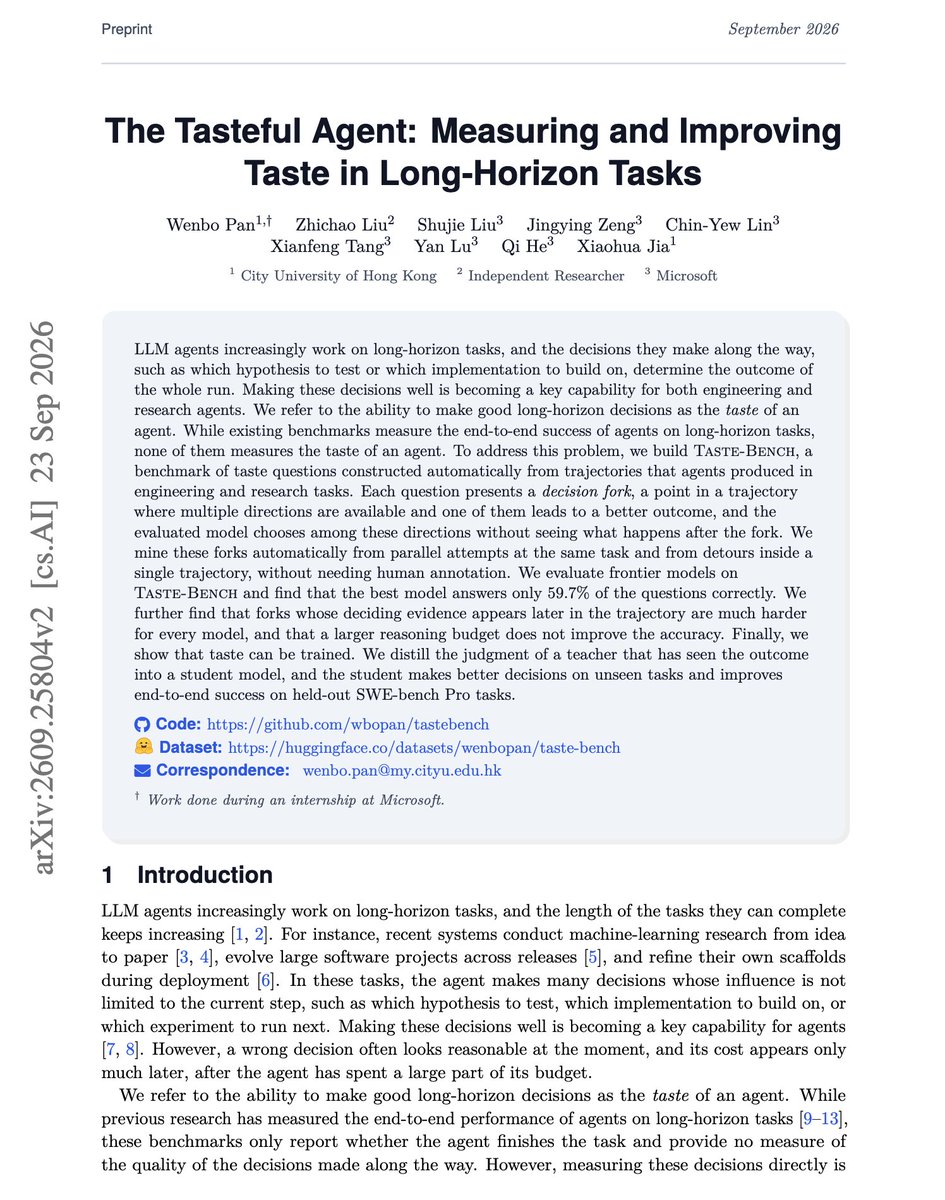
Taste-Bench’s best model reportedly picks the better path 59.7% of the time
A post describing a paper from Microsoft and colleagues says the benchmark tests AI agents at decision points in long tasks. Giving models a larger reasoning budget did not improve accuracy, it says.
TLDR
A post describing a paper from Microsoft and colleagues reports that the best model answered 59.7% of Taste-Bench questions correctly. The benchmark draws decision points from parallel attempts and detours in engineering and research tasks, asking agents to choose the direction that leads to a better outcome. The post says questions were much harder when the deciding evidence appeared later in the task, and a larger reasoning budget did not raise accuracy. It also says the authors distilled a teacher’s judgments about outcomes into a student model, improving end-to-end success on held-out SWE-bench Pro tasks.