• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Composite rewards reportedly improve FLUX.2-dev and Ideogram 4 after post-training

    Arena says its recipe pairs a human-preference model with rewards for prompt faithfulness, user constraints and avoiding reward-hacking.

    AR
    CT
    2 Sources, ,

    TLDR

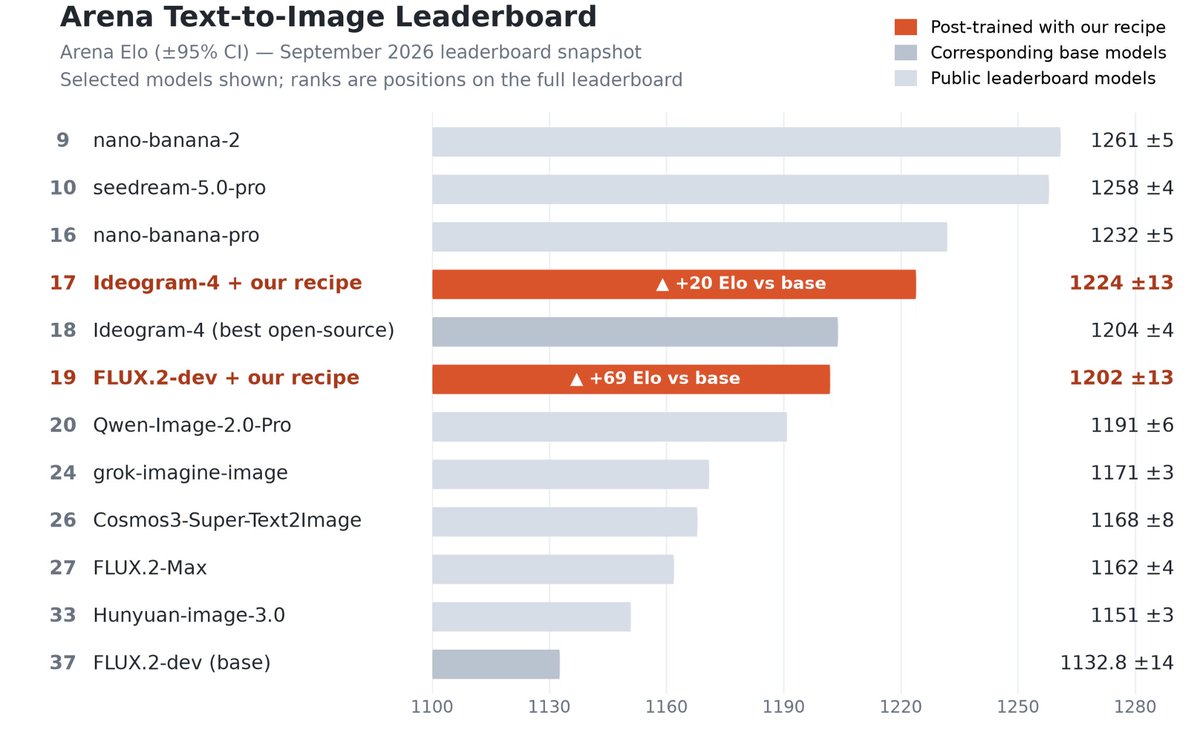
    Arena says its approach combines a preference model trained on about 5.6 million pairwise human votes with faithfulness, constraint and anti-reward-hacking rewards. It reports that post-training raised FLUX.2-dev by 69 Elo points to 1202 and Ideogram 4 by 20 points to 1224 on its live text-to-image leaderboard. Arena said Ideogram 4 surpassed all publicly listed open models as of September 4, 2026. In offline tests judged by Gemini 3.5 Flash, it reports a 64.2% win rate against the base model after adding faithfulness and constraint rewards, rising to 66.0% with a weight-space ensemble.

    Combined views

    12K

    2 Sources, first seen 4h ago

    Combined views

    12K

    2 Sources, first seen 4h ago

    98 likes
    4h ago
    first seen 4h ago
    98 likes
    13 comments
    18 saves
    9 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source
    13 comments
    18 saves
    9 reposts

    2 Sources

    @arenaHow to design rewards for post-training frontier image models? Our research suggests human preference reward is necessary, but insufficient: A preference model may still reward outputs that look appealing but miss details, introduce unrequested content, or exhibit other forms of reward-hacking. We therefore optimize towards a composite reward: - Bradley-Terry reward model trained on ~5.6M pairwise human votes - Faithfulness reward from auto-generated prompt checklists evaluated by a vision-language model - Constraint reward covering explicit and implicit user intent - Anti-reward-hacking rubric rewards targeting failures such as garbled text and photorealism drift This post-training recipe improves two already-strong open image models: - Post-trained FLUX.2-dev gains 69 Elo points on our live T2I leaderboard, scoring 1202 - Post-trained Ideogram 4 gains 20 Elo points reaching a score of 1224 and surpassing all publicly listed open models (as of Sep 04, 2026). Offline ablations with Gemini 3.5 Flash as the judge, show that these reward components are complementary: win rate against the base model increases as we add faithfulness and then constraint rewards on top of preference-only training, reaching 64.2%. Finally, we ensemble policies trained with and without the anti-reward-hacking objective directly in weight space, further increasing win rate to 66.0%.4h
    @cthorrezarena RMs are SotA :)1h

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet

    2 Sources

    @arenaHow to design rewards for post-training frontier image models? Our research suggests human preference reward is necessary, but insufficient: A preference model may still reward outputs that look appealing but miss details, introduce unrequested content, or exhibit other forms of reward-hacking. We therefore optimize towards a composite reward: - Bradley-Terry reward model trained on ~5.6M pairwise human votes - Faithfulness reward from auto-generated prompt checklists evaluated by a vision-language model - Constraint reward covering explicit and implicit user intent - Anti-reward-hacking rubric rewards targeting failures such as garbled text and photorealism drift This post-training recipe improves two already-strong open image models: - Post-trained FLUX.2-dev gains 69 Elo points on our live T2I leaderboard, scoring 1202 - Post-trained Ideogram 4 gains 20 Elo points reaching a score of 1224 and surpassing all publicly listed open models (as of Sep 04, 2026). Offline ablations with Gemini 3.5 Flash as the judge, show that these reward components are complementary: win rate against the base model increases as we add faithfulness and then constraint rewards on top of preference-only training, reaching 64.2%. Finally, we ensemble policies trained with and without the anti-reward-hacking objective directly in weight space, further increasing win rate to 66.0%.4h
    @cthorrezarena RMs are SotA :)1h