Reaction
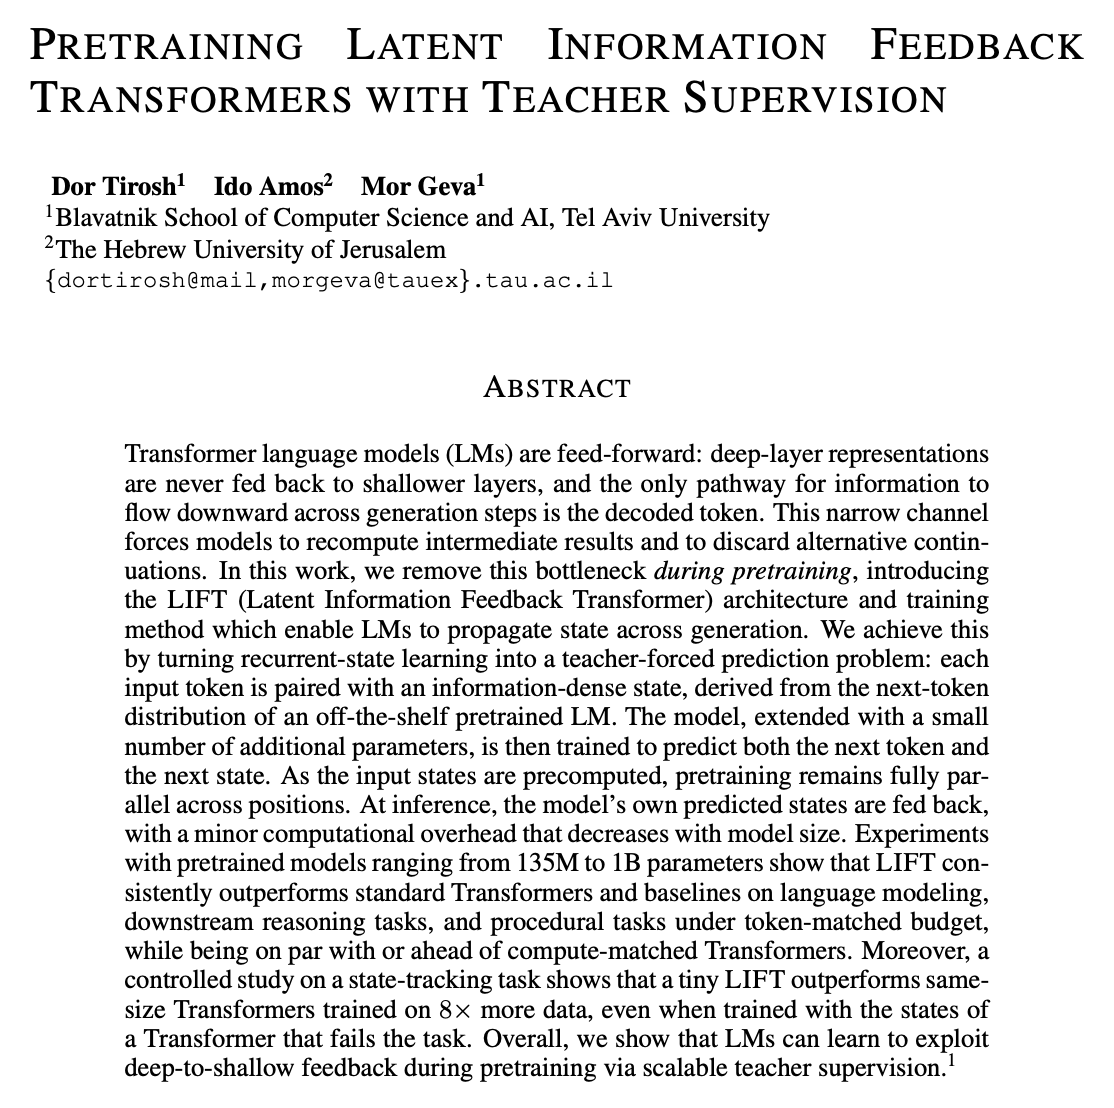
LIFT proposes deep-to-shallow feedback in Transformers while keeping pretraining parallel
A post introducing the preprint says LIFT uses teacher-supervised training to tackle a bottleneck in how language models pass information between layers.
TLDR
The post introducing LIFT says its Transformer architecture and teacher-supervised training let information flow from deeper to shallower layers while preserving parallel training. It claims LIFT outperformed standard Transformers and other baselines on language modeling, reasoning and procedural tasks under a token-matched budget, and matched or beat compute-matched Transformers. Another user called the approach a promising way to explore abilities associated with recurrent and state-space models.
Combined views
302
1 Source, first seen 8h ago