Announcement
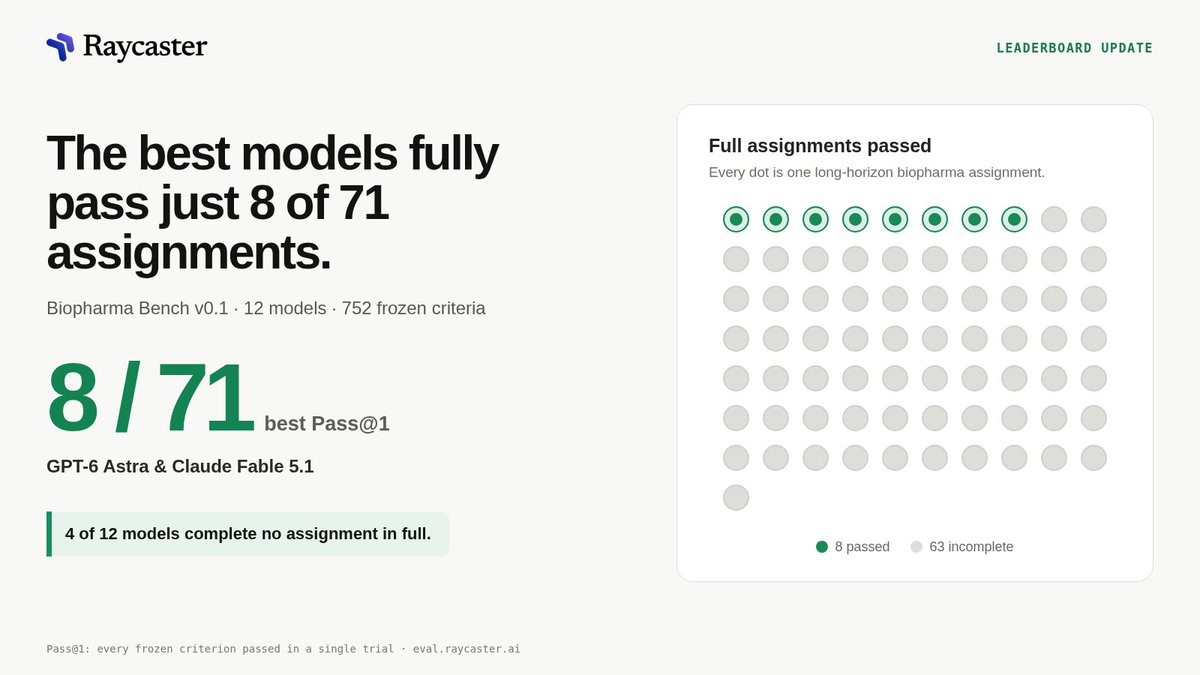
GPT-6 Astra and Fable 5.1 lead Biopharma Bench v0.1, but each fully passes 8 of 71 assignments
A post announcing five new runs says both models had high average partial scores on the long-horizon assignments.
TLDR
A post announcing five new runs for Biopharma Bench v0.1 says GPT-6 Astra and Fable 5.1 lead the benchmark. Each fully passes only 8 of 71 long-horizon assignments (11.3%), despite high average partial scores.
Combined views
3.1K
1 Source, first seen ago
likes