AI
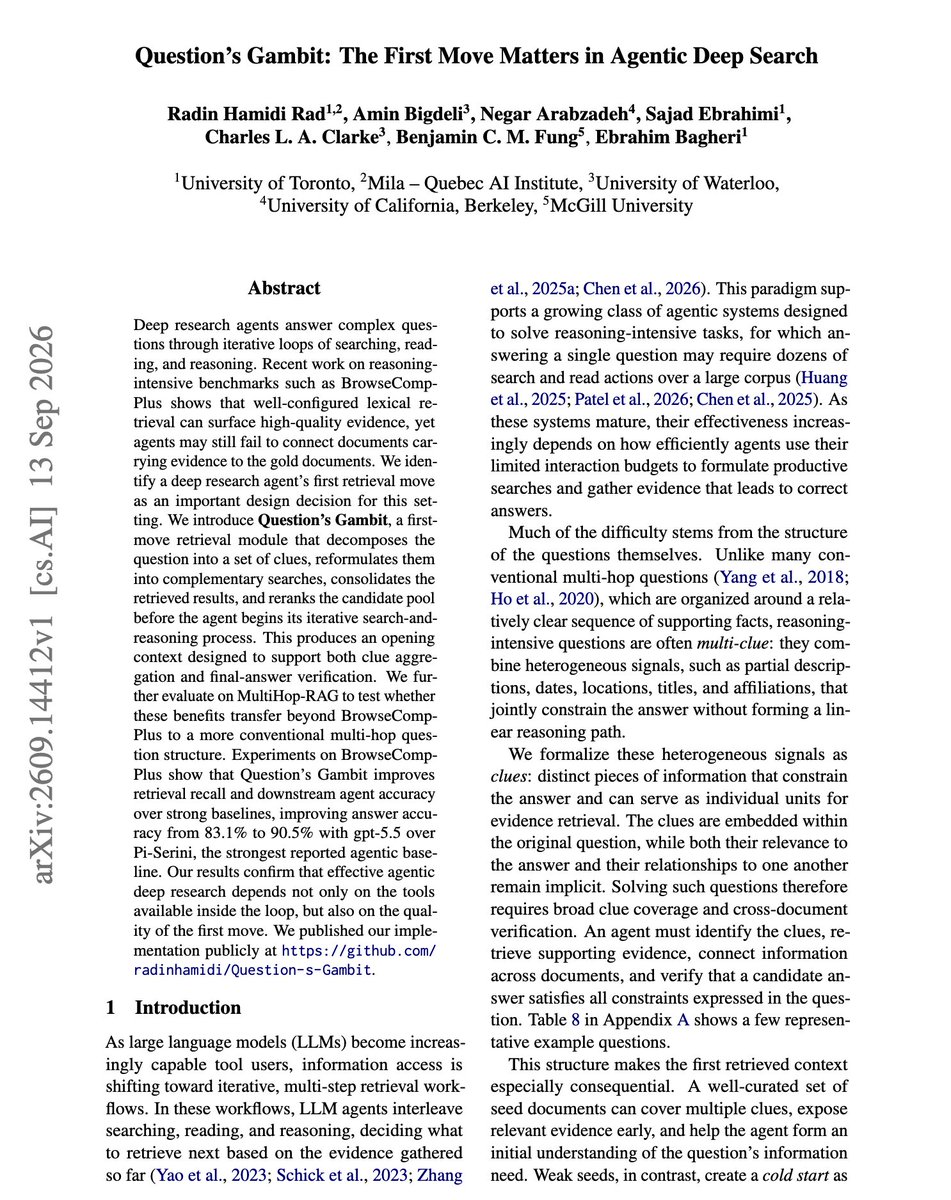
Question's Gambit reportedly lifts GPT-5.5 from 83.1% to 90.5% on BrowseComp-Plus
A post summarizing the paper says the method assembles ranked search results before an agent's search loop begins. The reported GPT-5.5 gain used the same retriever and agent loop.
TLDR
A post describing the paper says Question's Gambit runs once before an agent's search loop: it splits the question into clues, creates complementary searches, pools the results and reranks them. The agent starts with those results already in context. The post reports BrowseComp-Plus gains from 83.1% to 90.5% for GPT-5.5, 68.1% to 79.0% for GPT-5.4-mini and 71.4% to 76.9% for DeepSeek-v4-pro. The method costs 2.3–5.3 extra tool calls per question. The post also describes an error analysis in which only 3 of GPT-5.5's 79 remaining errors involved never retrieving the target document. The other 76 occurred later, when the agent previewed, opened or used the evidence.