• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
  • HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Report

    Verifying sampled shell commands can improve terminal-agent benchmark results

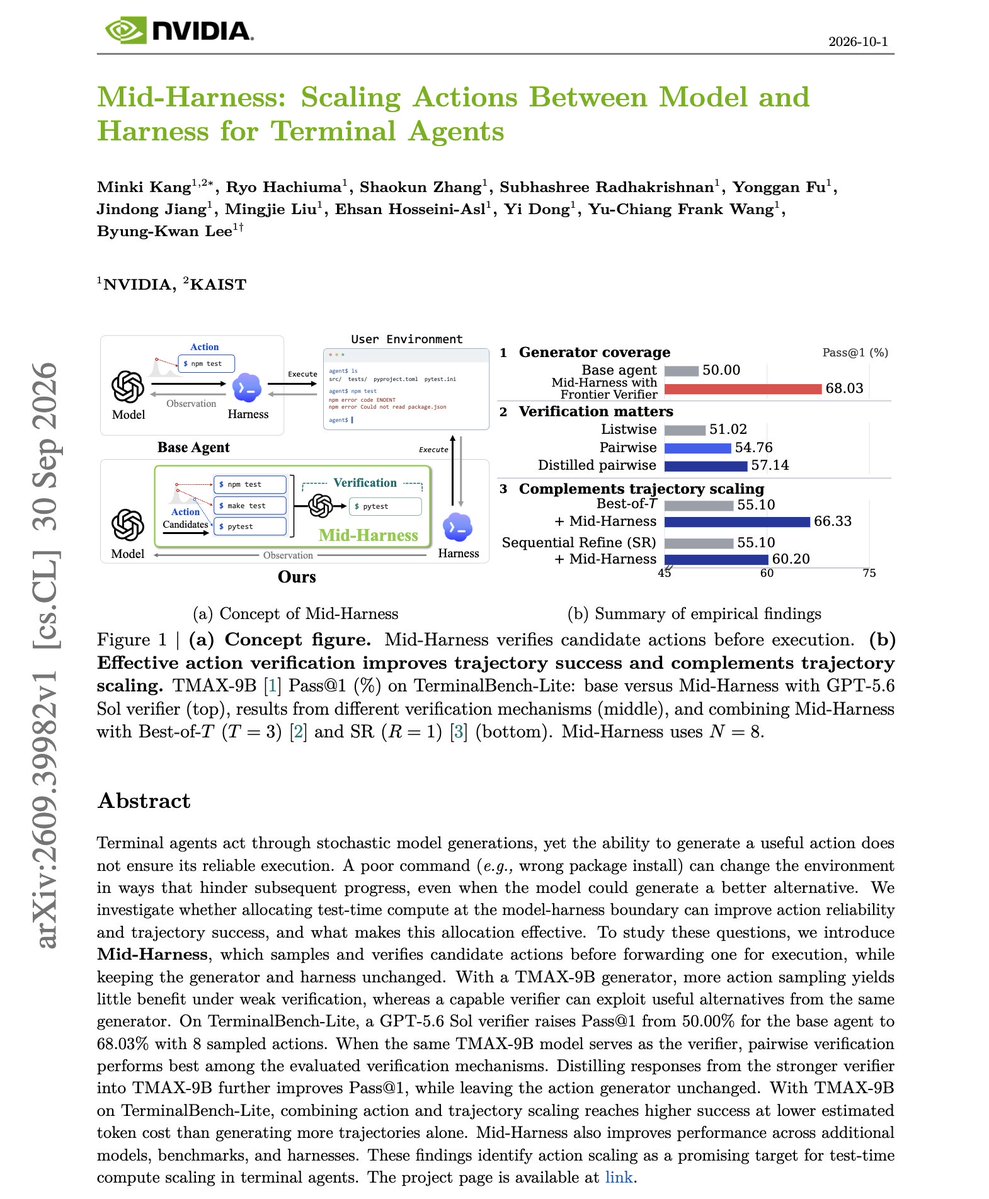
    A post describing an NVIDIA paper says TerminalBench-Lite Pass@1 rose from 50.0% to 68.0% with a GPT-5.6 Sol verifier choosing among eight sampled actions.

    EL
    1 Source, 1h ago, first seen 1h ago

    TLDR

    A post describing an NVIDIA paper says its Mid-Harness method verifies candidate shell commands before running one, without changing the generator or harness. With a GPT-5.6 Sol verifier choosing among eight sampled actions, TerminalBench-Lite Pass@1 rose from 50.0% to 68.0%. The post says extra samples added little with a weak verifier, while combining action and trajectory sampling reached higher success at lower estimated token cost than sampling full trajectories alone.

    Combined views

    387

    1 Source, first seen 1h ago

    Combined views

    387

    1 Source, first seen 1h ago

    20 reposts
    20 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Featured Source

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    1 Source

    @omarsar0RT @dair_ai: Banger paper from NVIDIA on test-time compute for terminal agents. The finding is that you should sample several candidate sh…1h

    1 Source

    @omarsar0RT @dair_ai: Banger paper from NVIDIA on test-time compute for terminal agents. The finding is that you should sample several candidate sh…1h
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet