• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    AI
    Announcement

    Perplexity’s models search PDFs, slides and scans without OCR

    Perplexity says embedding images and rendered pages directly preserves tables, figures and layout that text extraction drops.

    Aravind SrinivasAS
    Omar KhattabOK
    Connor ShortenCS
    10 Sources, ,

    TLDR

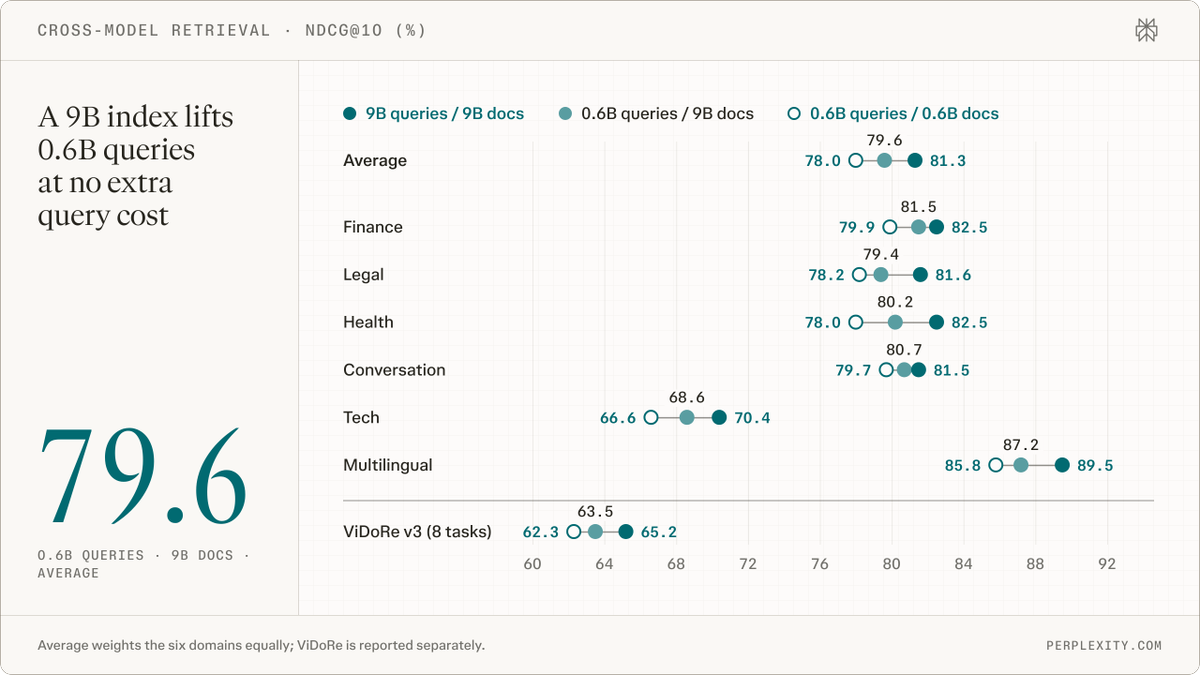
    Perplexity says its models embed images and rendered pages directly, allowing PDFs, slides and scans to be searched without OCR. The company says its 9B and 0.6B models share an embedding space after distillation from one 18B teacher. It claims queries using the 0.6B model on a 9B-indexed corpus lift ViDoRe v3 from 62.3% to 63.5% with no added query cost.

    Combined views

    19.1K

    10 Sources, first seen 1h ago

    Combined views

    19.1K

    10 Sources, first seen 1h ago

    328 likes
    1h ago
    first seen 1h ago
    328 likes
    56 comments
    97 saves
    37 reposts
    Featured Source
    56 comments
    97 saves
    37 reposts

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Sentiment

    Positive——Negative

    Summary

    Not enough discussion yet.

    No sentiment analysis available yet.

    Today's Rank

    #4

    Today's Rank

    #4

    10 Sources

    Perplexity@perplexity_aiBoth sizes are distilled token by token from one 18B teacher, so they share one embedding space. A corpus indexed with the 9B model can be searched with 0.6B queries. That lifts ViDoRe v3 from 62.3% to 63.5% with no added query cost.1h
    Bo@bo_wangboanother release from us, we probably built the strongest late interaction retriever you can find ever, anywhere on earth. we trained a massive 18B colbert model for text retrieval, image retrieval and document screenshot retrieval, then distilled it to a 9B colbert, and a 0.6B colbert. Since they from the same teacher, so naturally have shared token embedding space. So you can use 9B offline indexing, 0.6B online search, or use 9B on strong chips and 0.6B locally. Remind 0.6b includes a vision tower as well! pplx-embed-v2-context, late both out, Dense will be soon. These will marks our new gen or retriever suite.1h
    Antoine Chaffin@antoine_chaffinNew company, new team, same frontier results & same open license Happy to announce the release of our new embedding model family More than just an upgrade in performance, the models are now multimodal, multi-vectors, and use a shared embedding space to allow cross-model querying1h
    Aravind Srinivas@AravSrinivasWe’re open-sourcing pplx-embed-v2-late, multi-vector embeddings for text and images, 9B and 0.6B, in one shared embedding space. You can use these to index multimodal data with 9B, and query on device with 0.6B. This also enables you to search over PDF pages with no OCR. And scores 92.4% on MADQA, 64% on BrowseComp+. Weights available on @huggingface now.1h
    Connor Shorten@CShorten30RT @antoine_chaffin: New company, new team, same frontier results & same open license Happy to announce the release of our new embedding mo…1h
    Omar Khattab@lateinteraction(un)perplexingly strong late interaction models27m