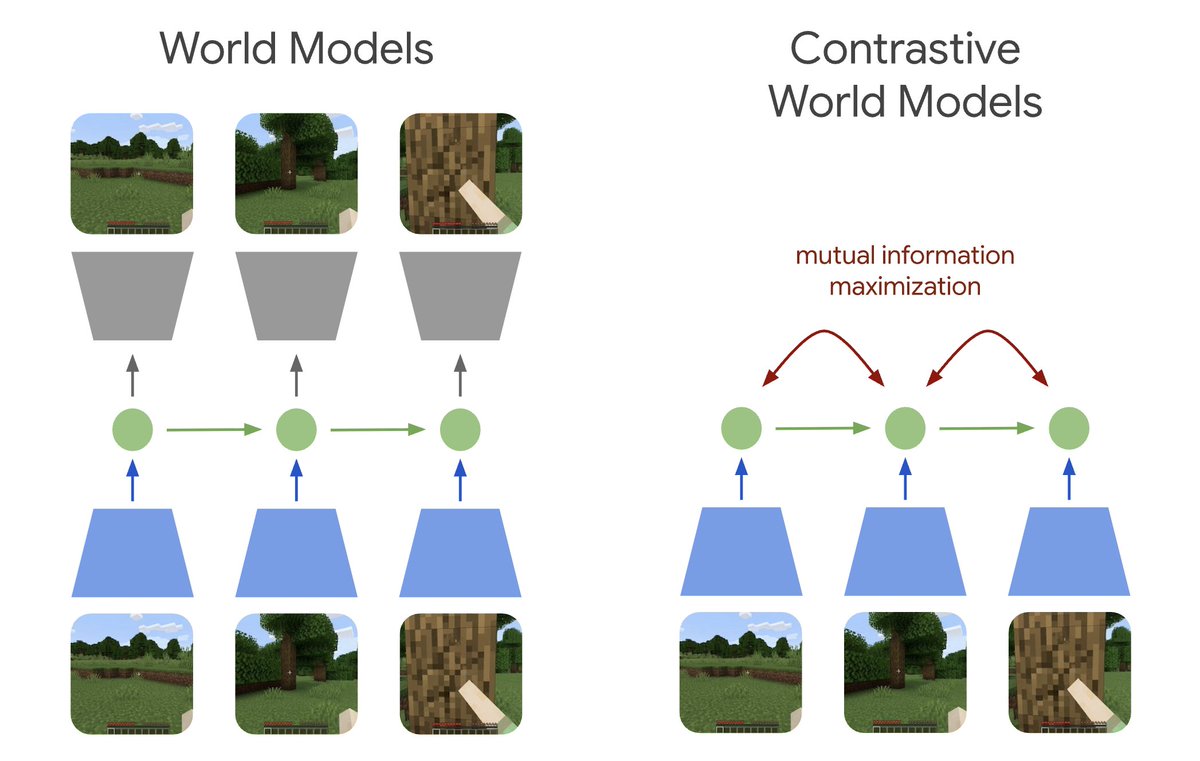
Contrastive World Models aim to learn without predicting pixels
The team behind the approach claims more robust representations and says removing the pixel decoder makes training more efficient.
TLDR
The team introducing Contrastive World Models says it trains latent states—internal representations—to maximize the information they share with future observations, without a decoder or pixel reconstruction. It claims substantially more robust representations and more efficient training, and describes the approach as general, with minimal assumptions.
Contrastive World Models aim to learn without predicting pixels
The team behind the approach claims more robust representations and says removing the pixel decoder makes training more efficient.